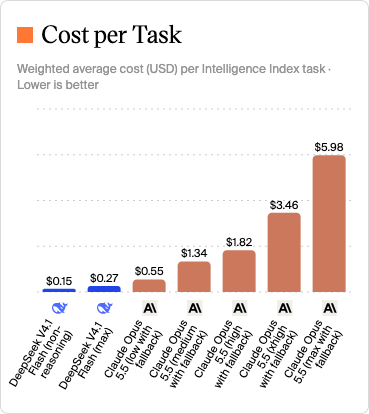
I have been using DeepSeek 4.1 Flash for about a month, heavily, across a dozen projects. It is super capable, and orders of magnitude cheaper than the "frontier" models. When I'm mid-session, if I don't look at the model name, I honestly could not tell you if I'm using DeepSeek or Opus. Whether it's our conversations, the work, or the speed, I don't notice a difference. I don't care that there is no 4.1 "Pro". I treat this like a frontier model because it behaves like one. I'm coming at this from my subjective usage experience, but you can see more complete benchmarks here if that floats your boat.

So why aren't the frontier labs freaking out right now? China is going to eat their lunch. They may be a month or two behind Anthropic/OpenAI, but these distilled Chinese models can handle the same workloads.
Sure, they stole Claude's training, and Anthropic stole it from other people. I'm not getting into the whole who-owns-whose-data debate, because most developers aren't thinking like that. They're just trying to get the most bang for their buck.
Good Enough Changes How You Work
Today's models are now good enough for high-quality unattended tasks. Chasing the latest and greatest is silly. It is fun to see the new Fable capabilities, but the tasks we throw at them are usually ridiculous (maybe even insulting) if you believe in LLM sentience. It's like asking a math PhD to organize the files on your desktop.
With my OpenCode Go sub of $10/month, DeepSeek is basically unlimited. This has completely changed my way of developing. There is no shame now in spinning up mindless tasks, or exploratory UI monkey testing. And sure, go ahead and reorganize your desktop files. That will cost $0.003 instead of $1. I have rarely exceeded $1 in expected costs in a session. I try to keep my sessions tight, but sometimes they run for most of a day.
I even lean on 4.1 Flash for complex planning and research. For occasional critical tasks, I sometimes pull in Opus 5.5 to do a final code review, which will catch a few edge cases. Then I have DeepSeek execute the fixes. Even when I call up Opus or GLM (which seems to be drinking the same Chinese Kool-Aid as DeepSeek), it's less about quality and capabilities and more about getting new eyes on a problem.
Cache Magic
DeepSeek shrank the KV cache by roughly 437x compared to their V1 model. Holding that cache in GPU memory is one of the biggest costs of running long coding sessions. That's how my all-day sessions stay under a dollar.
It must be better for the environment too. Using Claude almost feels wasteful, and not just on cost: its caching means DeepSeek must be using less water and electricity. This cache magic is also how Opus 5.5 quietly got its own efficiency boost.
Yes, I have frontier subscriptions. My work provides Claude, Cursor, and others. I'm not nickel-and-diming here. I'm thinking more about long-term planning, sustainability, and democratizing access to high intelligence. This is a game changer.
These wins are lost on the tech industry, which thinks that if you're not paying top dollar, it's not worth it. FAANG wants to spend the most money for the highest intelligence. Forget it if it's unethical, expensive, or bad for the environment or the economy. This is dog-eat-dog capitalism. This leads to people having crazy setups to load balance a dozen Claude Max subs, and complaining when they can't get more.
And to the self-hosters out there, the economics of 4.1 Flash mean self-hosting is not worth it. If saving money is your goal, you will never recoup the costs. But if your concern is privacy, just wait. These cache optimizations are coming to you, and this cache magic will soon run entirely locally. Even now, 4.1 Flash is technically self-hostable, even if not practically so. Any day now.