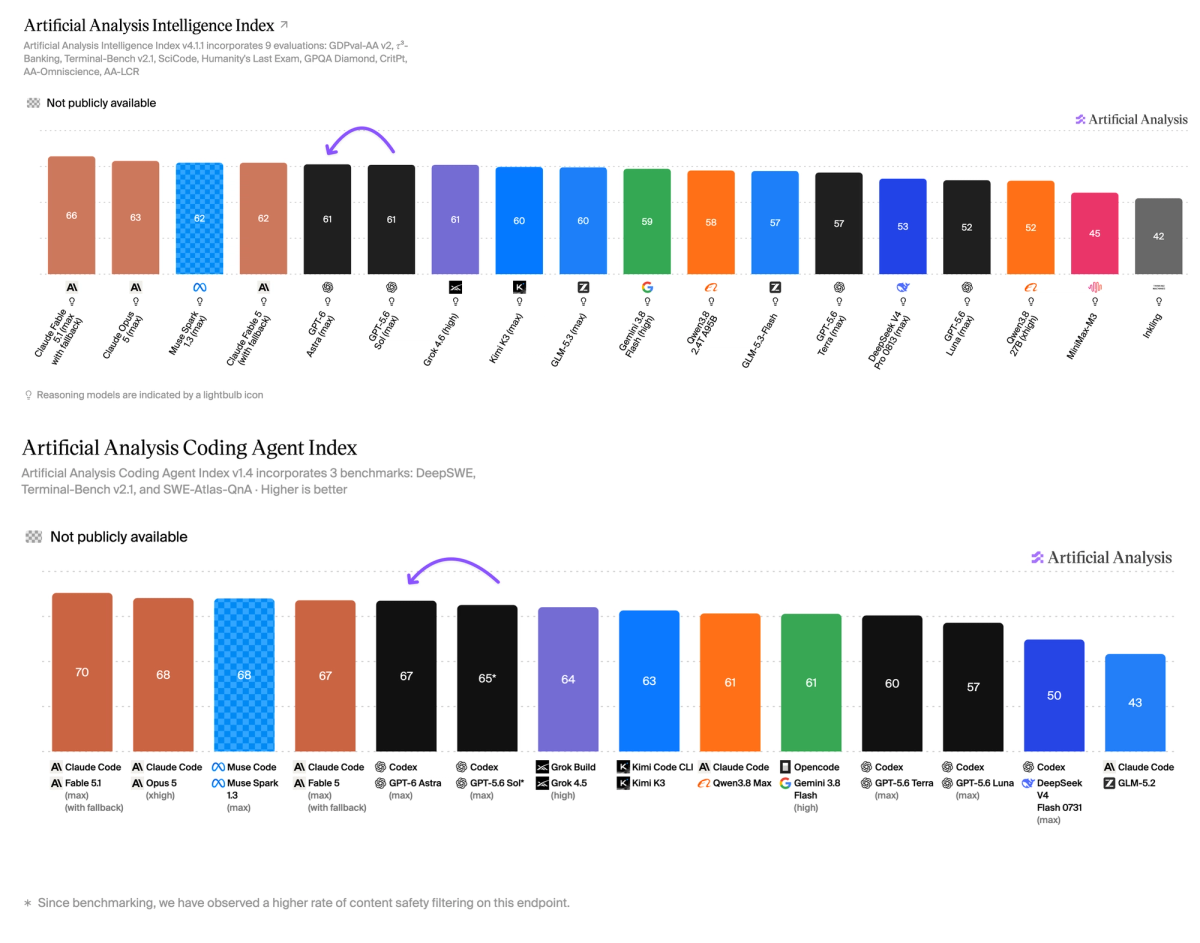
GPT-6 Astra makes significant gains in the Artificial Analysis Coding Agent Index, scoring equal to Fable 5 at lower cost. In the Intelligence Index, it uses fewer tokens than GPT-5.6 Sol for similar performance, but this is outweighed by higher prices
Pricing is 2.5x GPT-5.6 Sol’s current prices across the board, up from $4/$20 to $10/$50 per million input/output tokens, with the same 90% discount for cache reads and 25% premium for cache writes.
We see distinct stories across our two flagship Indices. In the Artificial Analysis Coding Agent Index, GPT-6 Astra equals Fable 5 at less than half the cost, driven by significant token efficiency gains. In the Artificial Analysis Intelligence Index, GPT-6 Astra is more token efficient than its predecessor for similar performance, but this is offset by the price increase.
Artificial Analysis Coding Agent Index - key takeaways:
➤ Rivals top models: In Codex, GPT-6 Astra scores 67 in the Index - approximately equal to Claude Opus 5 and Fable 5 in Claude Code, and Muse Spark 1.3 in Muse Code. Fable 5.1 in Claude Code leads the Index with a score of 70.
➤ 70% more token efficient than GPT-5.6 Sol: GPT-6 Astra sees a substantial improvement in token efficiency, using one third of the tokens compared to GPT-5.6 Sol (max) in the Codex harness, and one fifth of the tokens of Claude Opus 5 (xhigh). Various effort levels of the model occupy the Pareto frontier of token efficiency.
➤ Leads Coding Agent Index cost efficiency frontier: At max effort, GPT-6 Astra costs about the same as GPT-5.6 Sol (max) while scoring 2 points higher on the Index. Per task, the model is less than half the cost of Claude Fable 5, for the same score.
Artificial Analysis Intelligence Index - key takeaways:
➤ Sits beside GPT-5.6 Sol in Intelligence: GPT-6 Astra scores equal to GPT-5.6 Sol in the Index at 61. This is 5 points lower than Claude Fable 5.1 (max with fallback). The model also trails Meta’s newly released Muse Spark 1.3 (max).
➤ ~10% fewer output tokens, offset by price increase: GPT-6 Astra defines a new Pareto frontier for Intelligence Index vs Output Tokens per Task - with a ~10% reduction in token use at max effort compared to GPT-5.6 Sol. However, due to the 2.5x increase in price, the model is 75% more expensive per task than its predecessor at max effort.
➤ Hallucinates half as much as GPT-5.6 Sol: GPT-6 Astra sees a large jump in AA-Omniscience, our knowledge and hallucination benchmark. This is driven by a significant decrease in hallucination rate from 92% to 51% at max effort. Unlike some models, this improvement does not come at the cost of accuracy - Astra increased accuracy by 4 points at the same time.
➤ ~80 point gain in AA-Briefcase Elo: GPT-6 Astra improves ~80 points in AA-Briefcase, our frontier long-horizon knowledge work evaluation. Models are tested on multi-week projects, with many linked tasks and thousands of source files. Astra sees a significant increase in both rubric scores and Analytical Quality Elo in AA-Briefcase compared to its predecessor. In the other direction, we observe a reduction in Presentation Quality Elo, where GPT-5.6 Sol (max) still leads all models.
➤ Mixed progress on other evaluations: The model sees a 6 point gain in Humanity’s Last Exam, a long-standing evaluation with emphasis on mathematics, science, and humanities. This is offset by a drop of ~80 Elo points in GDPval-AA v2 - a benchmark we adapted from OpenAI’s dataset measuring economically valuable tasks across 44 occupations. We also observe 2-3 point regressions on other evaluations across a mix of capabilities, including reductions in τ³-Banking (customer support), SciCode (Python problems in a scientific domain), and AA-LCR (long context reasoning over large documents).
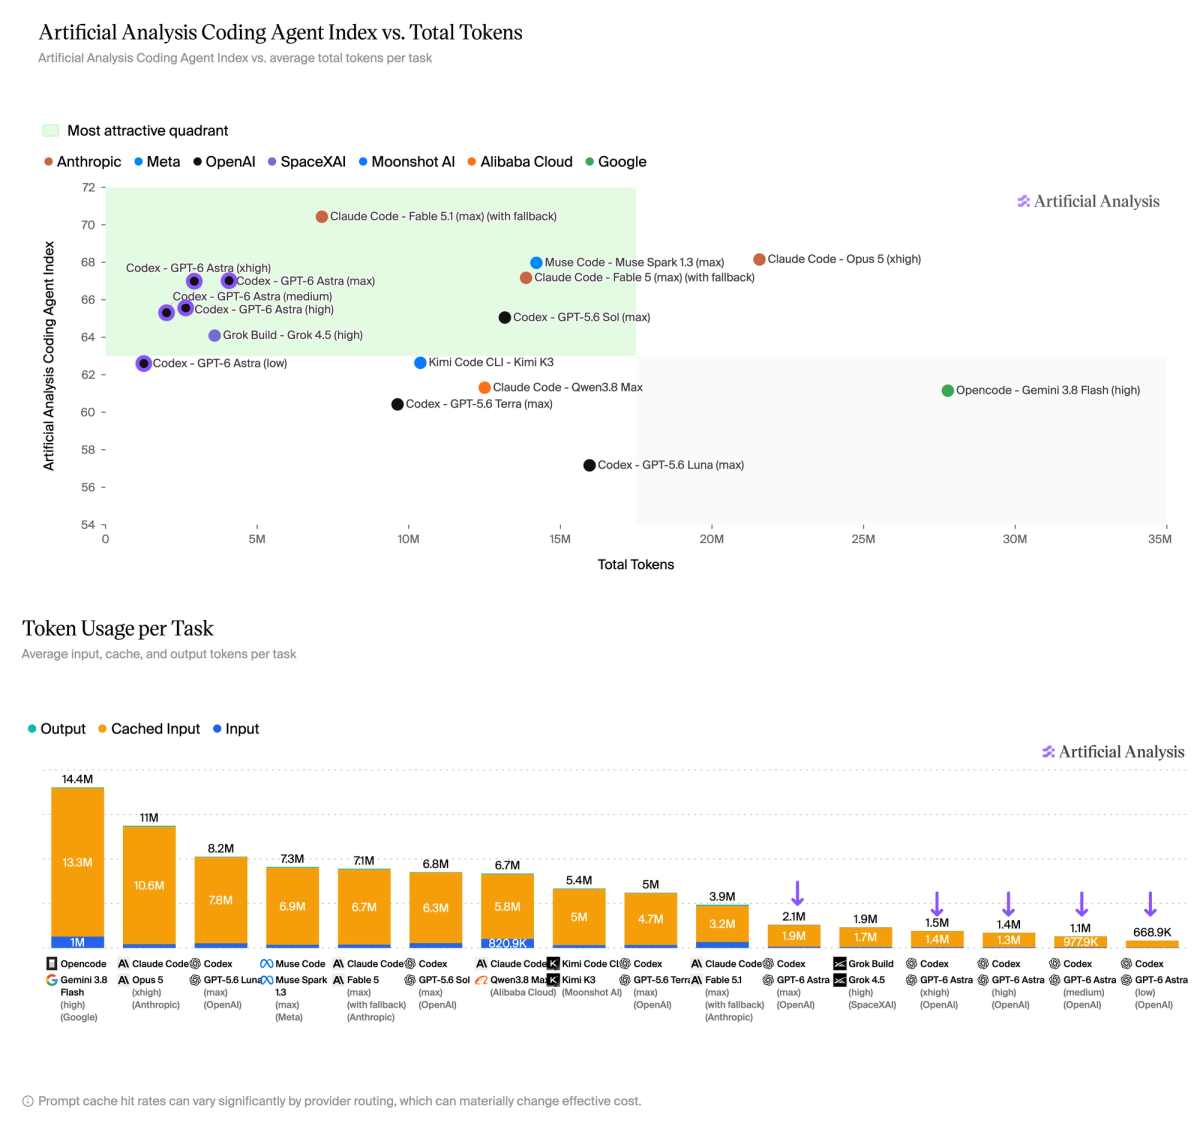
Coding Agent Index cost improvements are driven by token efficiency, with a ~3x token reduction at max effort compared to GPT-5.6 Sol (max).
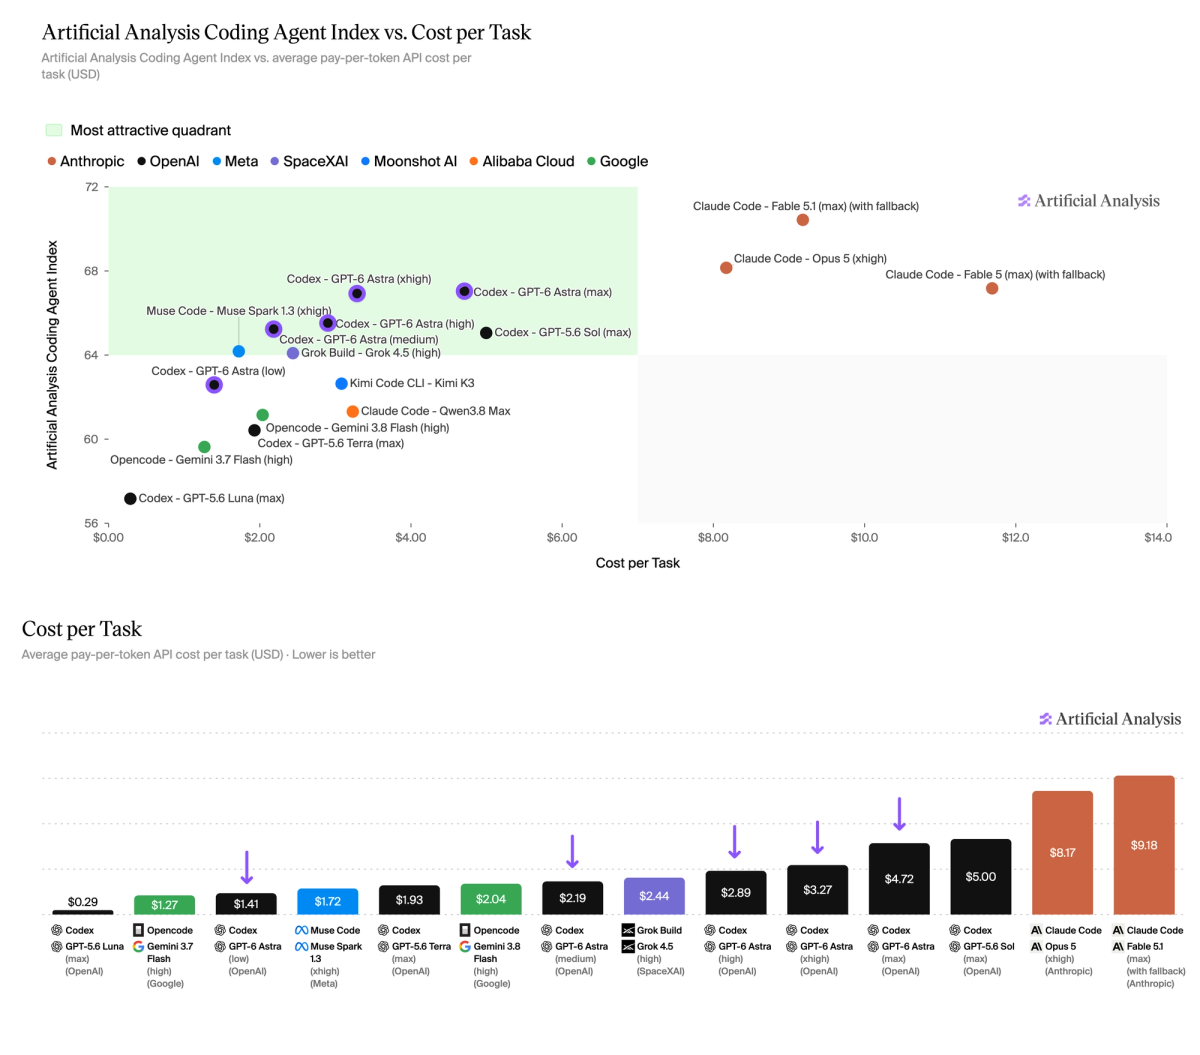
GPT-6 Astra is on the Pareto frontier for Coding Agent Index vs Cost per Task, with its max effort setting costing about the same as GPT-5.6 Sol (max) while scoring 2 points higher in the Index.
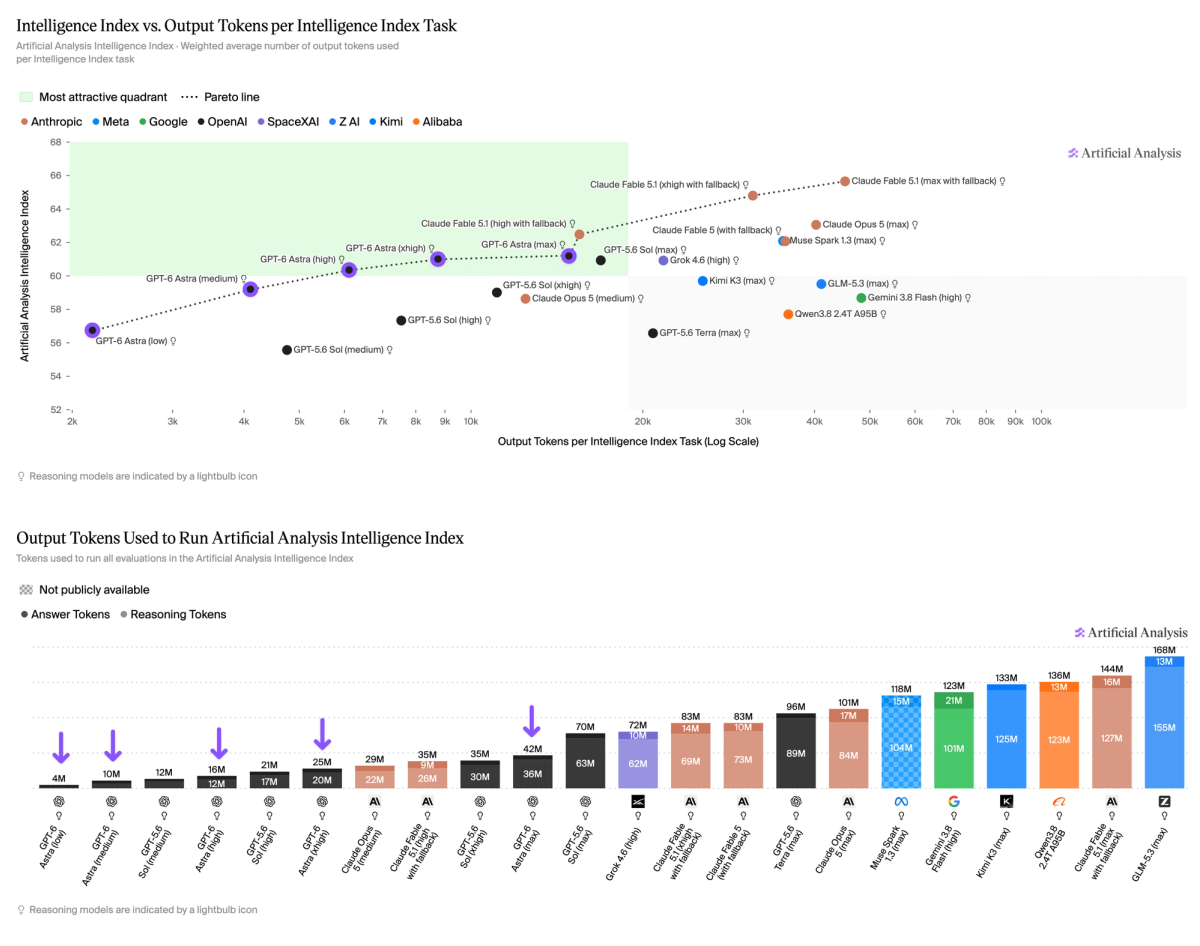
GPT-6 Astra defines a new Pareto frontier for Intelligence Index vs Output Tokens per Task - with a ~10% reduction in output tokens at max effort compared to GPT-5.6 Sol.
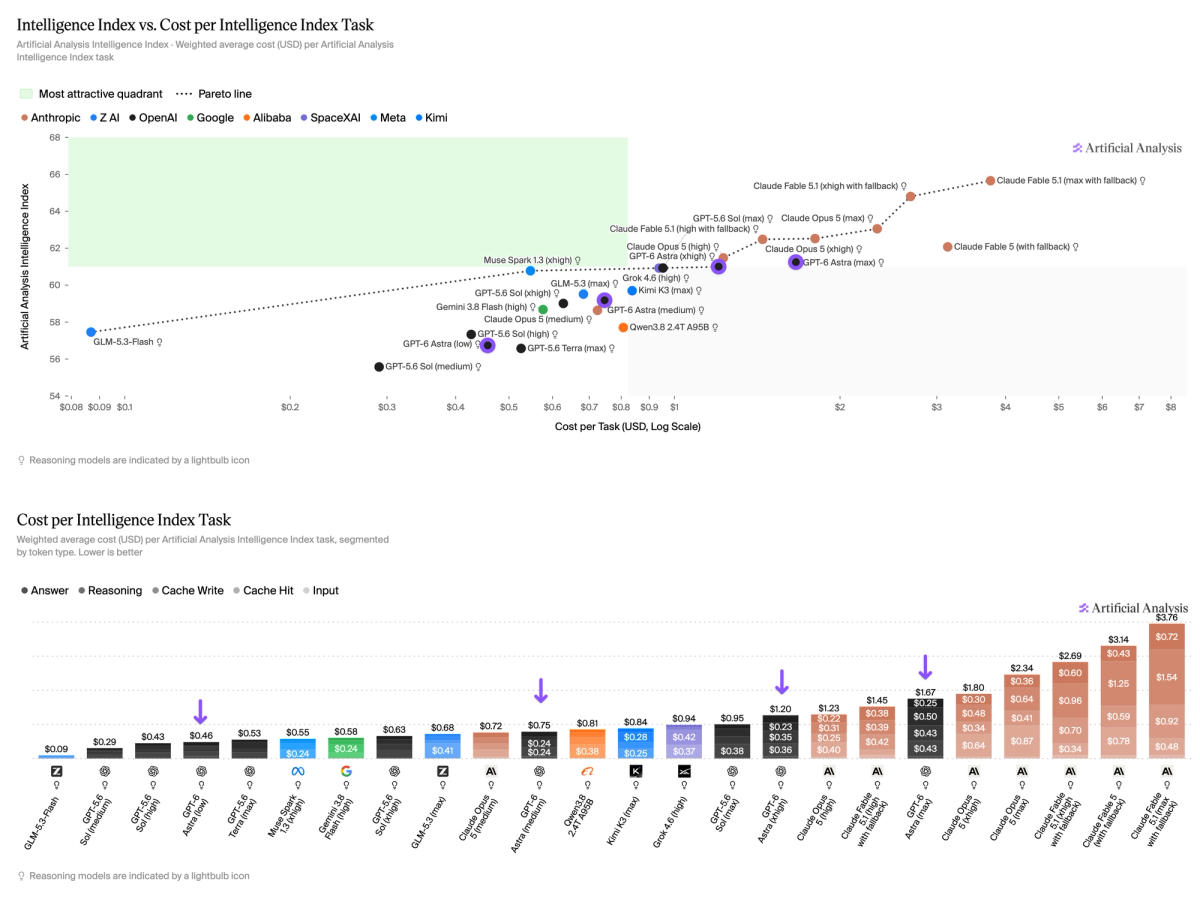
GPT-6 Astra is 75% more expensive than GPT-5.6 Sol at max effort, and largely sits behind its predecessor on the Intelligence Index vs Cost per Task frontier. This is driven by a 2.5x increase in price, partially offset by a reduction in token use.
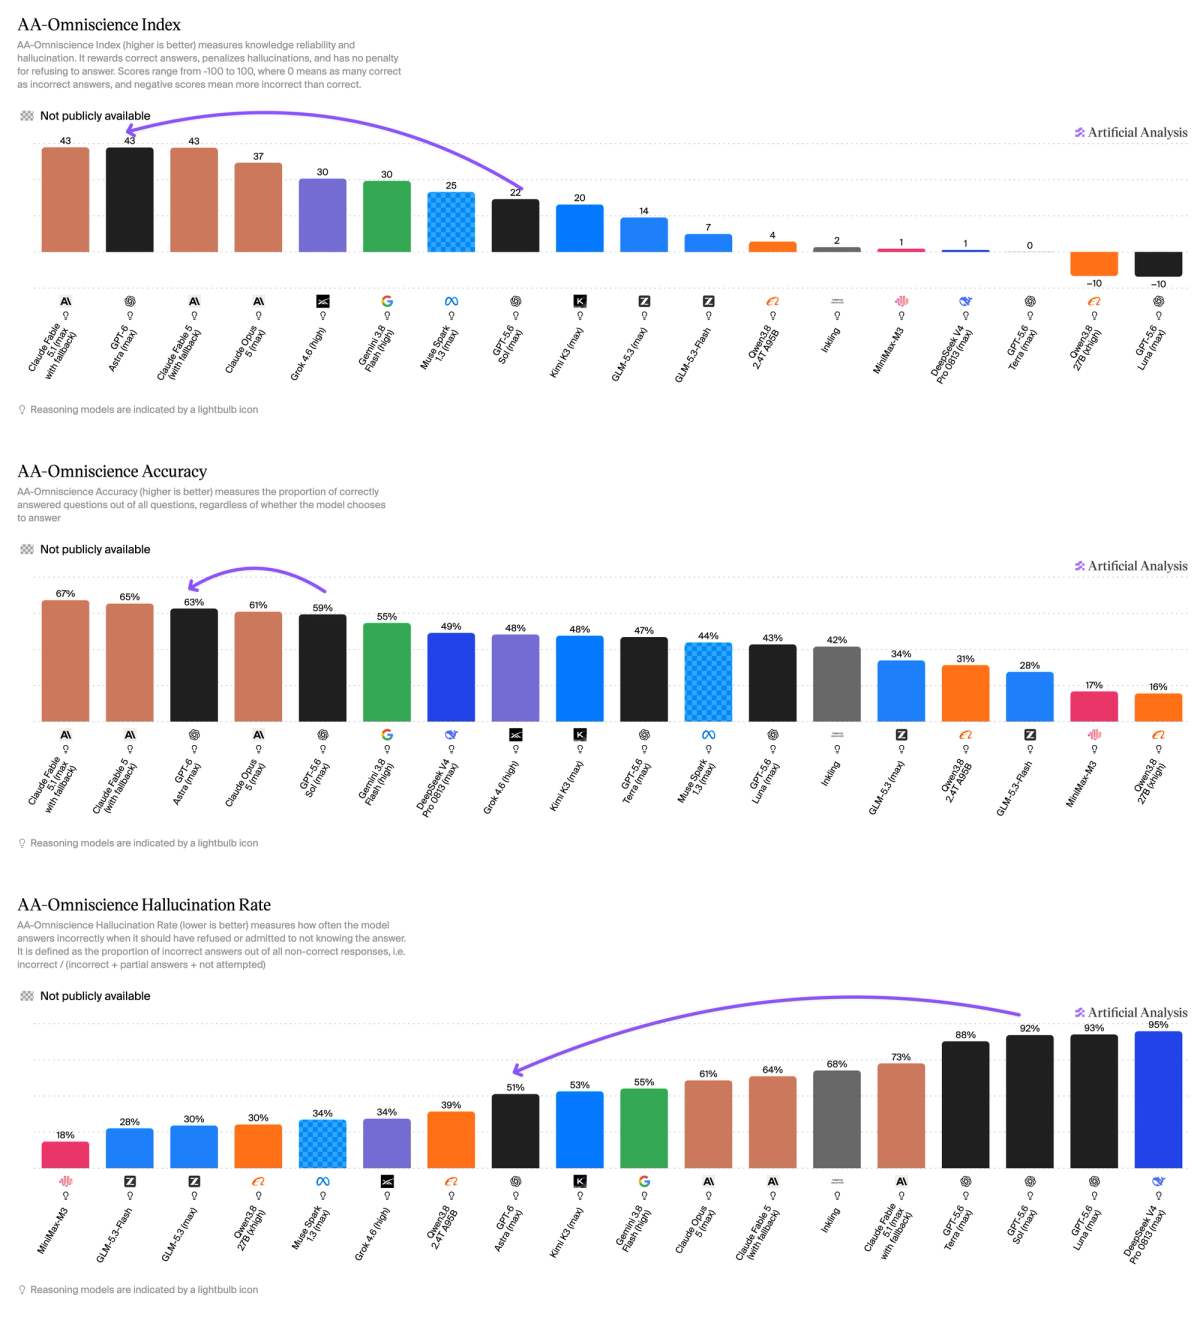
GPT-6 Astra sees a large jump in AA-Omniscience, driven by a significant decrease in hallucination rate from 92% to 51% at max effort, alongside a modest increase in accuracy.
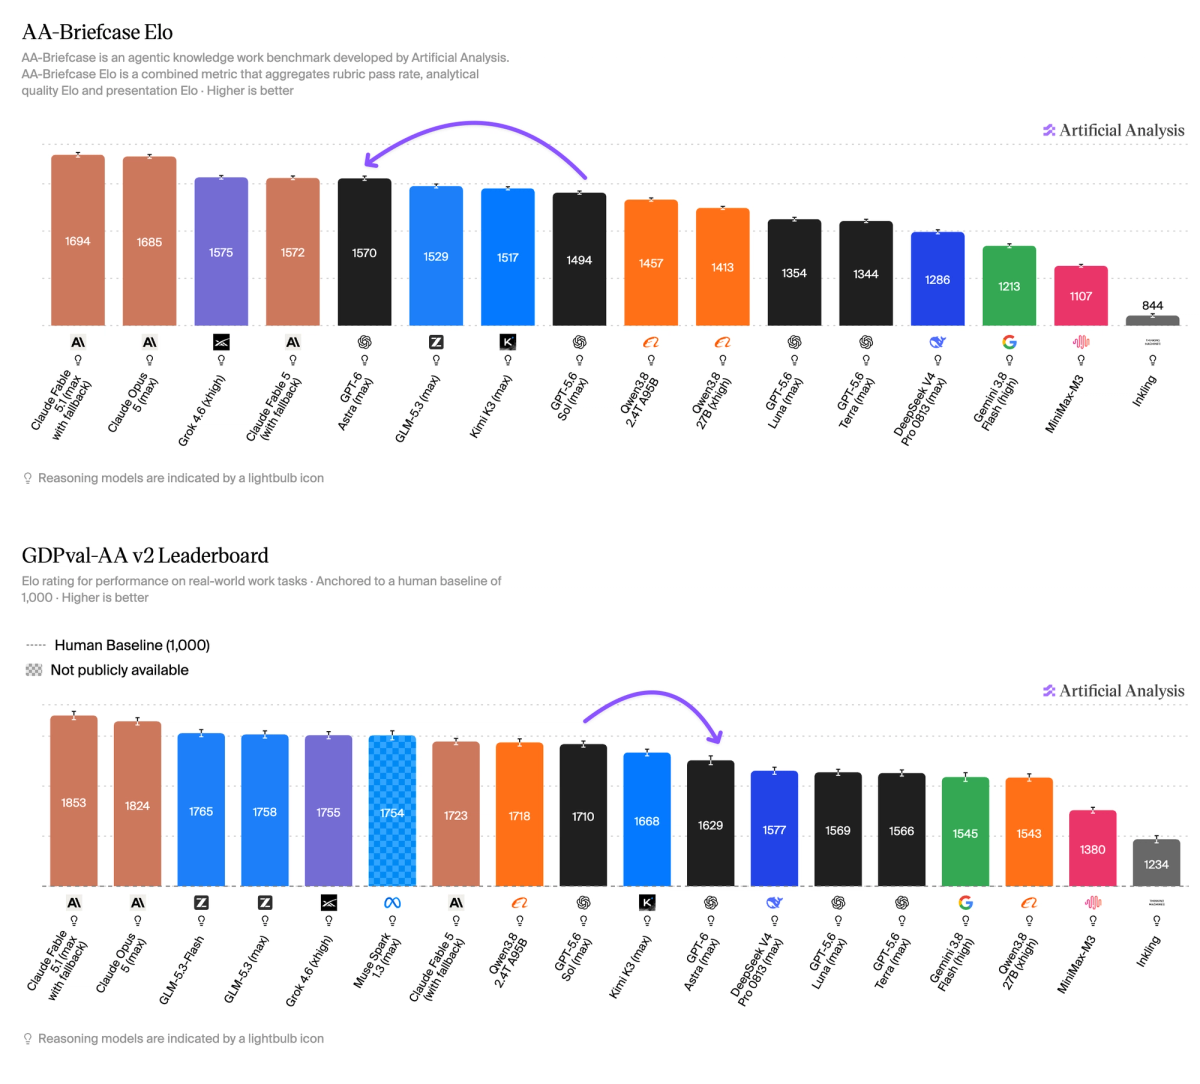
The model shows mixed progress in agentic knowledge work - improving ~80 points in AA-Briefcase, but regressing a similar amount in GDPval-AA v2. In AA-Briefcase, Astra sees a significant increase in both rubric scores and Analytical Quality Elo, but a reduction in Presentation Quality Elo.
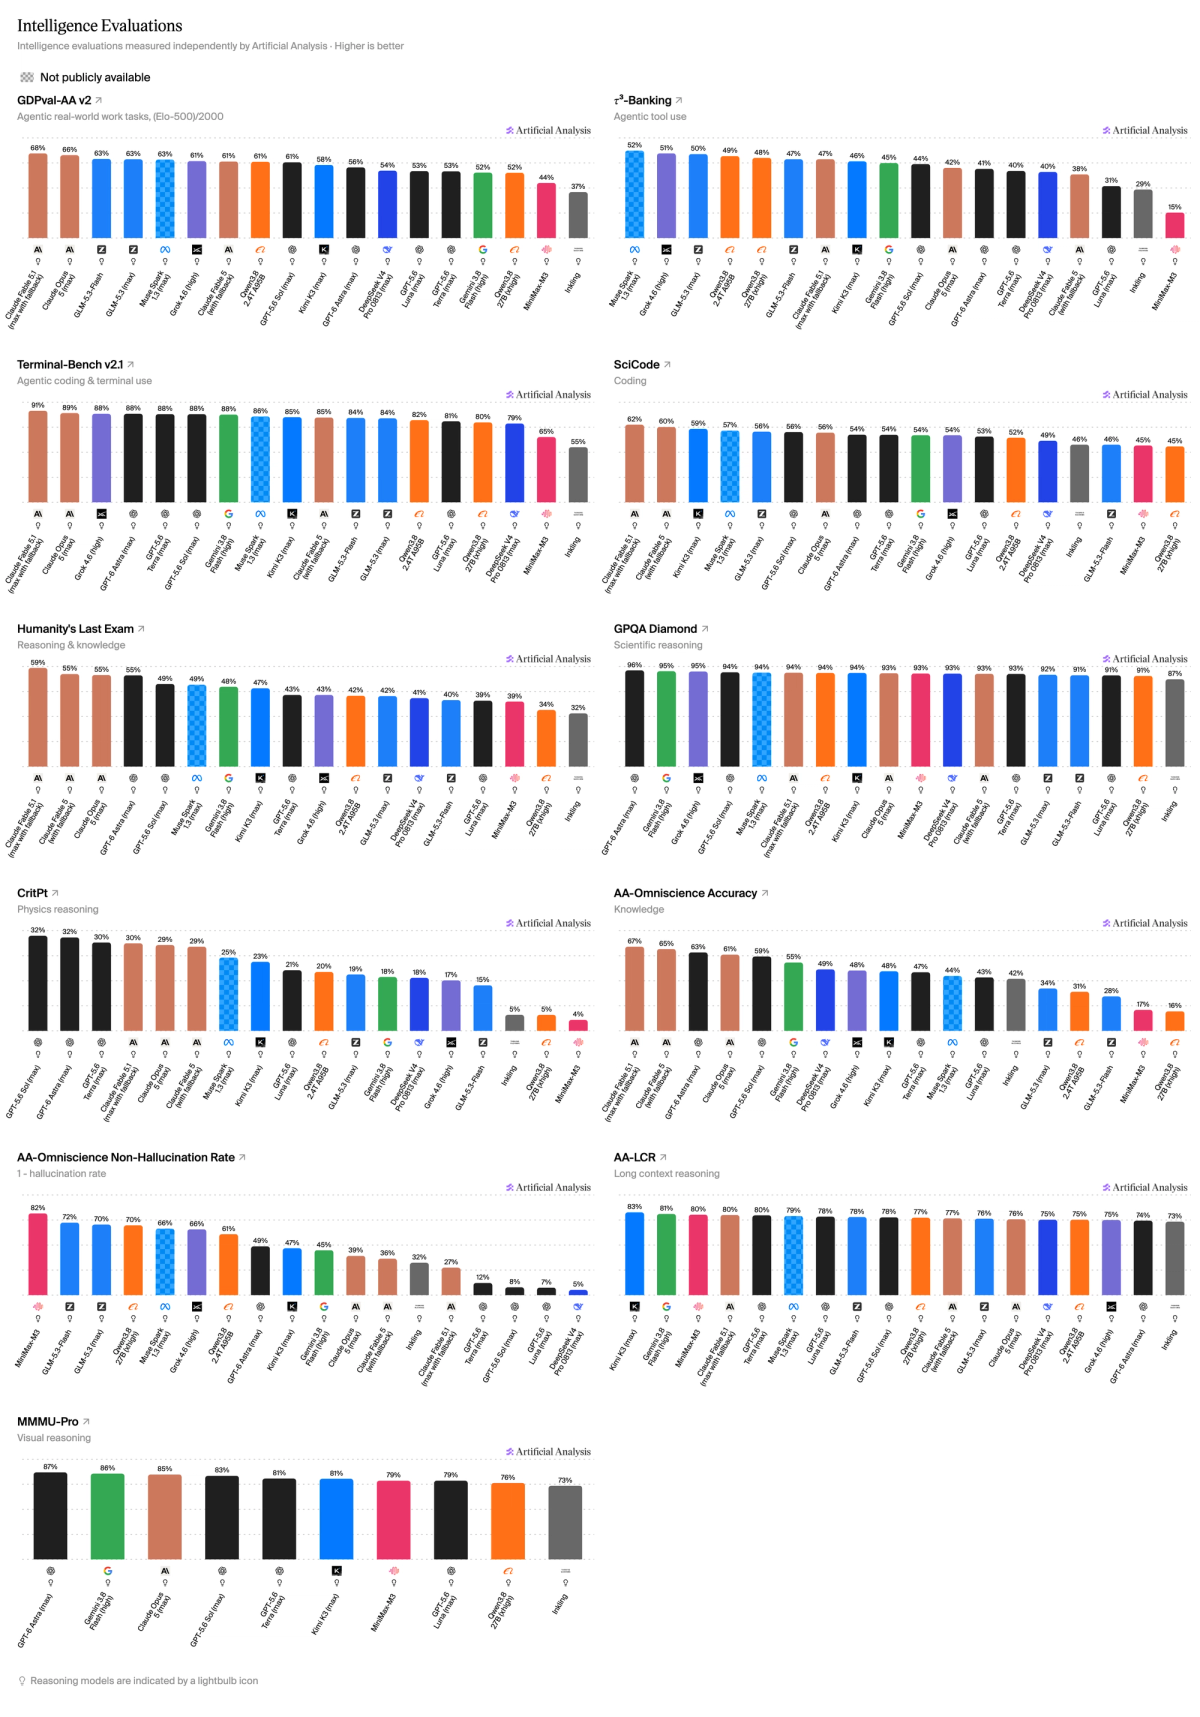
Breakdown of the individual evaluations in the Artificial Analysis Intelligence Index v4.1.1.
Compare GPT-6 Astra with other leading models at: www.artificialanalysis.ai