Ranked among the top tier of open-source models, Hy4 preview is built for real-world productivity tasks, delivering outstanding performance across coding, office work, and scientific research
Tencent has released and open-sourced Tencent Hy4 preview, a next-generation large language model with 770B total parameters and 49B active parameters, and a context window exceeding 1M tokens. It demonstrates outstanding capabilities on real-world productivity tasks spanning coding, office work, and scientific research.
Hy4 preview is now available as an open-source model and can also be accessed globally through WorkBuddy and CodeBuddy, as well as Yuanbao, ima and other Tencent products. Users can try the model directly through these applications, or connect to it via API through Tencent Cloud TokenHub and OpenRouter.
Upon launch, Hy4 preview will be available for free on WorkBuddy and CodeBuddy for two weeks. Free access to Hy3 on both platforms has also been extended until September 30.
Hy4 preview was expanded significantly in model size, context length, and data volume, and the advances in both pre-training and post-training have led to a major leap in overall intelligence, placing the model among the top tier of open-source models.
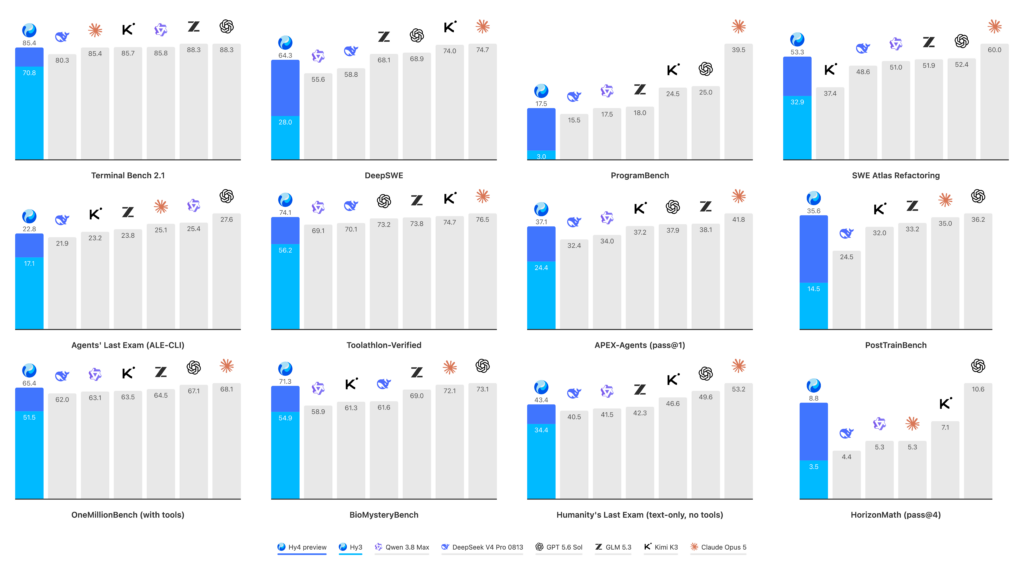
Hunyuan continuously works in deep co-design with products such as CodeBuddy and WorkBuddy, optimizing the real-world user experience across productivity scenarios. In a blind evaluation conducted internally by Tencent involving 163 experts and 203 engineering tasks, Hy4 preview scored an average of 2.99 out of 4.00, slightly ahead of GLM-5.3 (2.92/4.00) and Kimi K3 (2.94/4.00).
Designed for productivity, Hy4 preview was developed using high-quality training data co-created with Tencent experts across software engineering, gaming, finance, security, and other domains, as well as through deep co-design with products such as WorkBuddy. This has helped drive significant improvements across a wide range of real-world productivity tasks.
In software engineering, Hy4 preview delivers stronger understanding, planning, debugging, and validation capabilities for long-context development tasks, while also enhancing the visual quality and interaction experience of front-end development.
In office productivity and analytical scenarios, the model demonstrates a significantly stronger understanding of complex working environments and enhanced financial analysis capabilities. It has also been optimized for data analysis and cross-document collaboration, supporting the full workflow from information processing through to the creation of documents, spreadsheets, and presentations.
In game development, Hy4 preview can generate a playable prototype from a single natural-language request, and work effectively with game engines. Developers can then continue refining complex game projects through multi-turn interactions.
In scientific research, Hy4 preview demonstrates stronger capabilities in understanding, reasoning through and solving complex research problems, with notable improvements across areas including AI research and development, molecular dynamics simulation, condensed-matter physics and fundamental mathematics.
Notably, Hy4 preview also contributed to its own development process, participating for the first time in the automated optimization of training methods, data strategies, evaluation frameworks, and low-level operators. The model proposed approaches, ran experiments, and iterated based on the results, with the resulting code, logs, and feedback feeding into subsequent rounds of exploration. This established an early-stage recursive self-improvement loop.
Hy4 preview has also autonomously analyzed bottlenecks in its inference system and carried out multiple rounds of optimization on areas such as operator fusion and communication optimization. These improvements increased end-to-end throughput by 31.8% compared with the baseline, with consistent gains across different context lengths and concurrency levels. This demonstrates the model’s ability to autonomously optimize its own inference infrastructure.
Hy4 preview continues to offer cost efficiency, helping make advanced AI more widely accessible. API pricing is set at USD 0.834 per million input tokens, USD 2.501 per million output tokens and USD 0.042 per million tokens for cache hits.
Through a preview-first approach, followed by official releases, Hunyuan continuously incorporates real-world feedback into its research and development process, enabling its models to improve by solving real-world problems. The next batch of models in the Hy4 series is expected to roll out soon.