Amazon is buying massive quantities of books, scanning them for AI training data, and destroying them in the process.
A 404 Media investigation was able to reveal Amazon’s book buying operation, which hasn’t been previously reported, by placing a tracking device in a rare book we suspected would be acquired by an AI company for training data, and following it around the country to its final destination.
That final destination was an Amazon warehouse in Las Vegas, Nevada. Amazon employees who work at this location say all they do is receive massive shipments of printed books which they then cut the bindings off in order to scan the books more quickly. The printed book is destroyed in the process. The logo of the Amazon team that works at this warehouse, called VGT3, is a dinosaur, brandishing its teeth and with a book in its hands.
“Amazon purchases books through commercial channels to help develop and improve the products and services our customers use,” an Amazon spokesperson told me in a statement.
The world’s AI companies are constantly looking for, and spending extreme resources to locate, more material to train their AI models. With books, that sometimes means destroying them in the process, something that large parts of the public have spoken up against, and which we can now confirm Amazon is doing.
In July, I published a story about booksellers who reported a historical spike in sales starting in the past year. They suspected this spike in sales was due to AI companies acquiring any books they can in search of new training data. Printed books are valuable as training data because a lot of the text they contain is not readily available on the internet, which AI companies have already scraped. The data is also conveniently organized and, if the book was printed before 2022, is guaranteed to be free of AI-generated text, which can make any AI model that is trained on it worse via a recursive process called “model collapse.”
📖
Do you know work at a facility where you scan books? I would love to hear from you. Using a non-work device, you can message me securely on Signal at @emanuel.404. Otherwise, send me an email at [email protected].
These booksellers suspected AI companies were behind these large bulk purchases because of the high number of books they were buying, the seemingly random choice of books, and the fact that these buyers, unlike libraries and universities, did not seem price sensitive at all. But booksellers couldn’t say for certain who was behind the large purchases because the marketplaces where they sell their books keep the buyers anonymous. When an order comes in, a bookseller ships the sold books to a warehouse operated by the marketplaces, where books are sorted and then sent to the buyer.
In July, one bookseller told me they received a very large order of around 1,000 books on Biblio, one of these marketplaces. The seller agreed to put an Apple AirTag provided by 404 Media in one of the books included in this order so we could see where the book was going. And by extension, which company, AI or otherwise, was behind this massive order.
404 Media granted the bookseller anonymity because they worried sharing this information would harm their business. Biblio did not respond to a request for comment.
'})}}();The bookseller sent the shipment to Biblio, and it arrived at a California airport. It then traveled by plane to Milwaukee International Airport in Wisconsin. Later that day, the book traveled to a warehouse belonging to a specialized shipping and distribution company called Trifinity, right outside of Kenosha Regional Airport, about 30 miles south. The book remained there for about two weeks, at which point it began traveling west by what appeared to be a truck. I could see the book travel via the highway and spend a night over at a trucking travel center around Grand Junction, Colorado. The next day, the book arrived at its final destination, an Amazon warehouse called LAS8 in Las Vegas.
LAS8 is one of several large Amazon warehouses in the area, each with a different specialty. LAS7, right across the street, for example, is a fulfilment center, while LAS8 appears to mostly operate as one of Amazon’s “print on demand” operations, which will print and ship books to Amazon shoppers as they are buying them. Initially, I was confused about why the book would arrive there, but Amazon employees who work at this location and who discuss working conditions there with other Amazon employees online explain that the the north end of the LAS8 warehouse, where I saw the book arrived, housed a different Amazon operation with a different code: VGT3.
Many Amazon warehouses have unique symbols to represent that specific site. VGT3’s symbol, painted on the entrance to the site and inside, is of a Tyrannosaurus rex, the massive carnivorous dinosaur, with its mouth open, holding an open book.
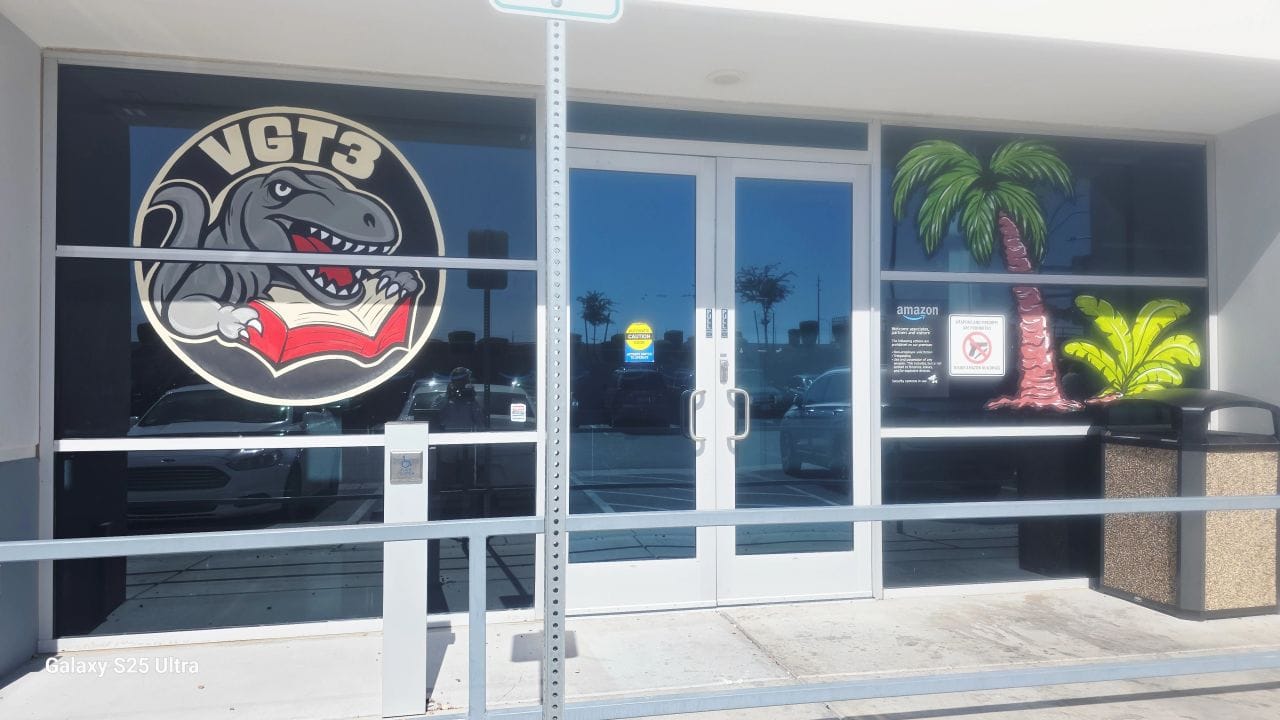
“I work at VGT3 here in Vegas, and all we do is scan books,” one Amazon employee wrote on a forum for Amazon workers. “Some are assigned to cut books, and others go to receive where they get books and scan the bar codes. We didn't have rates, but now we do, but it's not stressful.”
“Working at VGT3 is nice all we do is scan books,” another Amazon employee wrote. “It's so cool.”
I saw VGT3 employees online talk about how working in this operation is a good but boring job because workers do the same, easy, repetitive tasks all day. I also saw some discussion indicating that VGT3 jobs are desirable for this reason, and because the warehouse sometimes offered night shifts. Earlier this year, some employees expressed concerns that Amazon would shut down the site because they had worked through the books they had and weren’t getting enough shipments of new books, though the site is still operational today.
That employees are scanning the barcodes or ISBNs on books — a unique serial number given to every published book — before scanning their content gives further credence to another theory put forth by booksellers: AI companies are trying to methodically scan every printed book in the world by working through the list of ISBNs. One bookseller told me they suspected this was the case because the very large orders they were getting never included very rare books that do not have ISBNs.
Elsewhere online in 2024, booksellers who sell their books on Amazon said they received a spike in orders to be shipped directly to the VGT3 location for a customer named “Amazon FC.” This was so unusual given its size they suspected the orders were some kind of scam. An Amazon representative chimed in to say they checked and that the orders were legitimate.
Like other major tech companies, Amazon is developing its own large language models (LLMs). Amazon considers its family of models branded Nova to be “frontier” models, meaning it considers them to be competitive with other cutting edge LLMs from Google, OpenAI, and Anthropic. These models require massive amounts of training data in the form of human-written text. Internally, Amazon also used an AI coding agent called Kiro to develop its own software.
We first learned that AI companies wanted to scan millions of books for training data because of a lawsuit from book authors against Anthropic, which revealed Anthropic’s “Project Panama.” The goal of the project was to acquire books from commercial bookselling marketplaces, cut the spines off the books, and scan them. It’s possible to scan books without destroying them, but cutting the spine makes it cheaper and faster. Additionally, the judge in the lawsuit ruled it was fair use and not a copyright violation for Anthropic to scan a book for training data in part because it destroyed the original, printed copy. Essentially, it’s the customer’s right to take physical media and store it digitally, and destroying the original copy means that copy isn’t duplicated and resold, and isn’t cutting into the publisher’s business.
We’re not revealing the titles of the books included in the shipment we tracked, but they are rare, meaning there are not many copies of them in circulation. Sometimes that’s because not many copies of them were ever printed, and sometimes because they are in a foreign language not many people speak. As the bookseller who sold them told me, there are not many people in the world who would care about them in the same way people might care about the first edition of Oliver Twist, but that doesn’t mean they’re not valuable.
“There are different types of value,” the bookseller said. “There's monetary value, obviously, but there are a lot of other types of value. There's historical value, intellectual value, sentimental value. All sorts of things, and all of those the AI companies don't care about. They just want the content as a bunch of words strung together.”
Amazon provided its statement above but did not respond to questions about why it cut the books it scanned, how many facilities like this it has across the world, and their response to the backlash from people upset that AI companies are destroying books.