Last week, OpenAI announced the GPT-5.6 lineup, introducing the Sol, Terra, and Luna models. During the release stream, the team focused heavily on computer use, showing models capable of navigating and operating desktop applications. OpenAI highlighted UI agents and detailed 3D visualizations, but both depend on stronger visual understanding.
To measure their vision capabilities, we ran the models through our upcoming VLM benchmark, which we plan to release in the next few weeks. The benchmark covers common vision tasks, including detection, counting, OCR, and data extraction. In this post, we take a closer look at how GPT-5.6 performs across each of them.
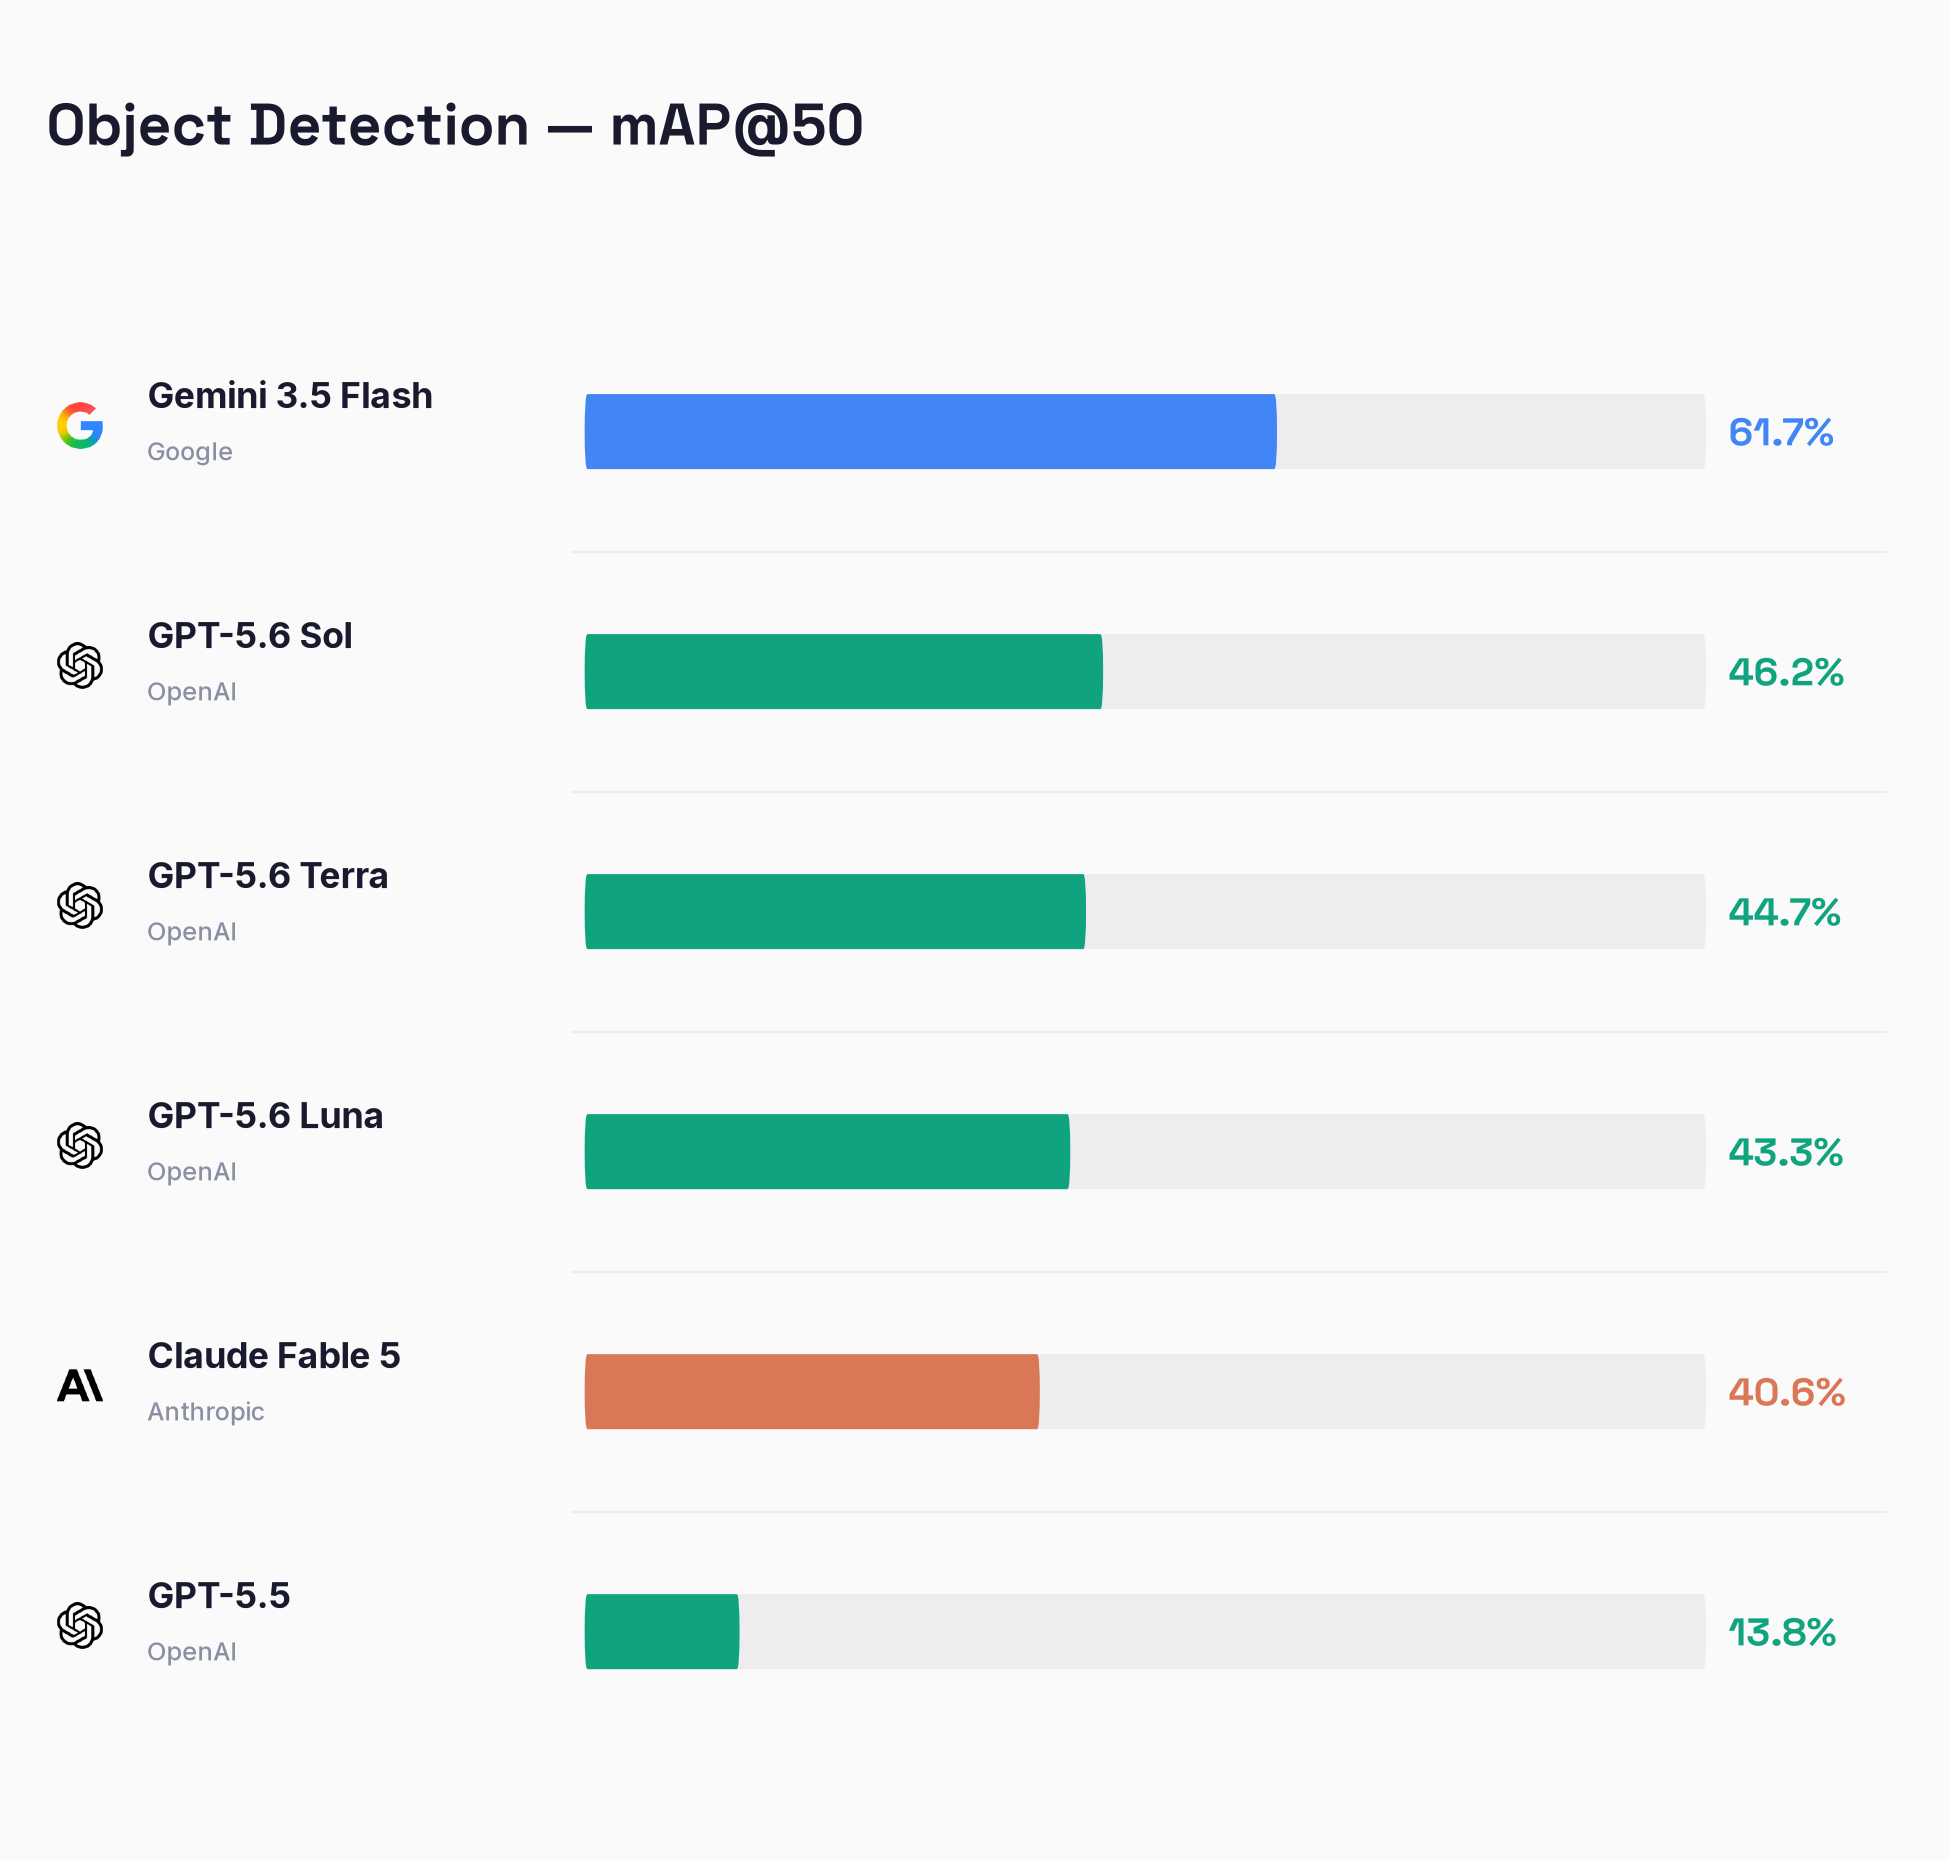
Sol is clearly the best vision model OpenAI has released so far. The jump is especially visible in object detection and counting, where GPT-5.5 was far behind the strongest VLMs. Terra and Luna are not as strong as Sol, but both show meaningful progress over GPT-5.5.
Test Sol, Terra, and Luna in Roboflow Playground and compare their results with models such as Claude Fable 5 and Gemini 3.5 Flash across the same vision tasks.
Object Detection
Detection is where GPT-5.6 shows the clearest jump. GPT-5.5 scored 13.8 mAP@50 in our benchmark, while Sol reached 46.2. Terra and Luna followed closely at 44.7 and 43.3, moving object detection from a major weakness to a practical capability.
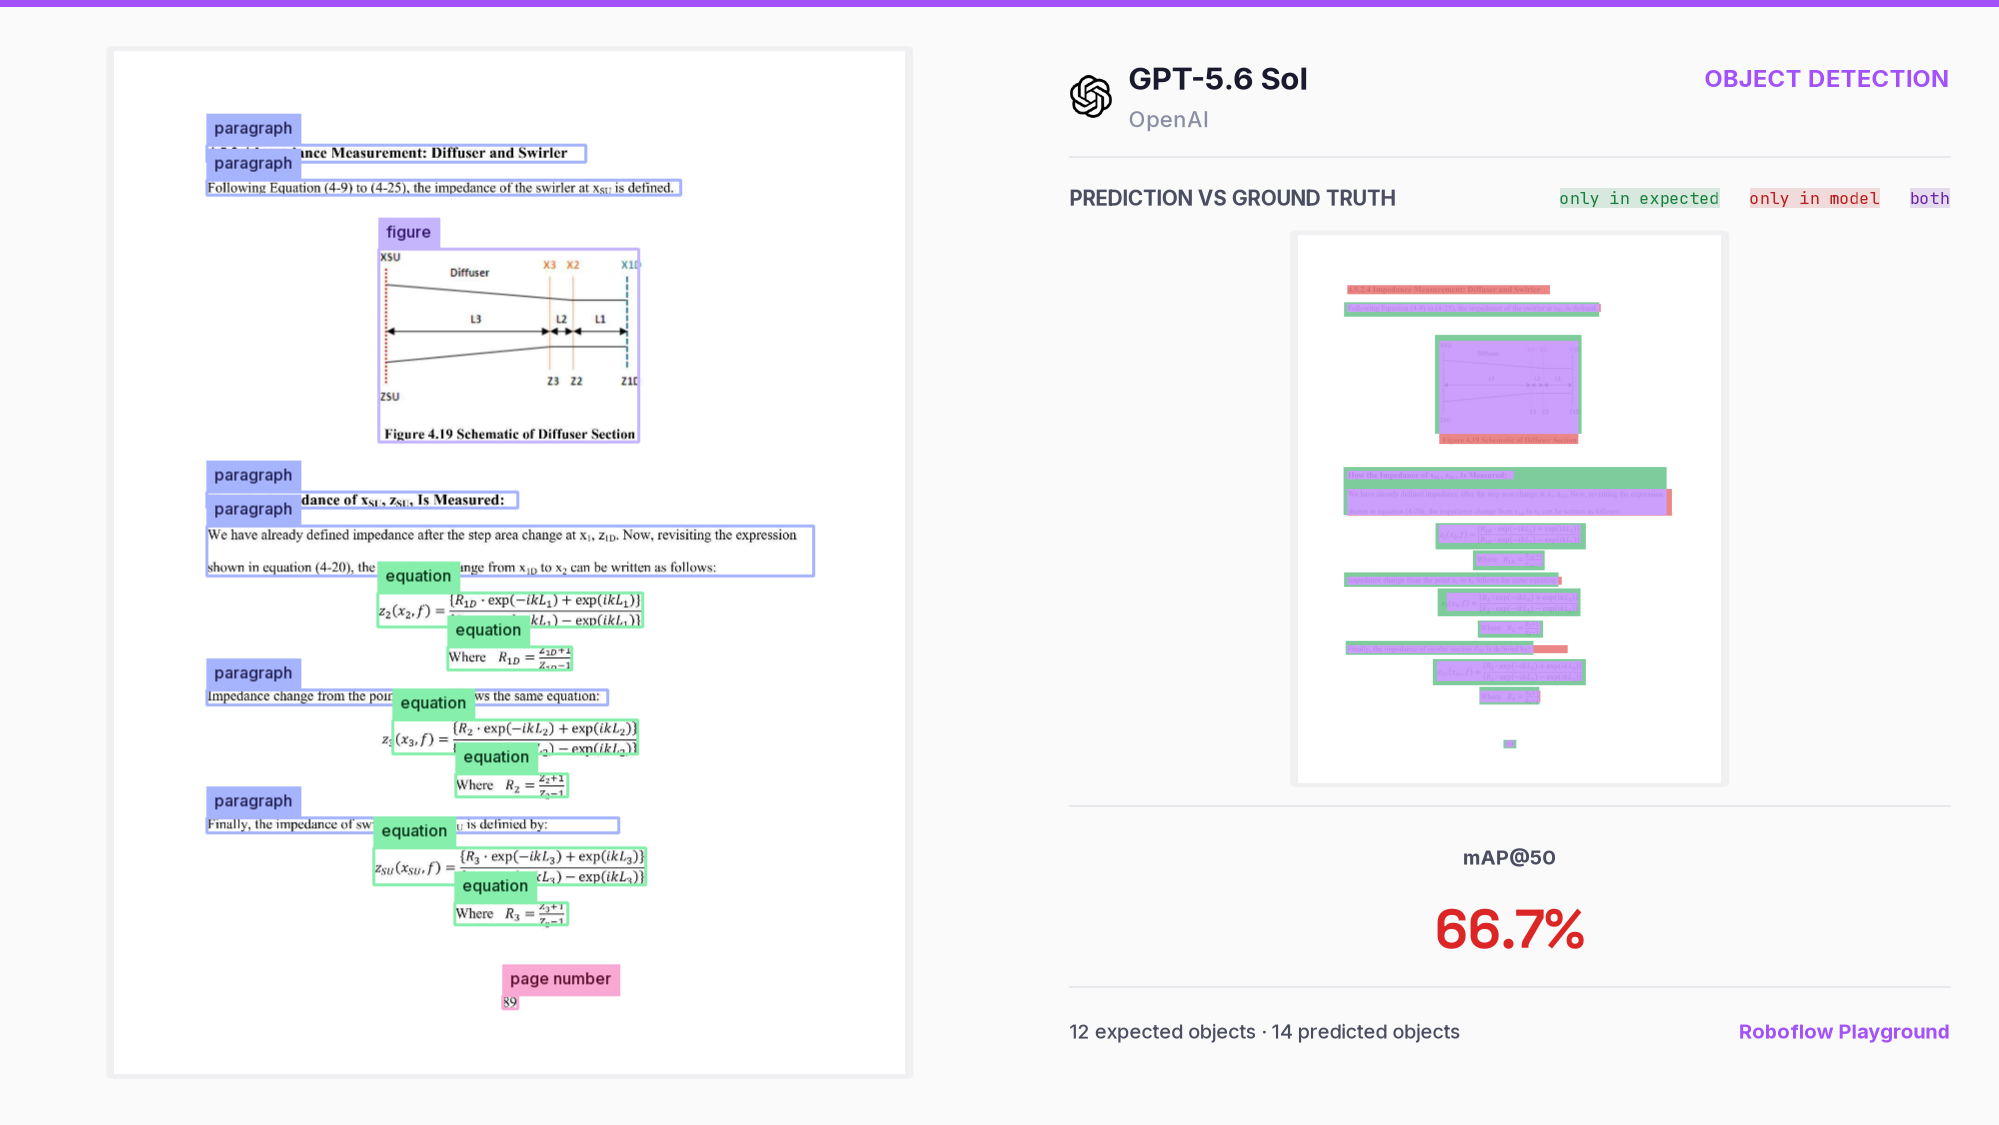
Document layout detection is one of the clearest strengths of GPT-5.6. Sol handled titles, paragraphs, tables, images, and signatures well. Many document workflows start with locating the relevant parts of a page before OCR or data extraction begins.
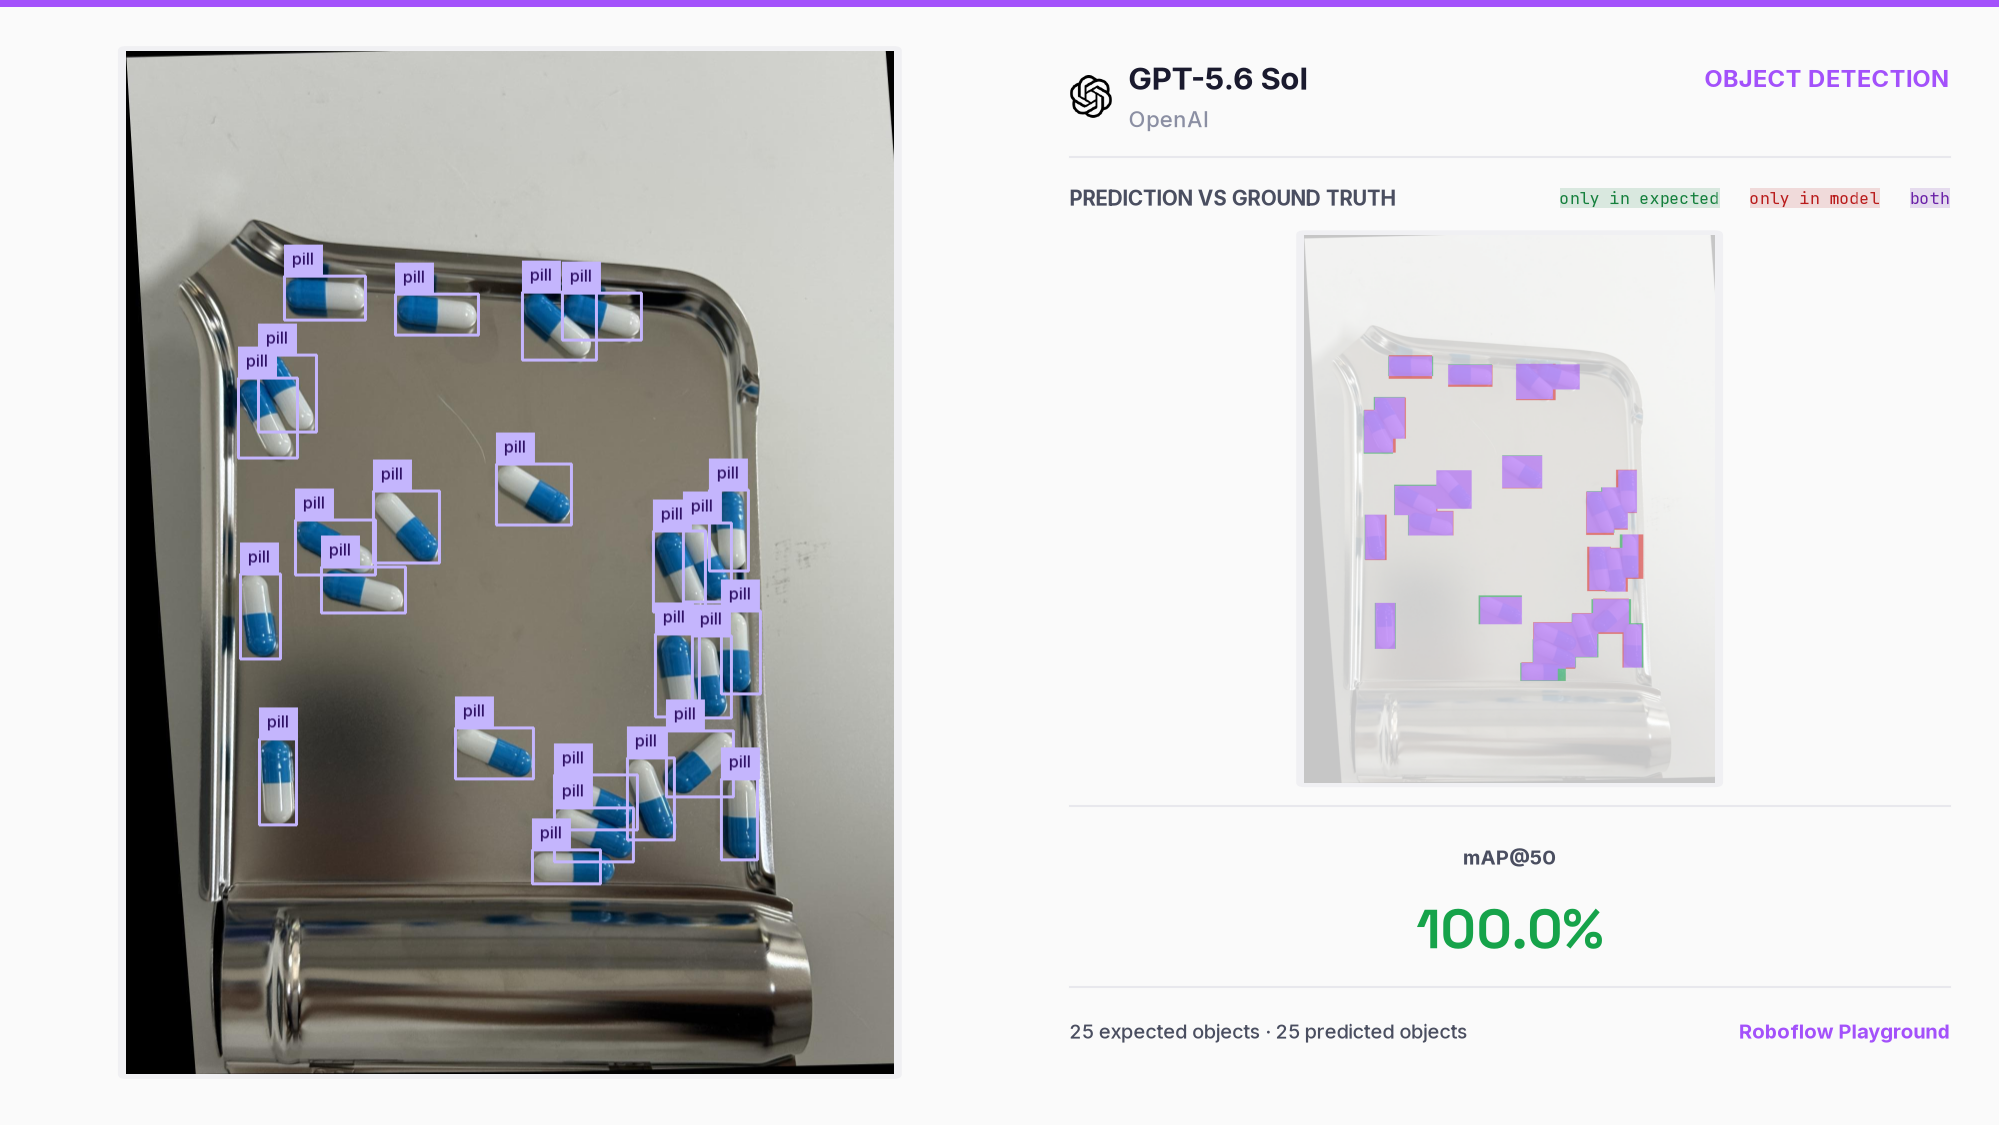
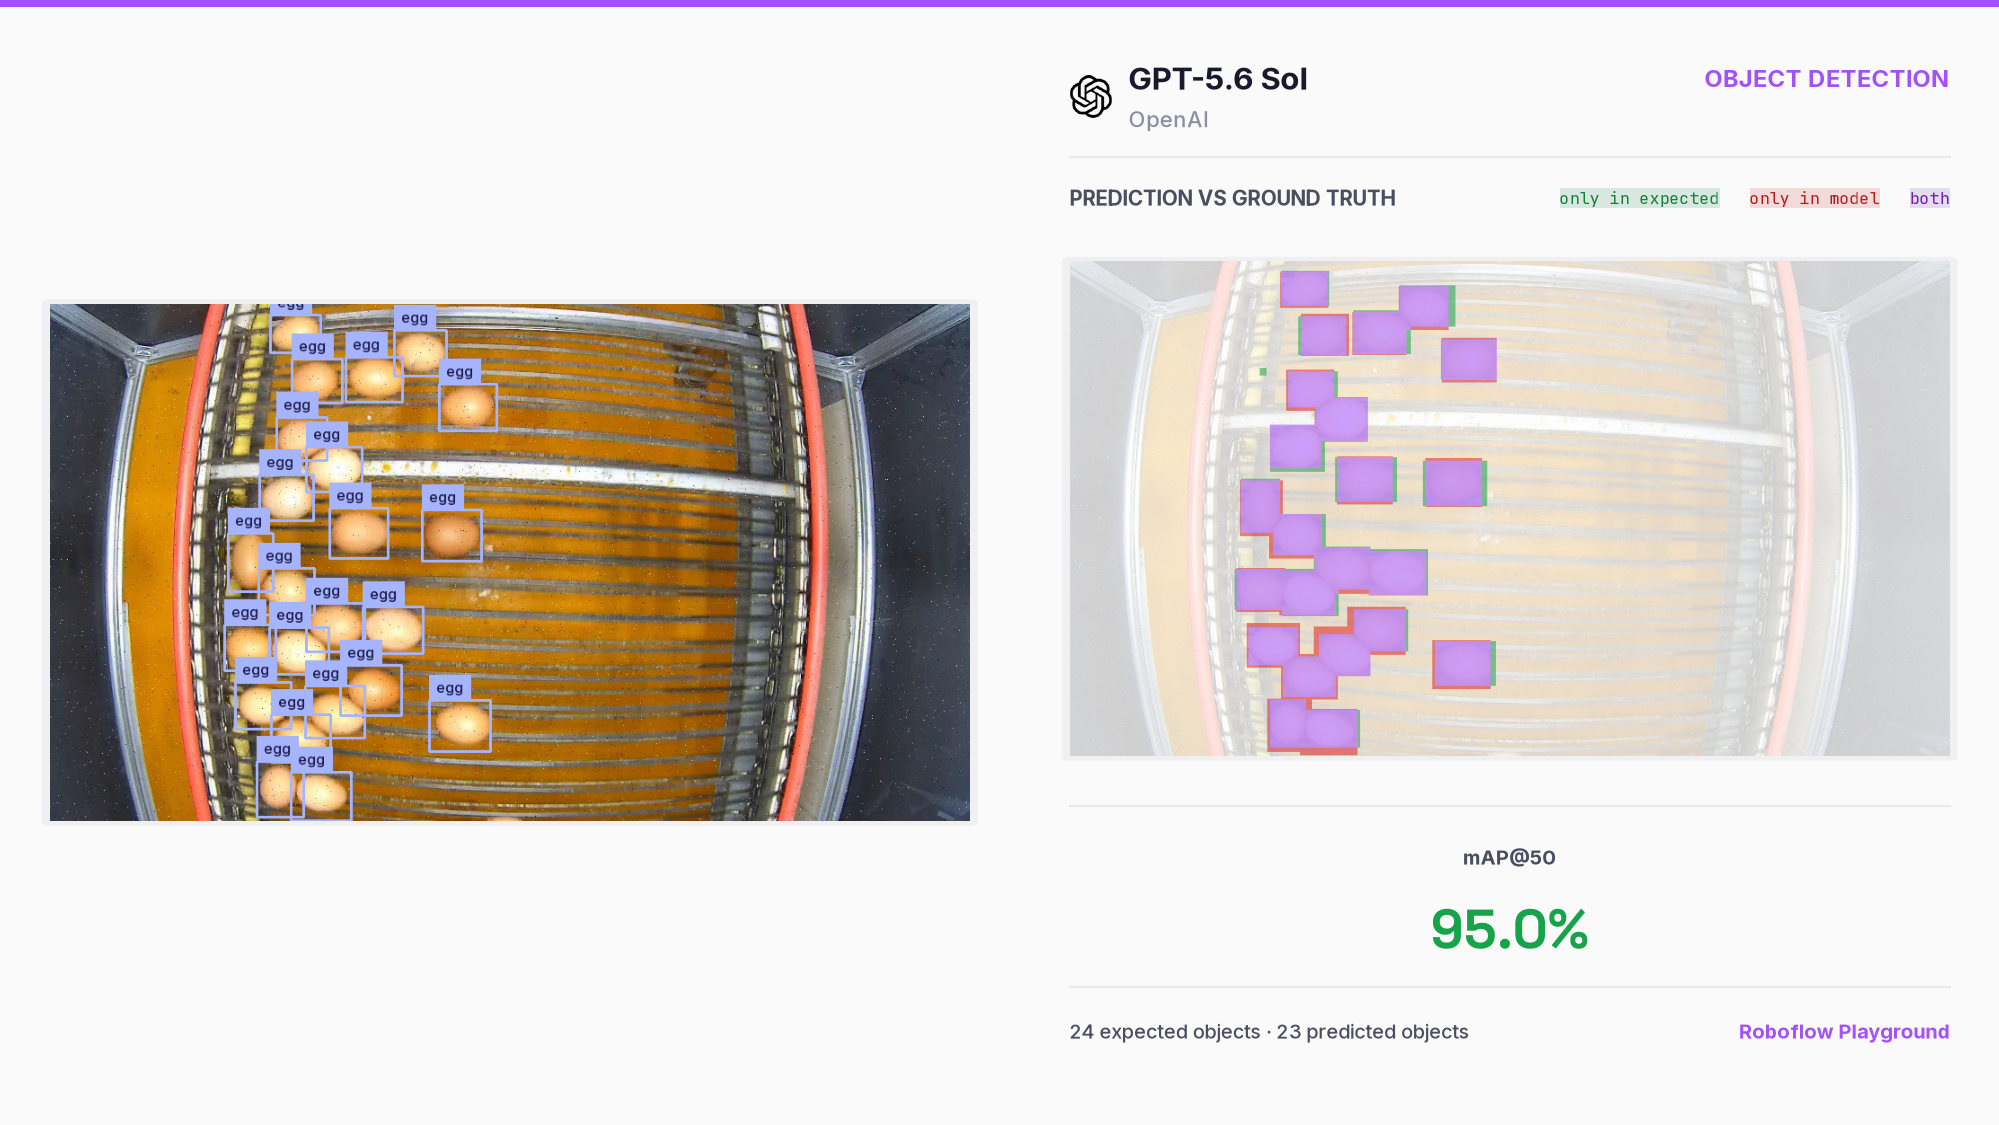
GPT-5.6 also performed well on dense scenes. The pills and eggs examples contain many similar objects packed closely together, a common weakness for VLM-based detection. Unlike traditional detectors, VLMs generate each class label and set of coordinates as text. As object count grows, the response becomes longer and the risk of missed objects, duplicates, or coordinate errors increases. Despite this, Sol detected most objects across both scenes.
For the best detection results, prompt GPT-5.6 models to return absolute XYXY coordinates in image pixels. This differs from Gemini 3.5 Flash, which performed best with YXYX coordinates normalized to a 0–1000 range. Using the wrong coordinate format reduced GPT-5.6 detection performance by around 15 mAP points in our benchmark.
In a few cases, GPT-5.6 Sol returned boxes in seemingly random parts of the image. Many had no overlap, or almost no overlap, with the ground truth. Instead of matching the visible objects, the boxes often formed unnatural layouts, such as straight rows or evenly spaced groups.
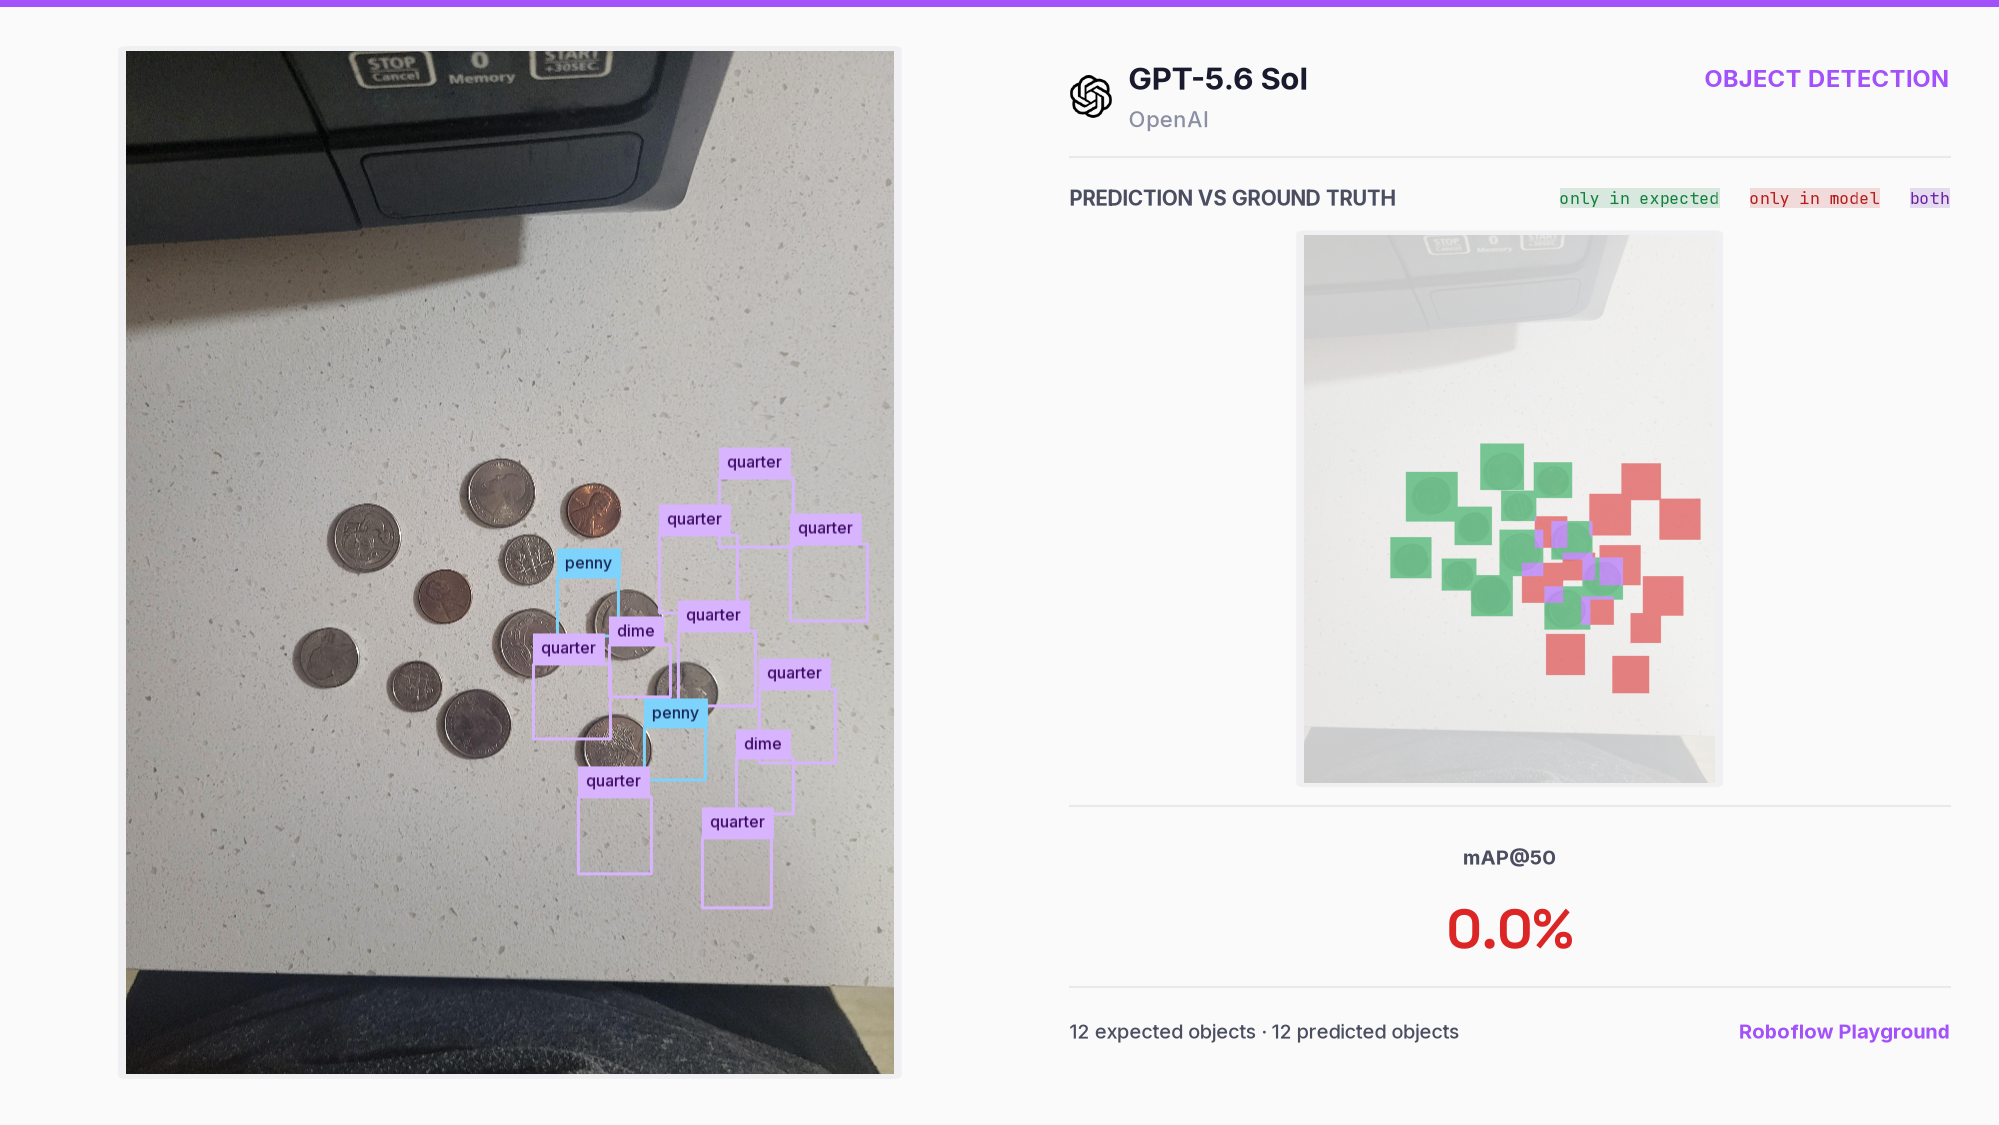
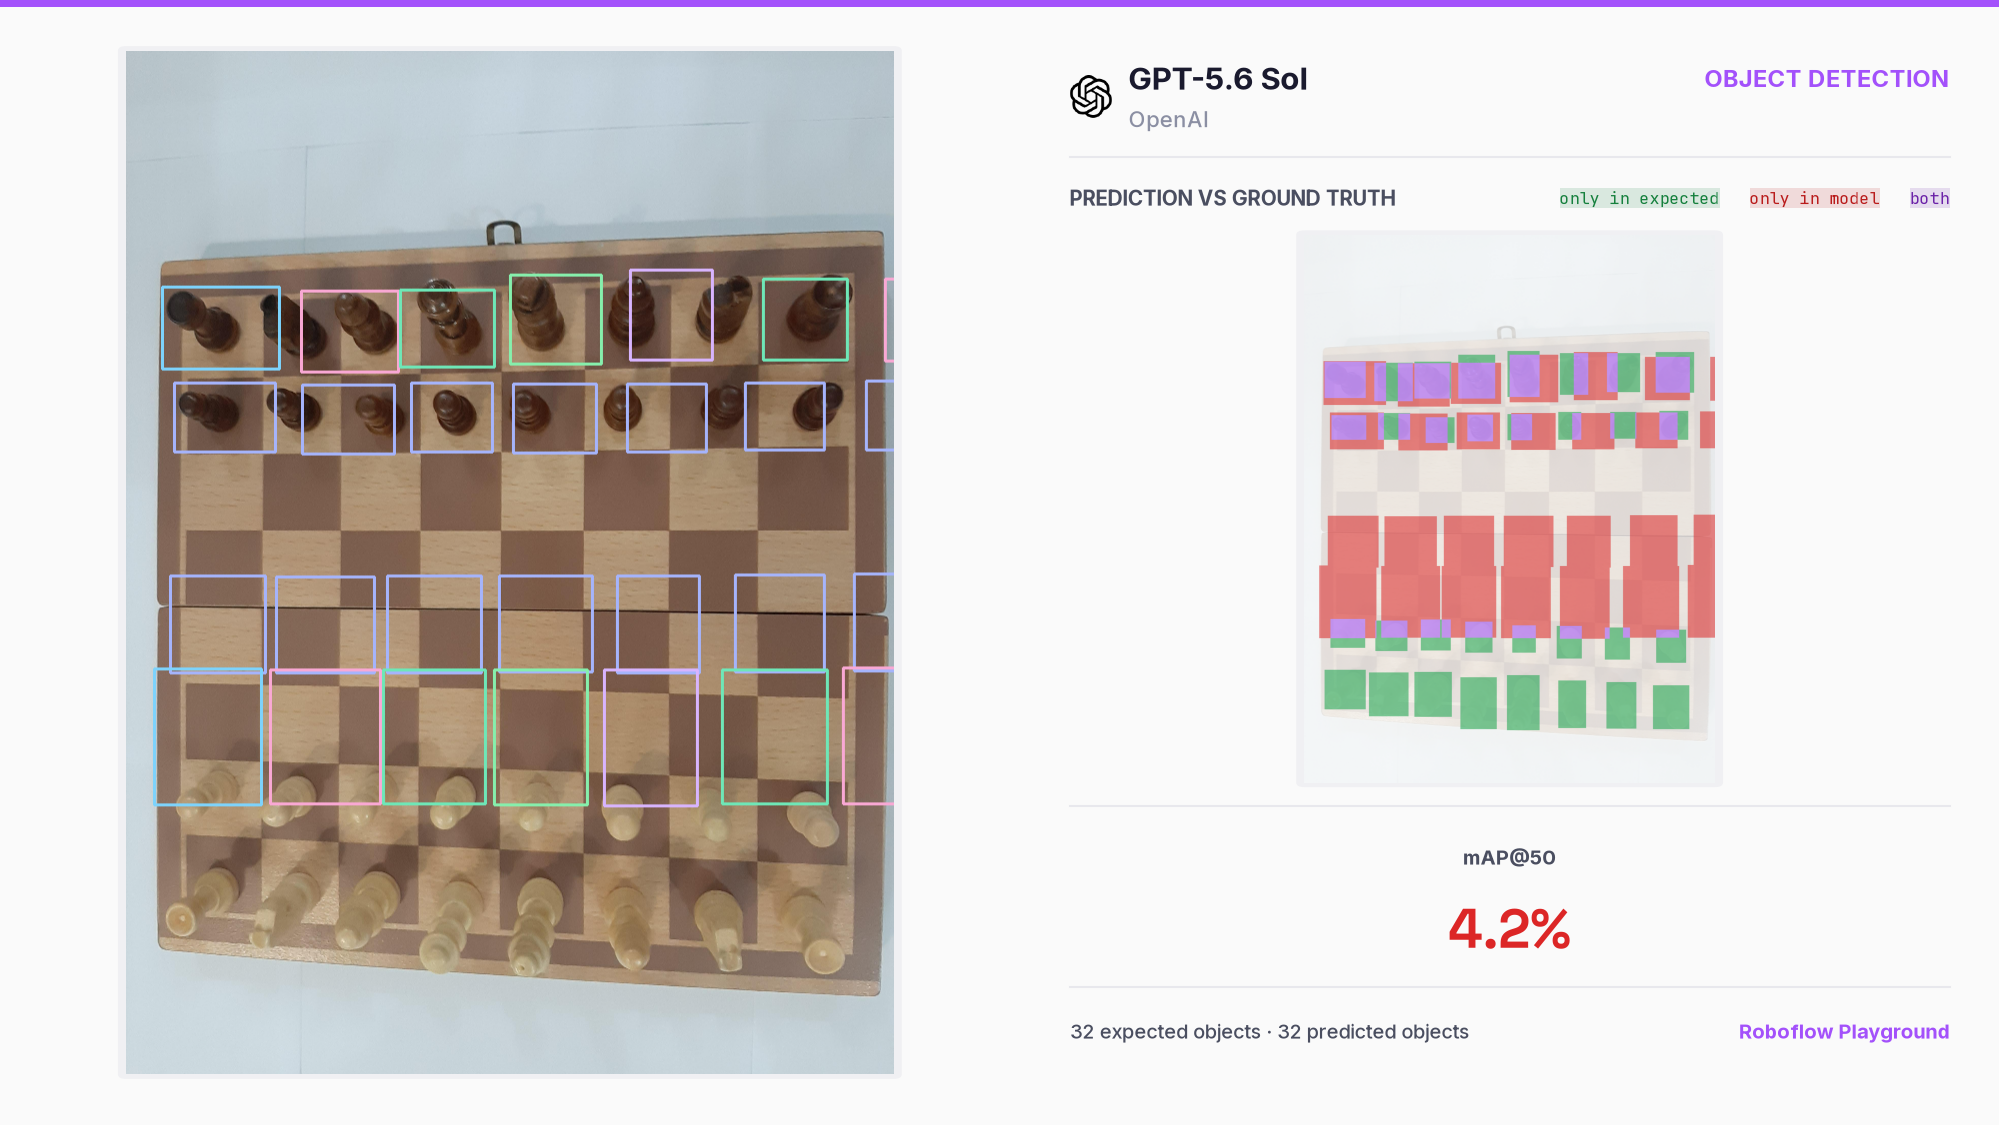
We shared those examples with OpenAI. Their team confirmed that Sol becomes less stable on images around 2,000 by 2,000 pixels or larger, especially at lower reasoning effort. Higher reasoning effort improves stability, but also increases token use, latency, and cost. Resizing or cropping large images before sending them to the OpenAI API is the most practical workaround.
Object Counting
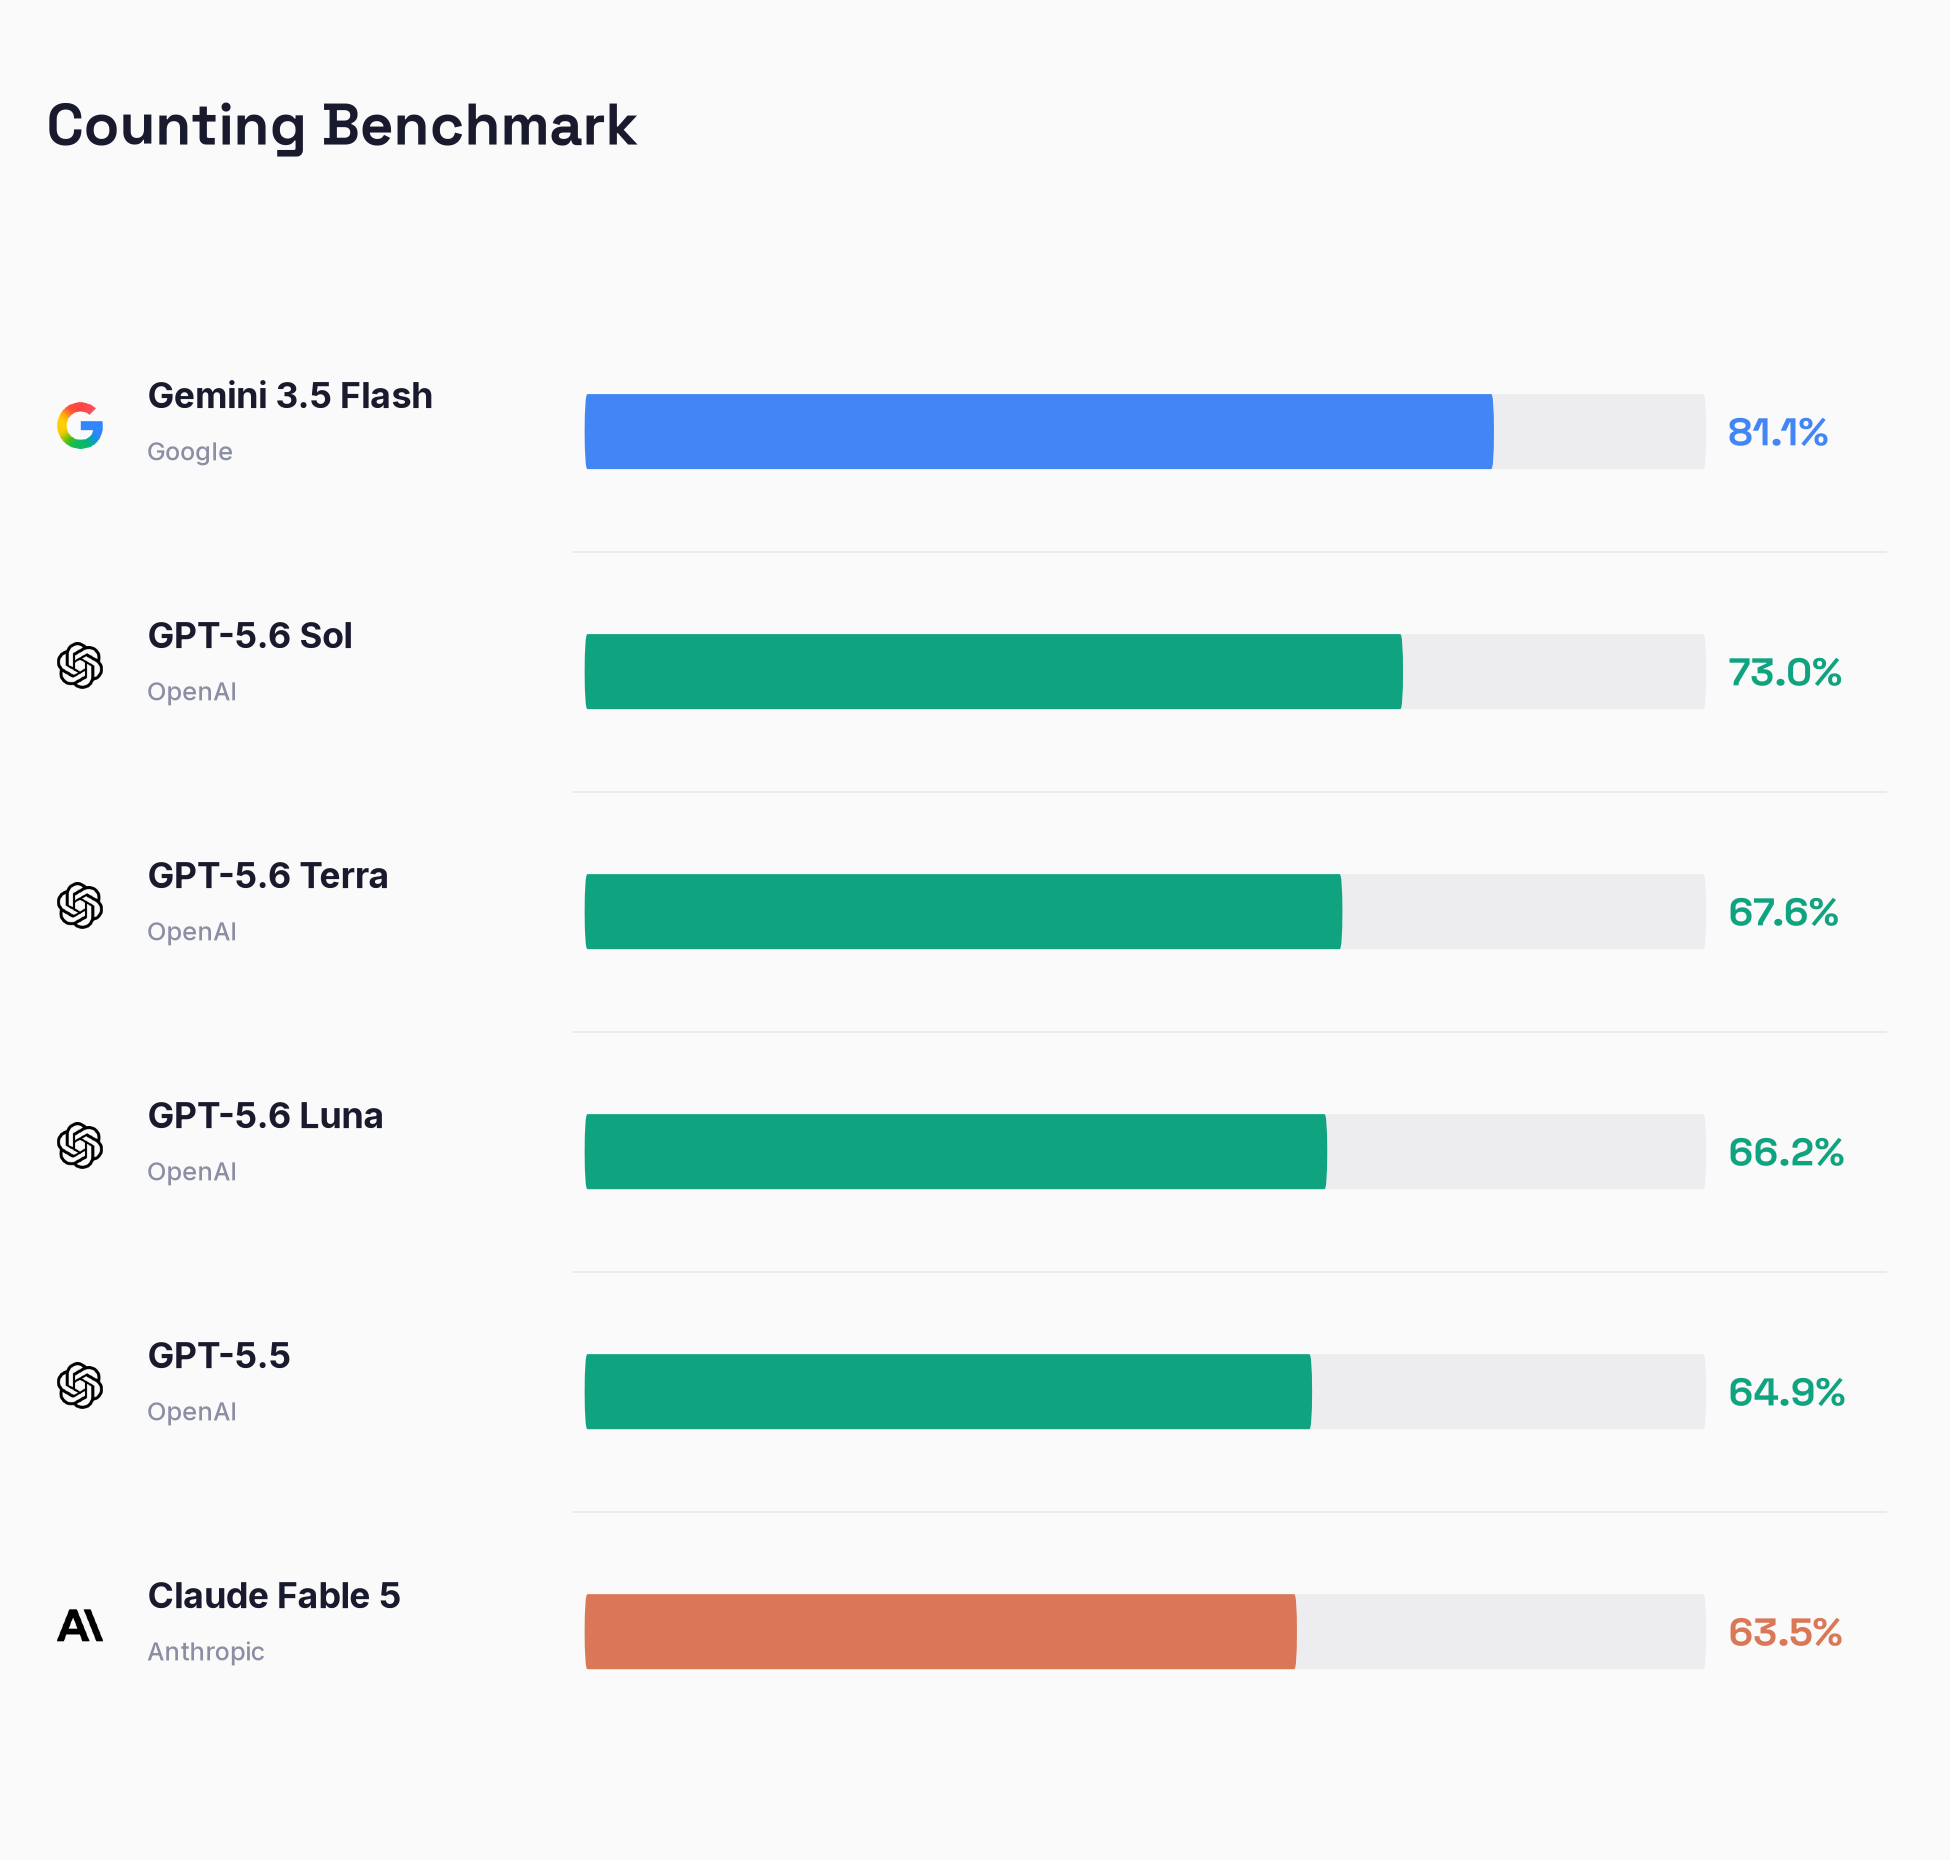
Counting improved across the full GPT-5.6 lineup. Sol scored 73.0% in our benchmark, up from 64.9% for GPT-5.5, while Terra and Luna reached 67.6% and 66.2%. Luna, the cheapest model in the lineup, still outperformed the previous OpenAI baseline.
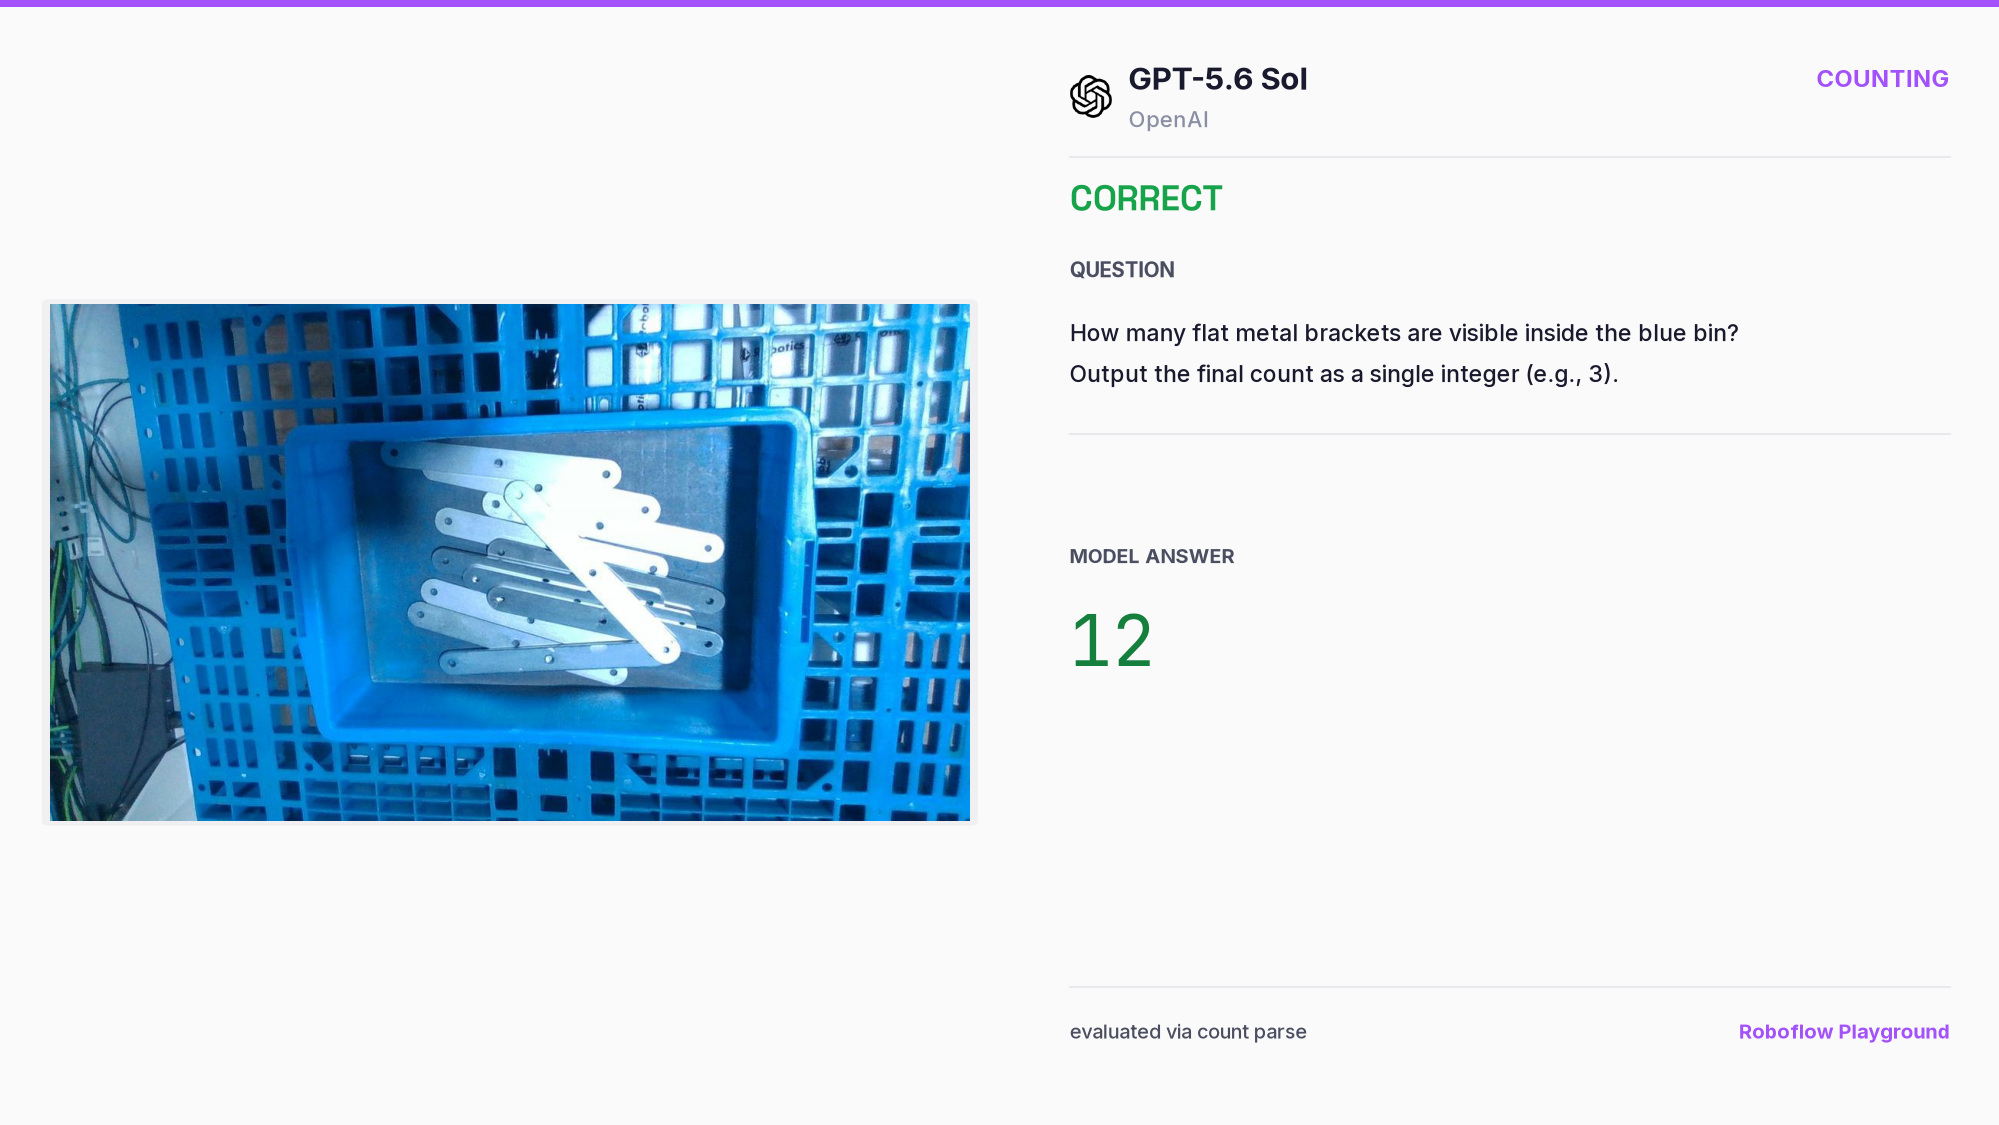
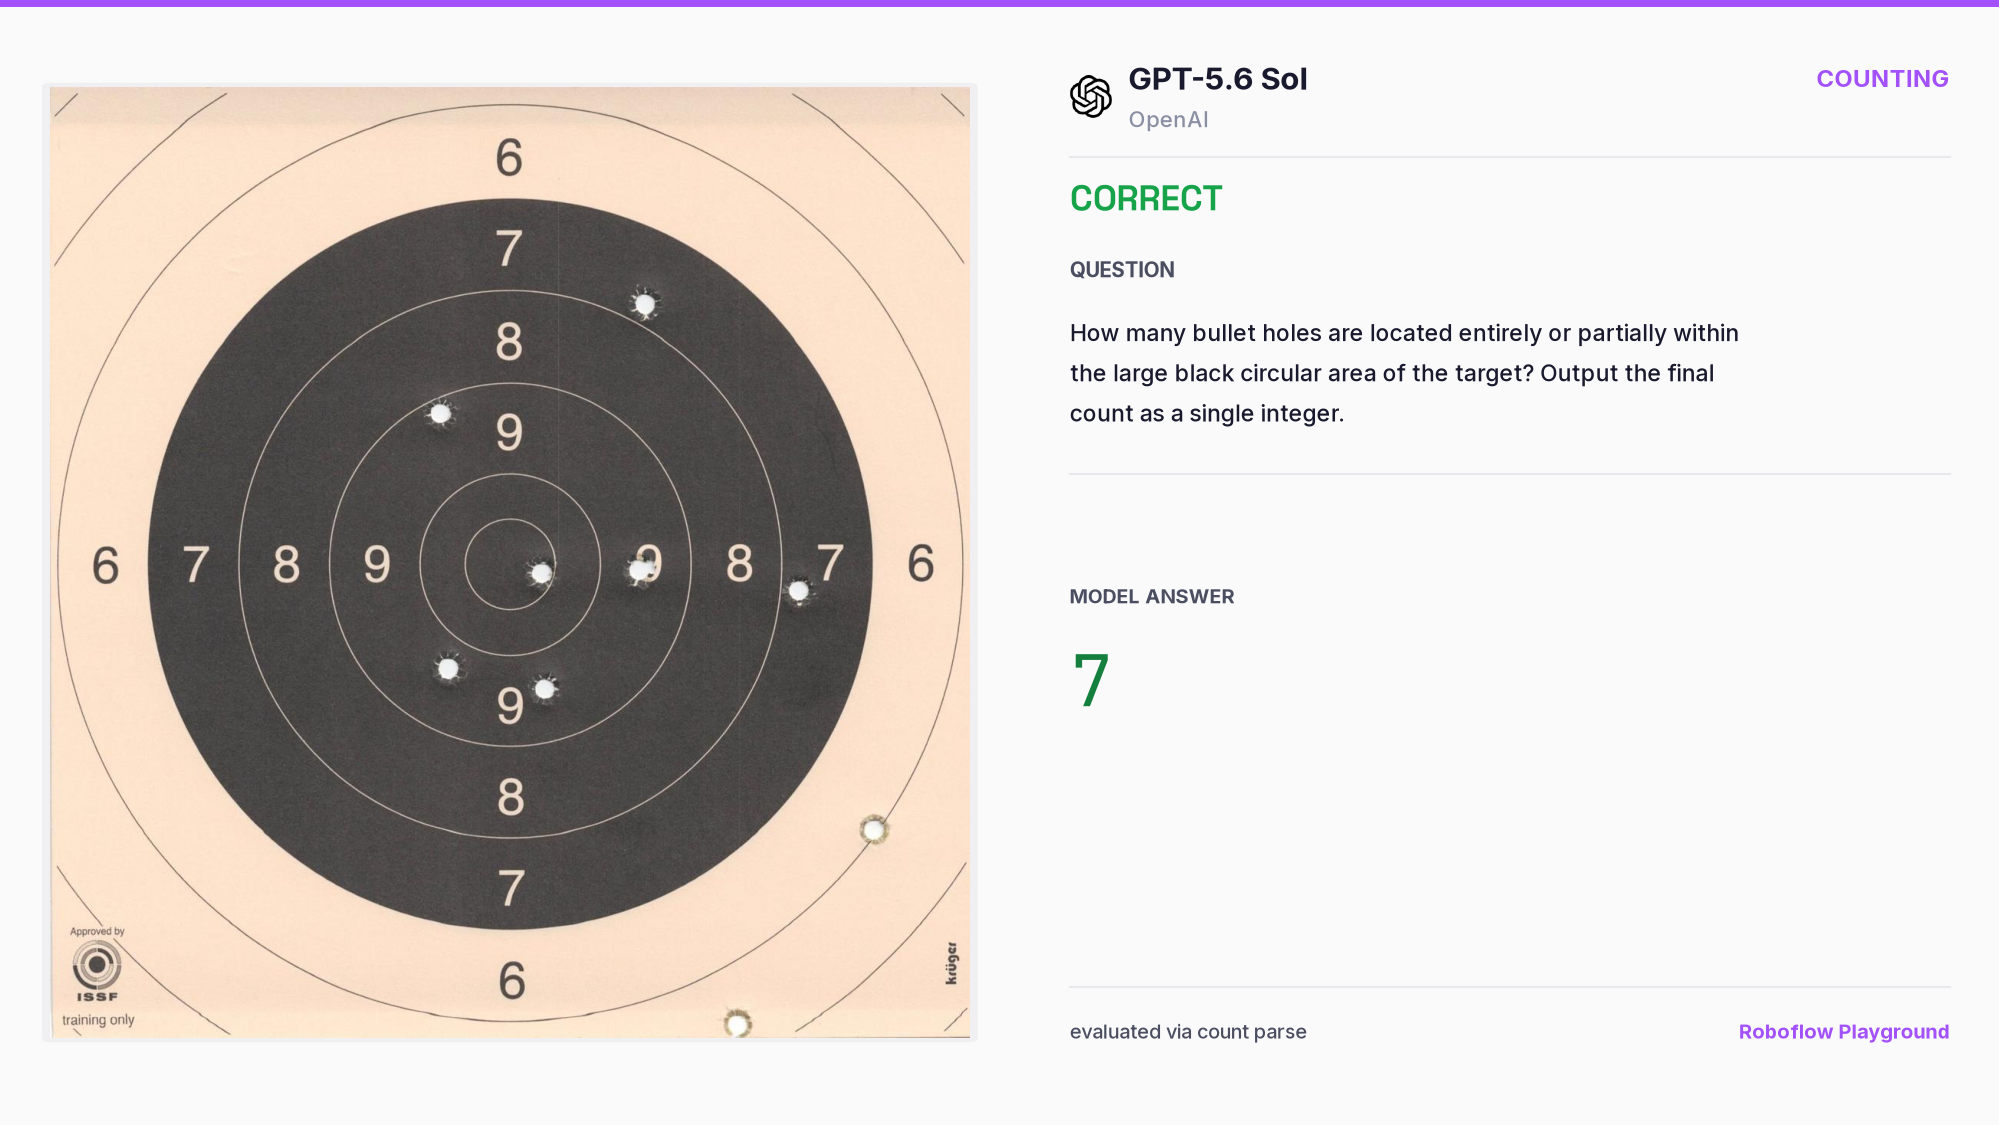
As part of the benchmark, we tested cases requiring more than spotting objects and returning a total. Sol counted heavily overlapping metal brackets, a difficult case for both traditional object detectors and VLMs. Sol also counted bullet holes only inside selected scoring zones, showing an understanding of both which objects to count and where the rule applied.
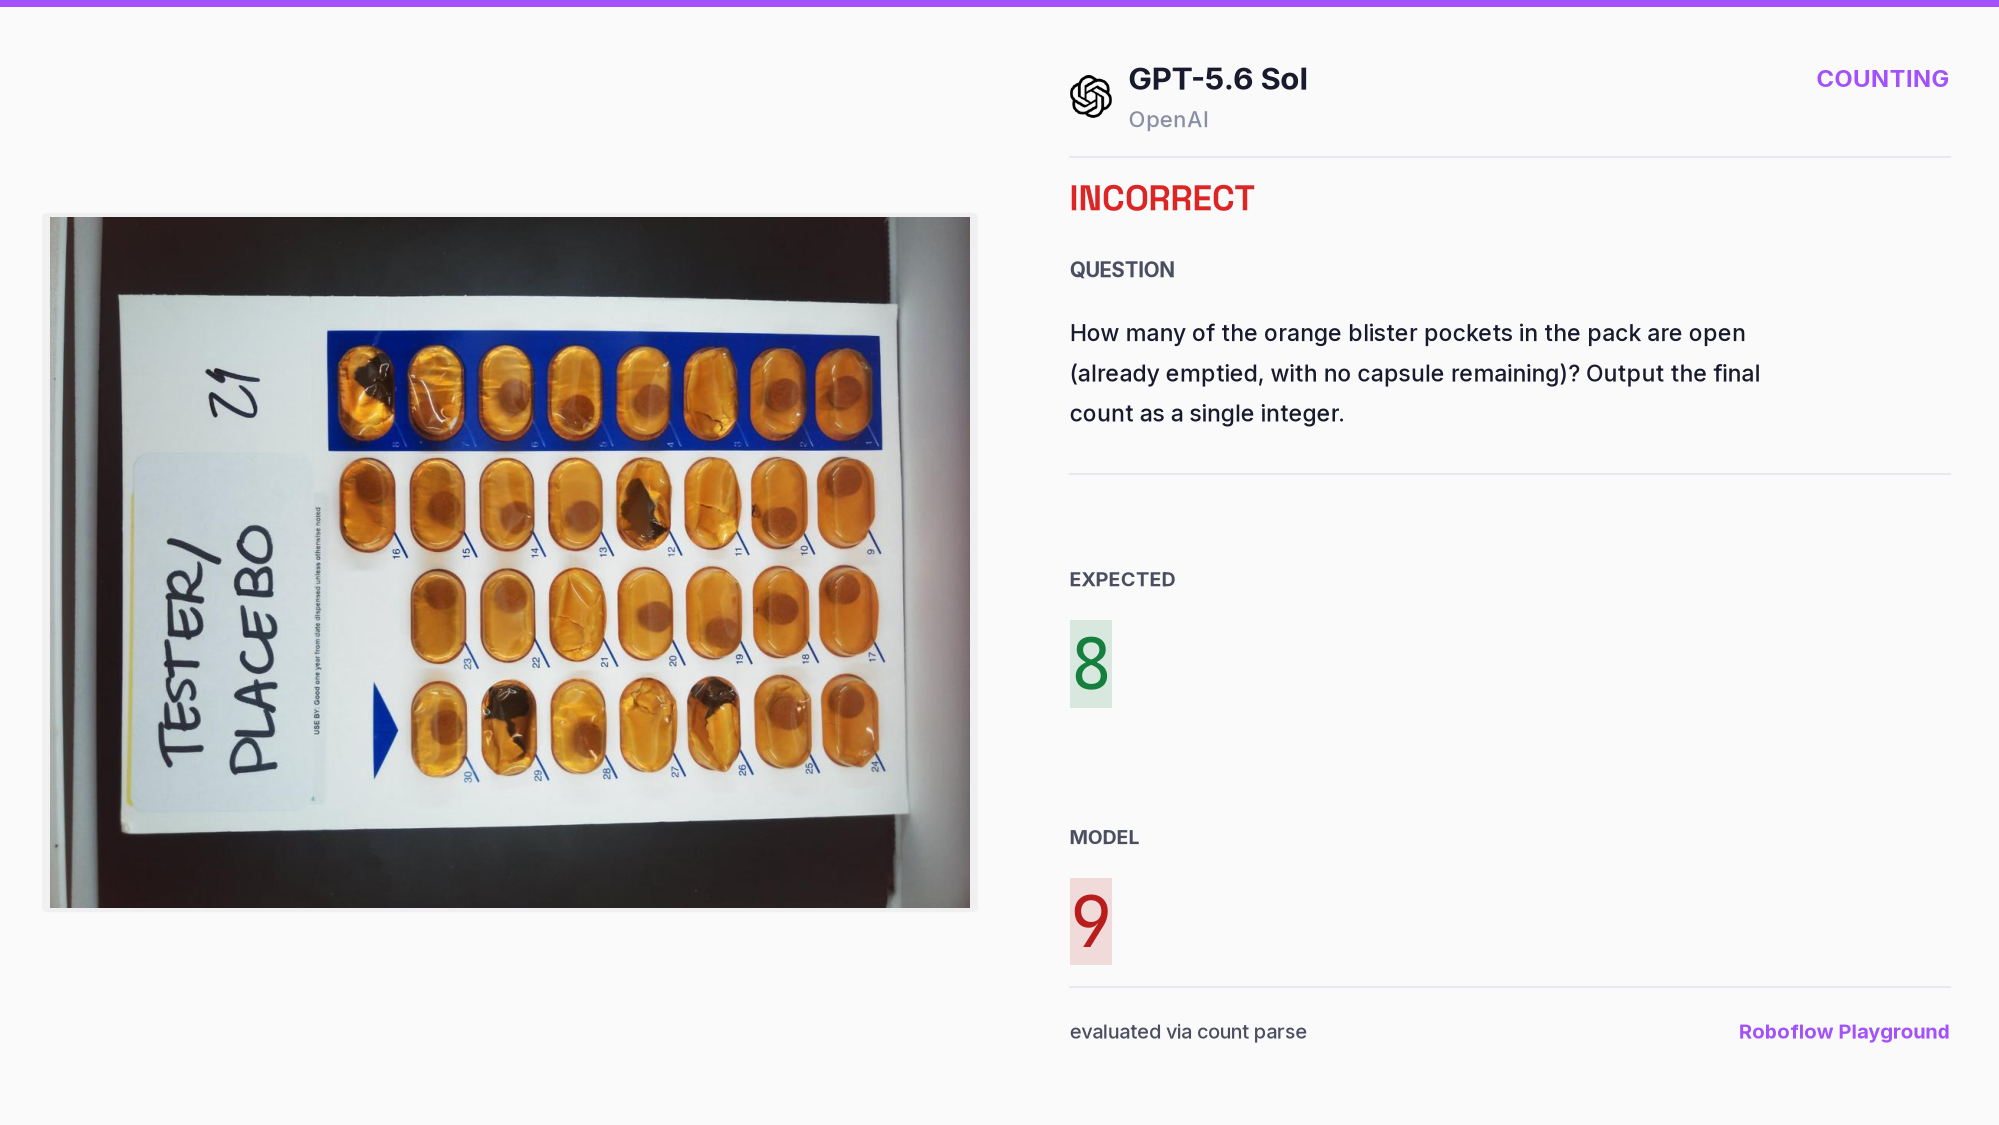
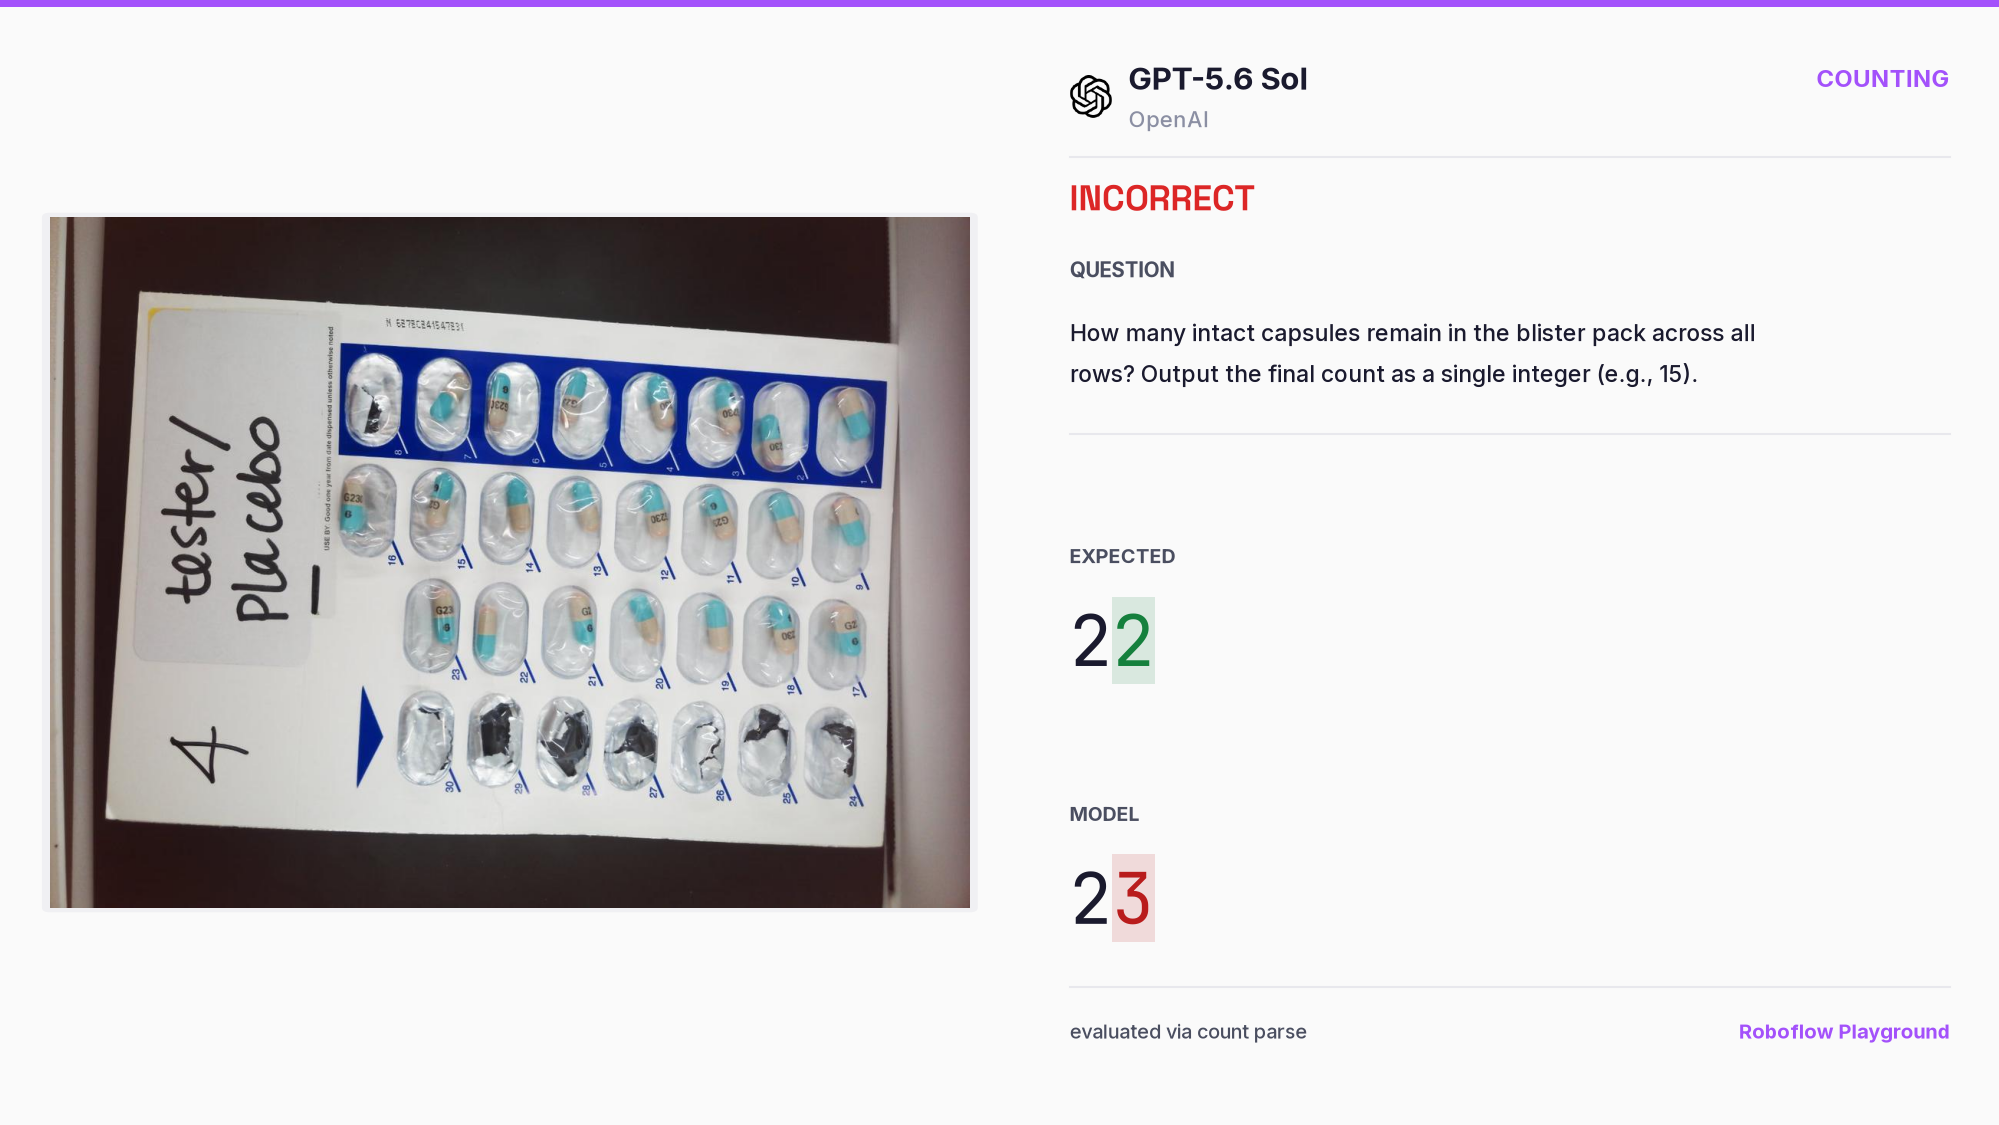
Blister packs proved much harder. In separate prompts, we asked Sol to count the empty slots and the pills still sealed inside the package. The repeated layout, reflections, and small visual differences between filled and empty slots made both tasks difficult.
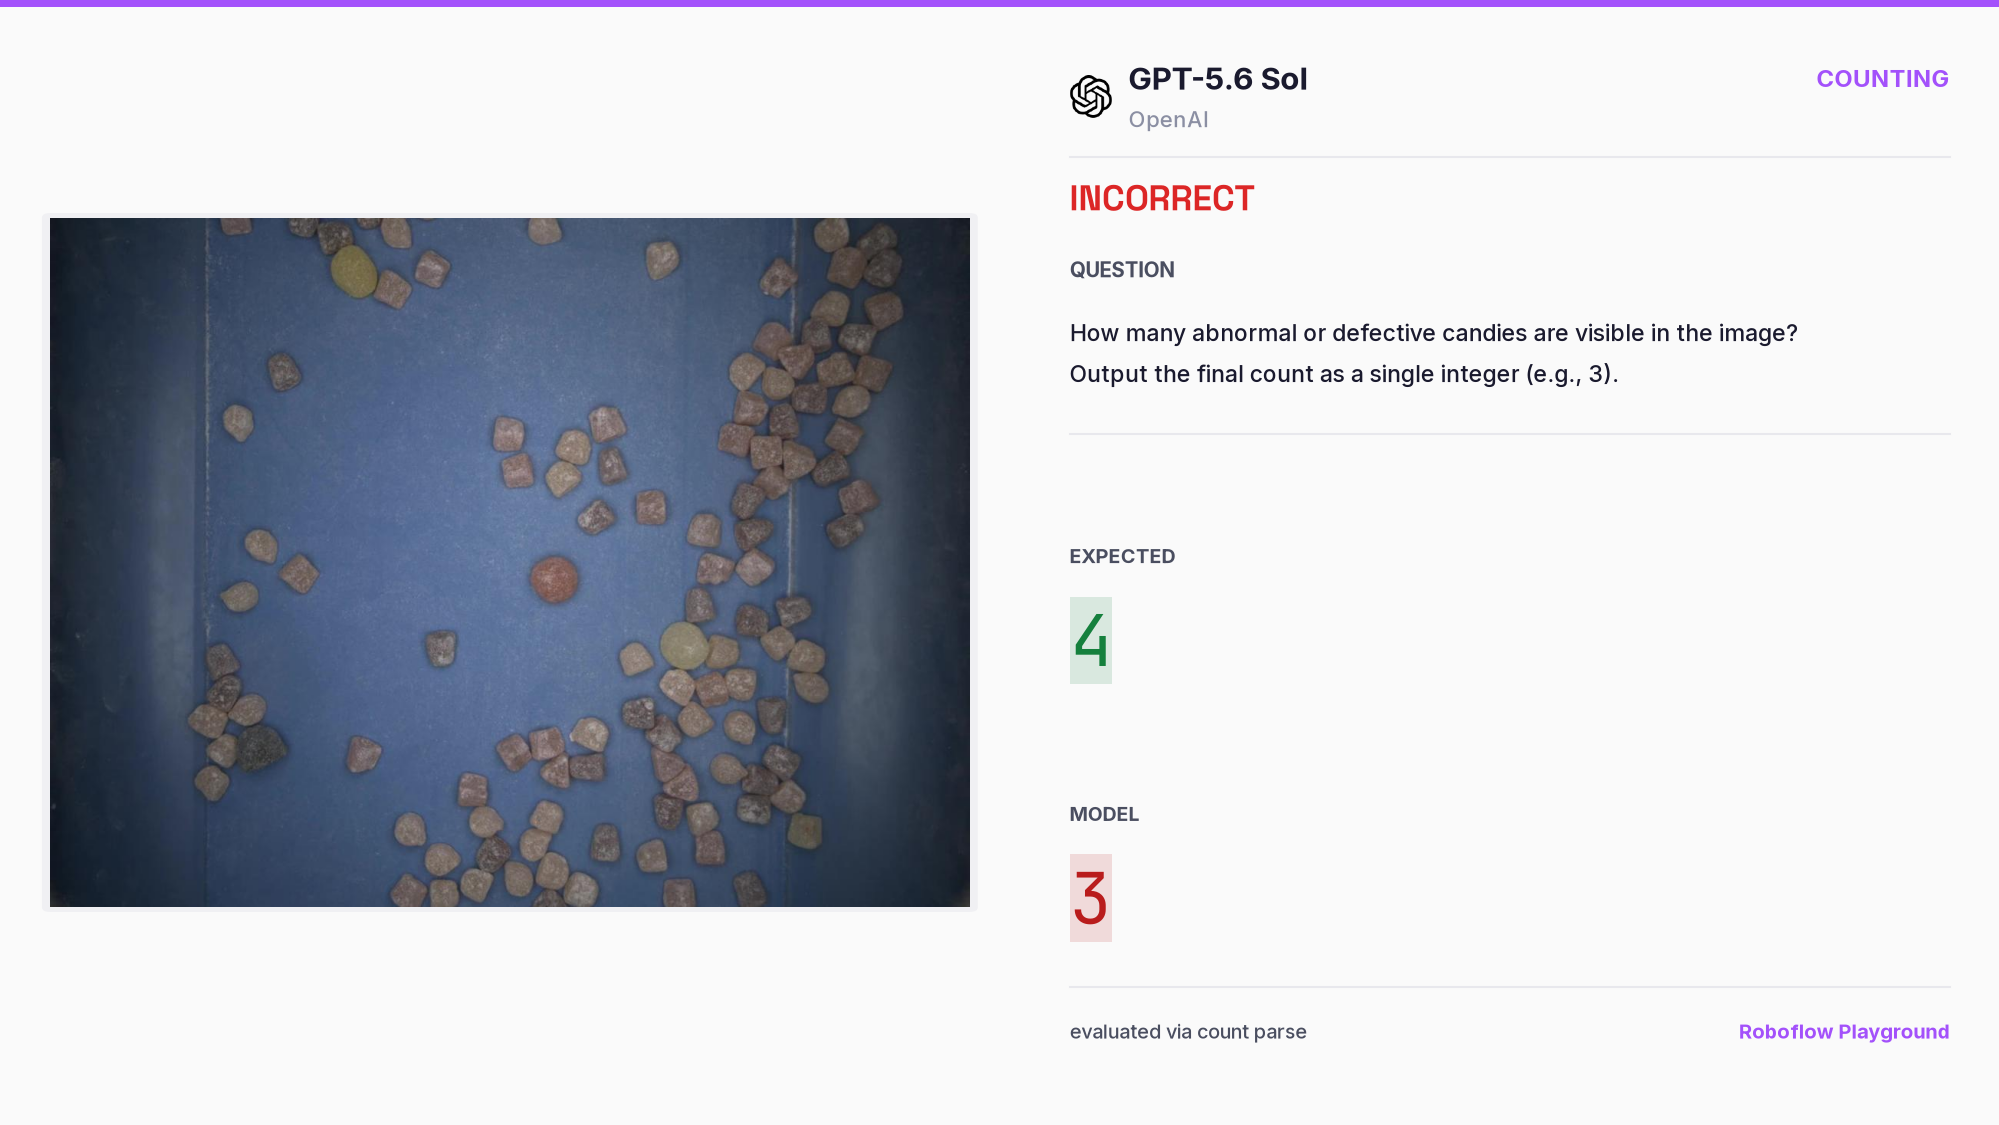
The abnormal candy example exposed a different type of failure. Sol gave the wrong count, though it is unclear whether the model miscounted the candies or misunderstood the target category.
OCR and Data Extraction
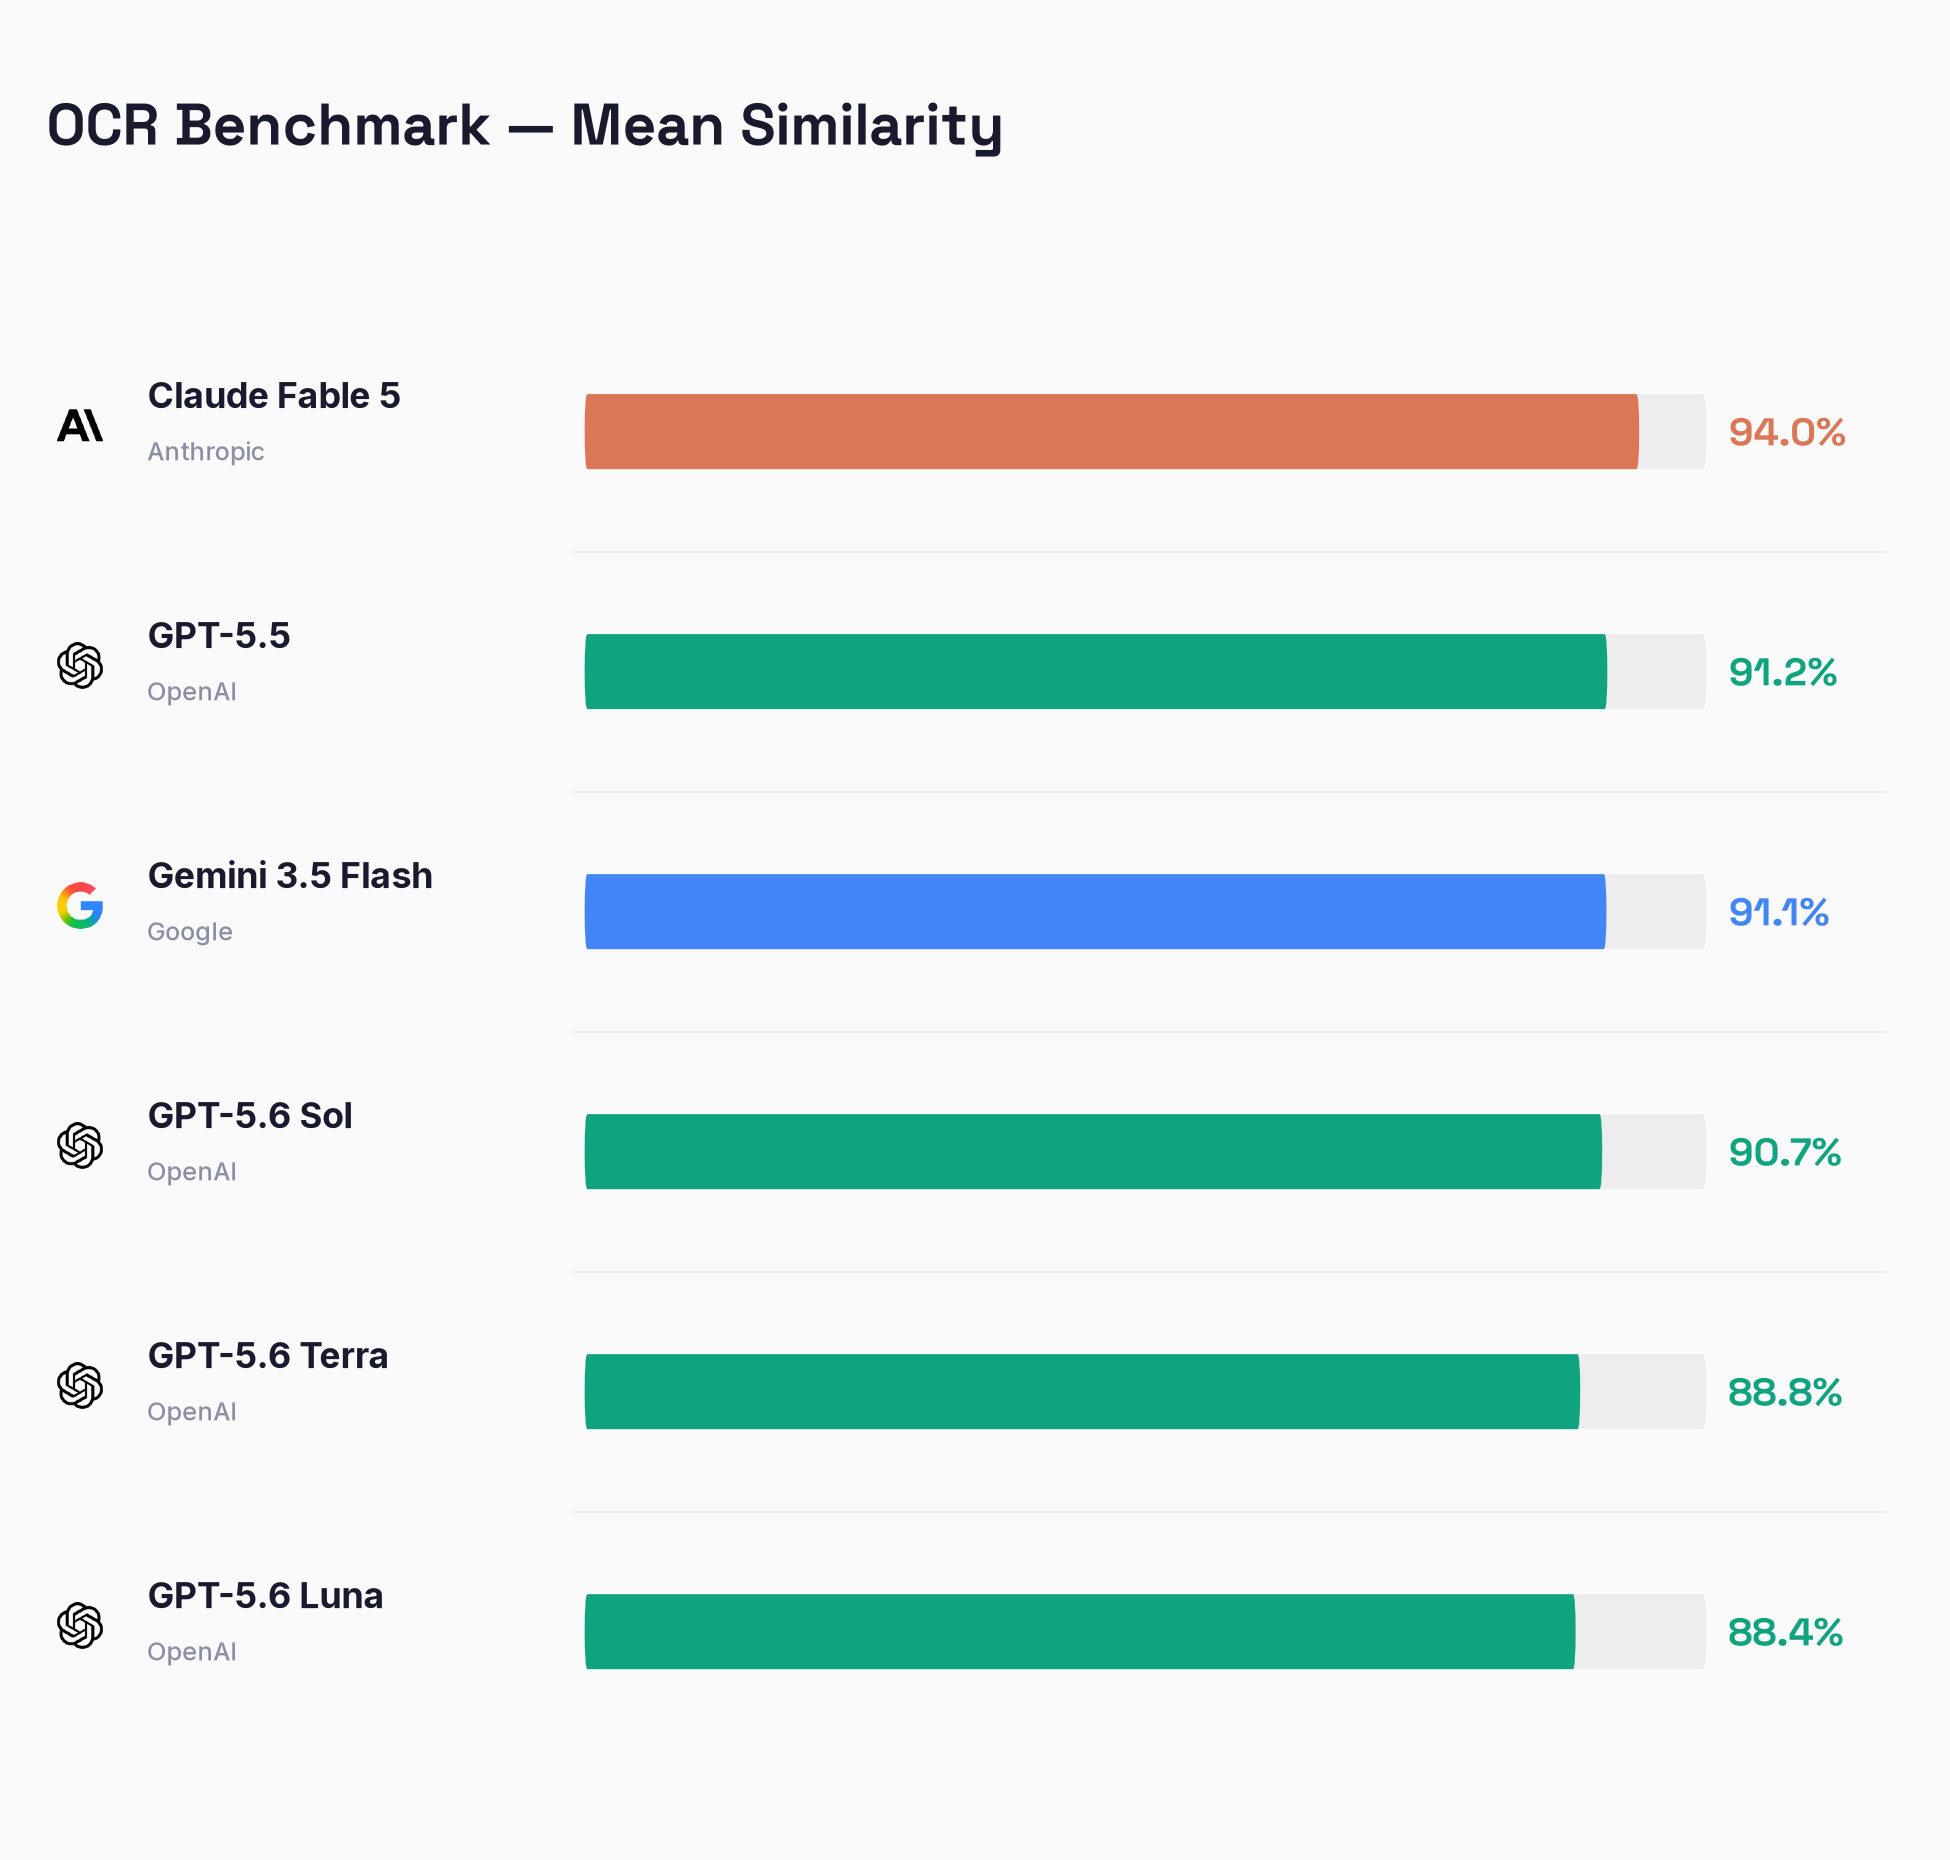
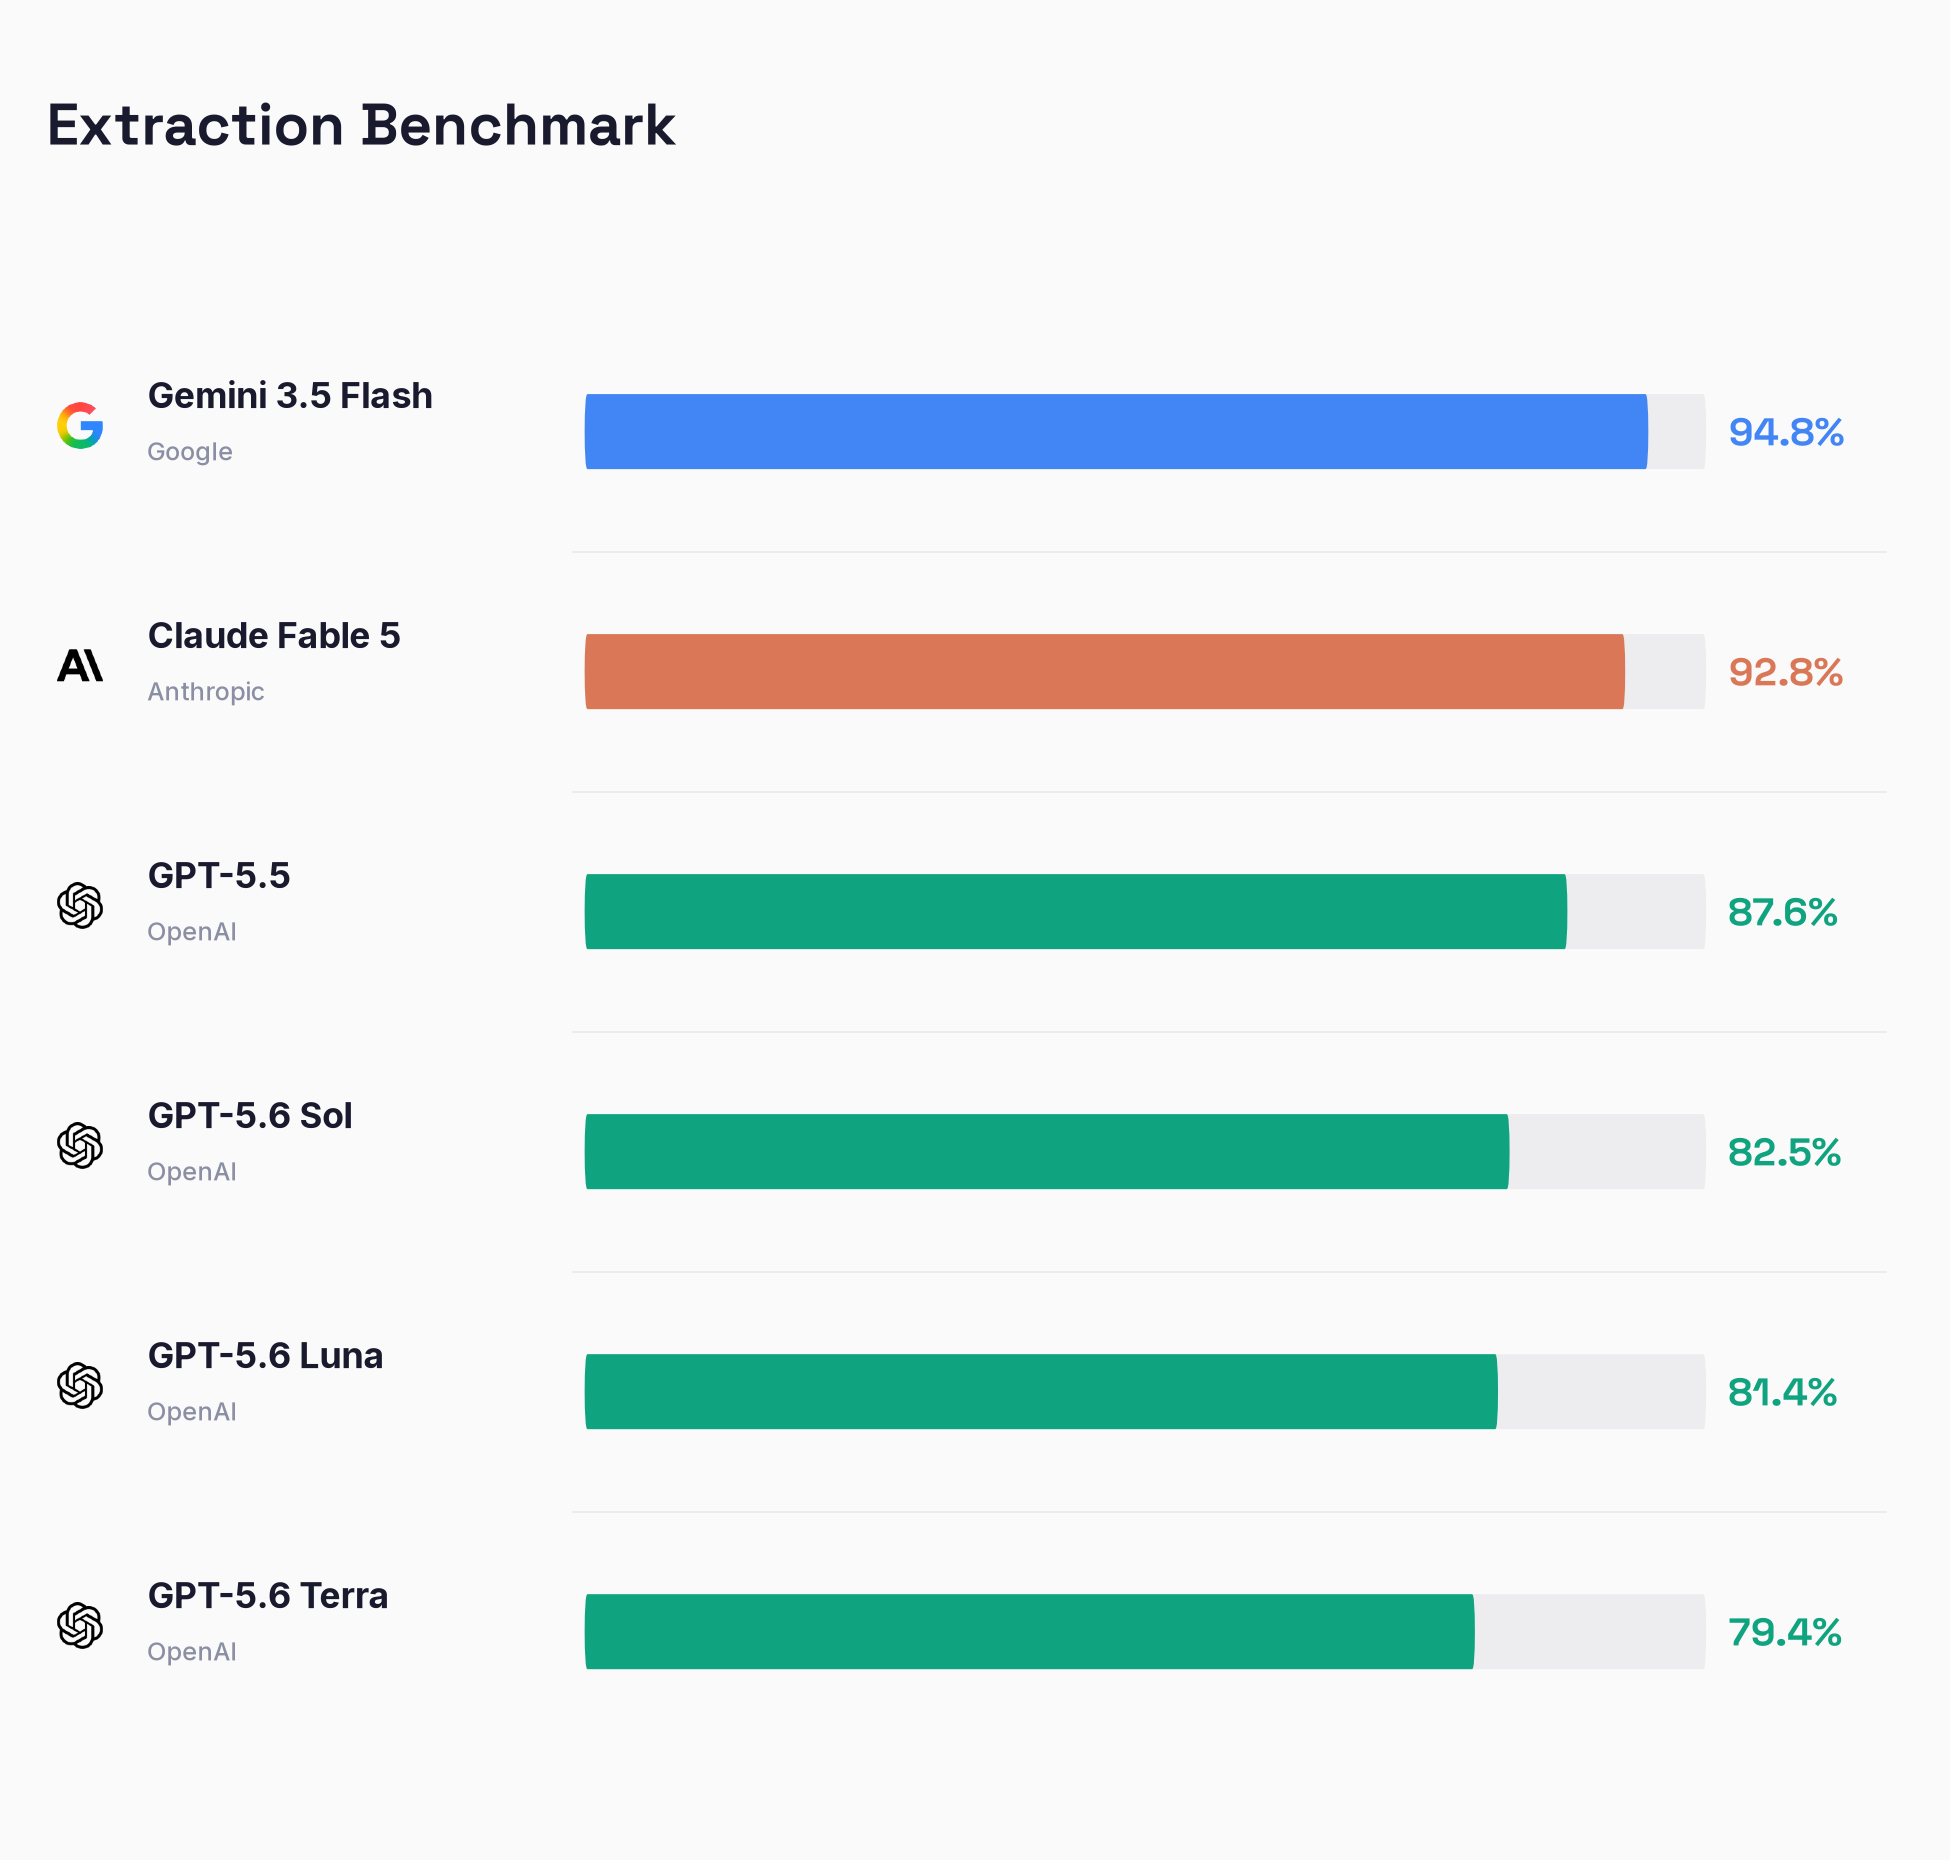
OCR performance stayed close to GPT-5.5. Sol achieved a 90.7% mean similarity score, only 0.5 points behind GPT-5.5 at 91.2%, while Terra and Luna reached 88.8% and 88.4%. The gap was larger in text extraction, where Sol scored 82.5% compared with 87.6% for GPT-5.5. Luna and Terra followed at 81.4% and 79.4%.
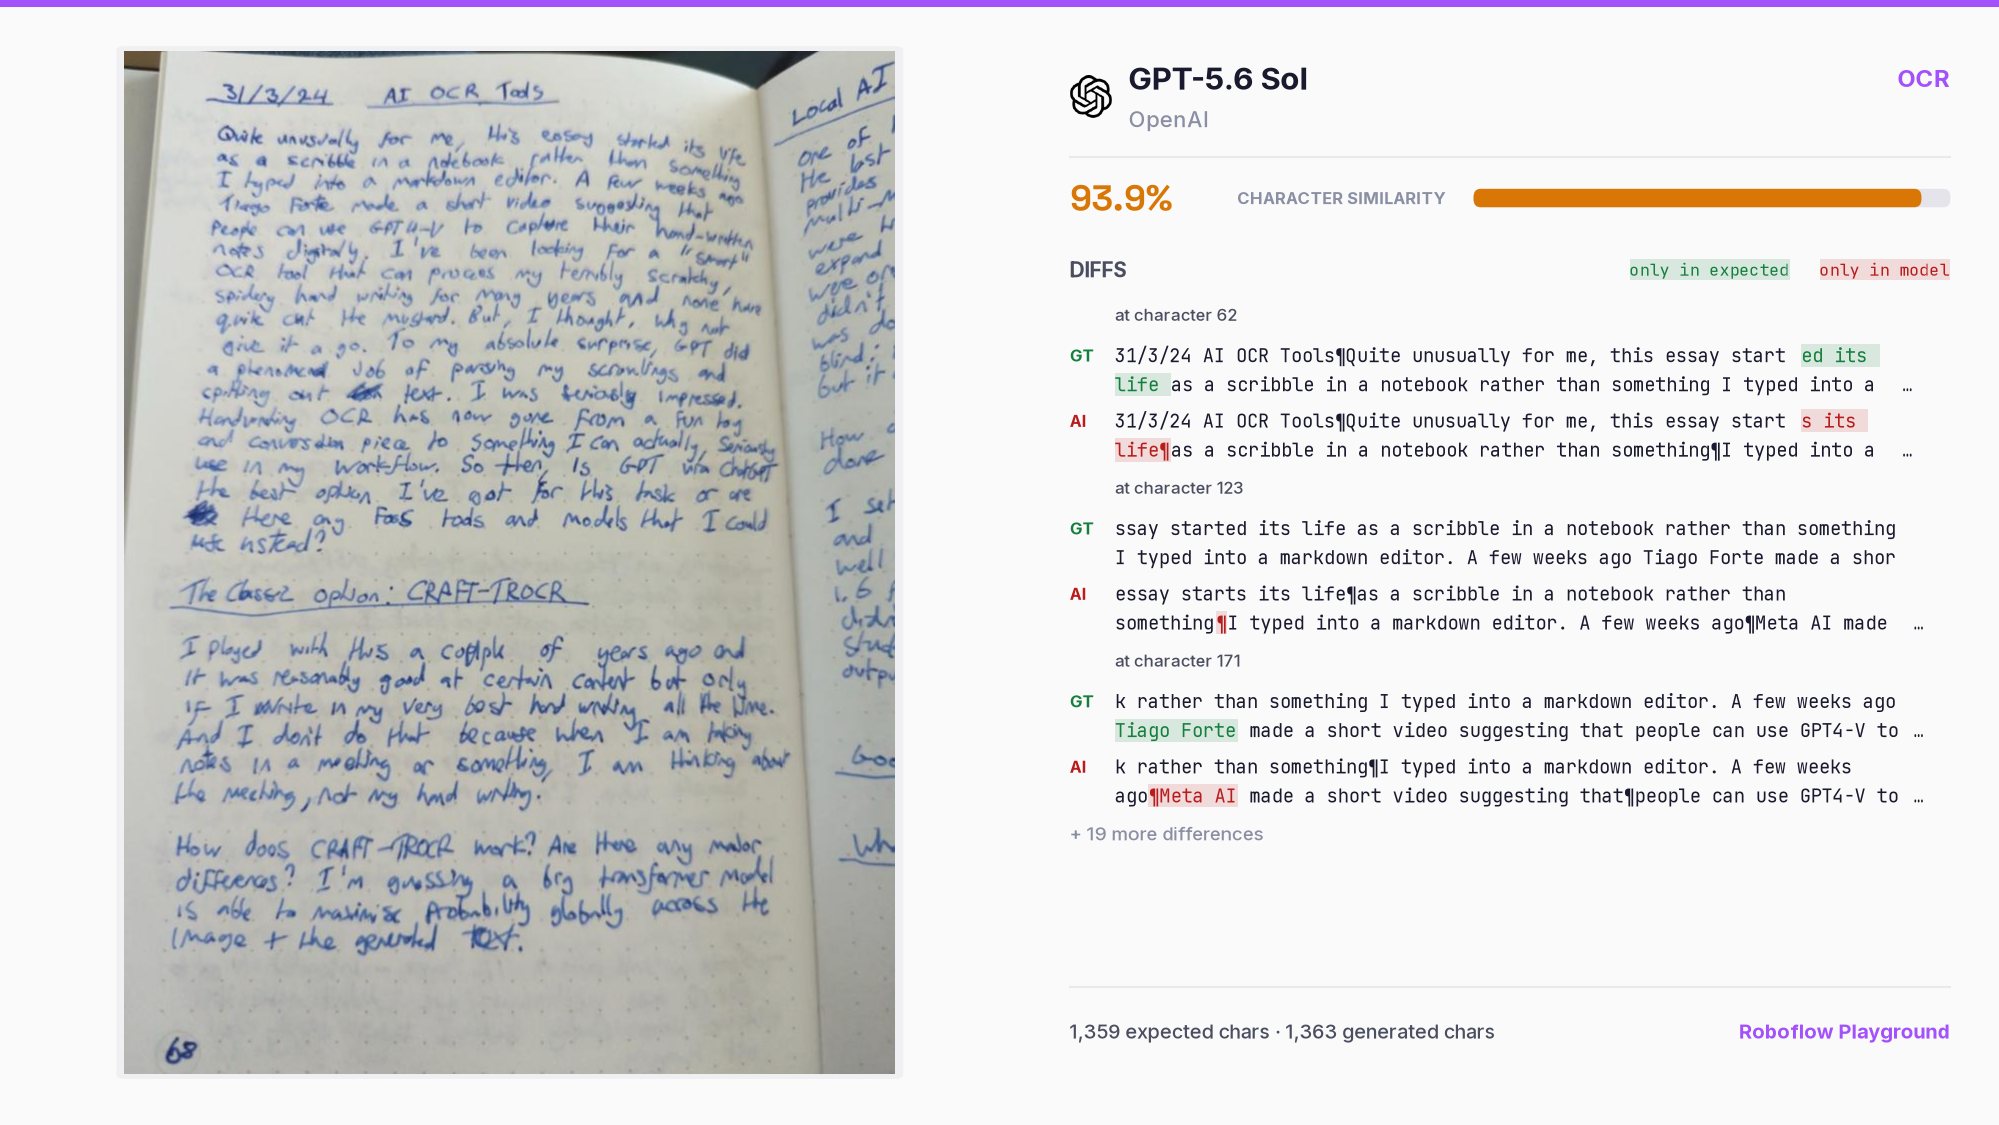
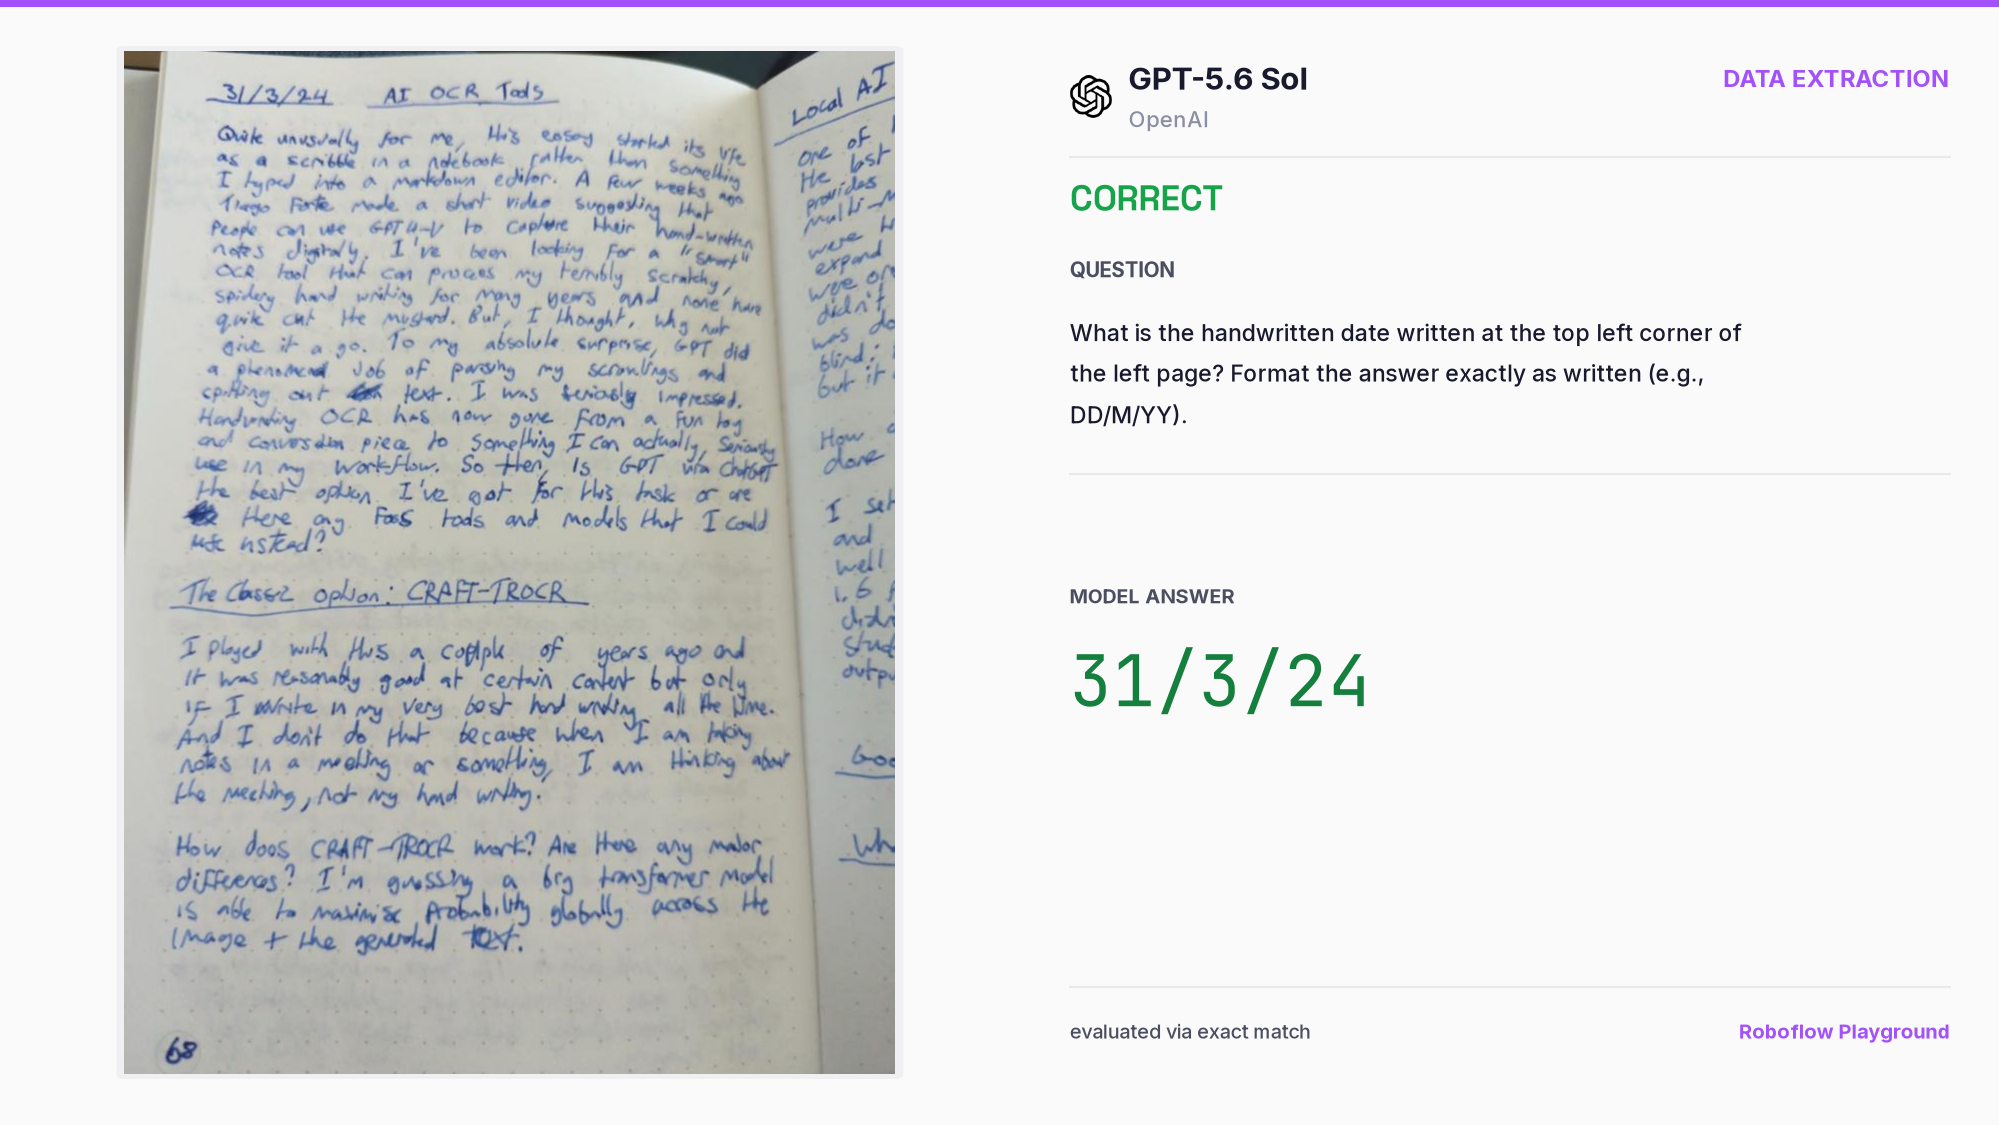
As part of the benchmark, we separated full transcription from targeted extraction. OCR asks the model to transcribe all visible text, while text extraction asks for a specific piece of information. Sol performed well on handwritten notes in both settings, producing a full transcription in one case and extracting a requested date in another.
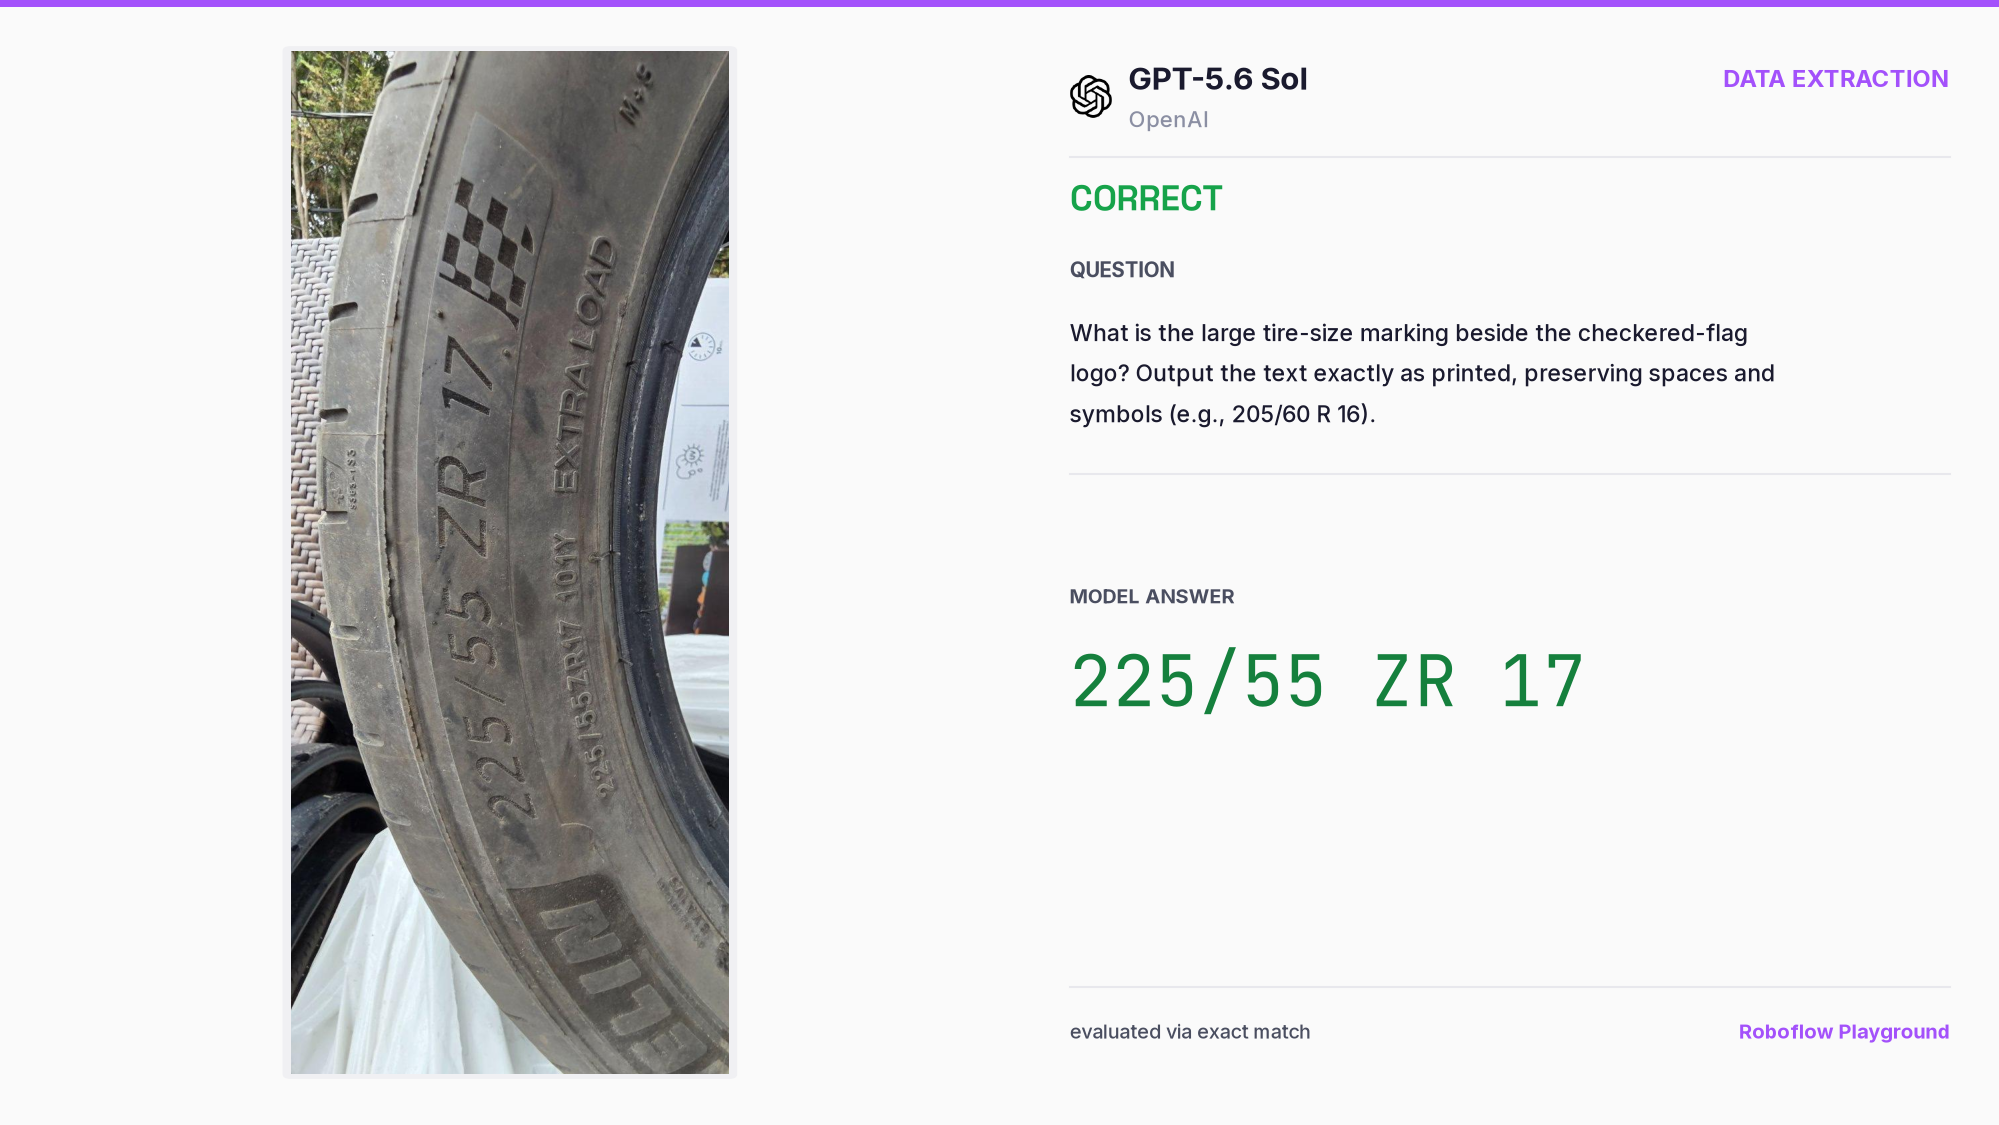
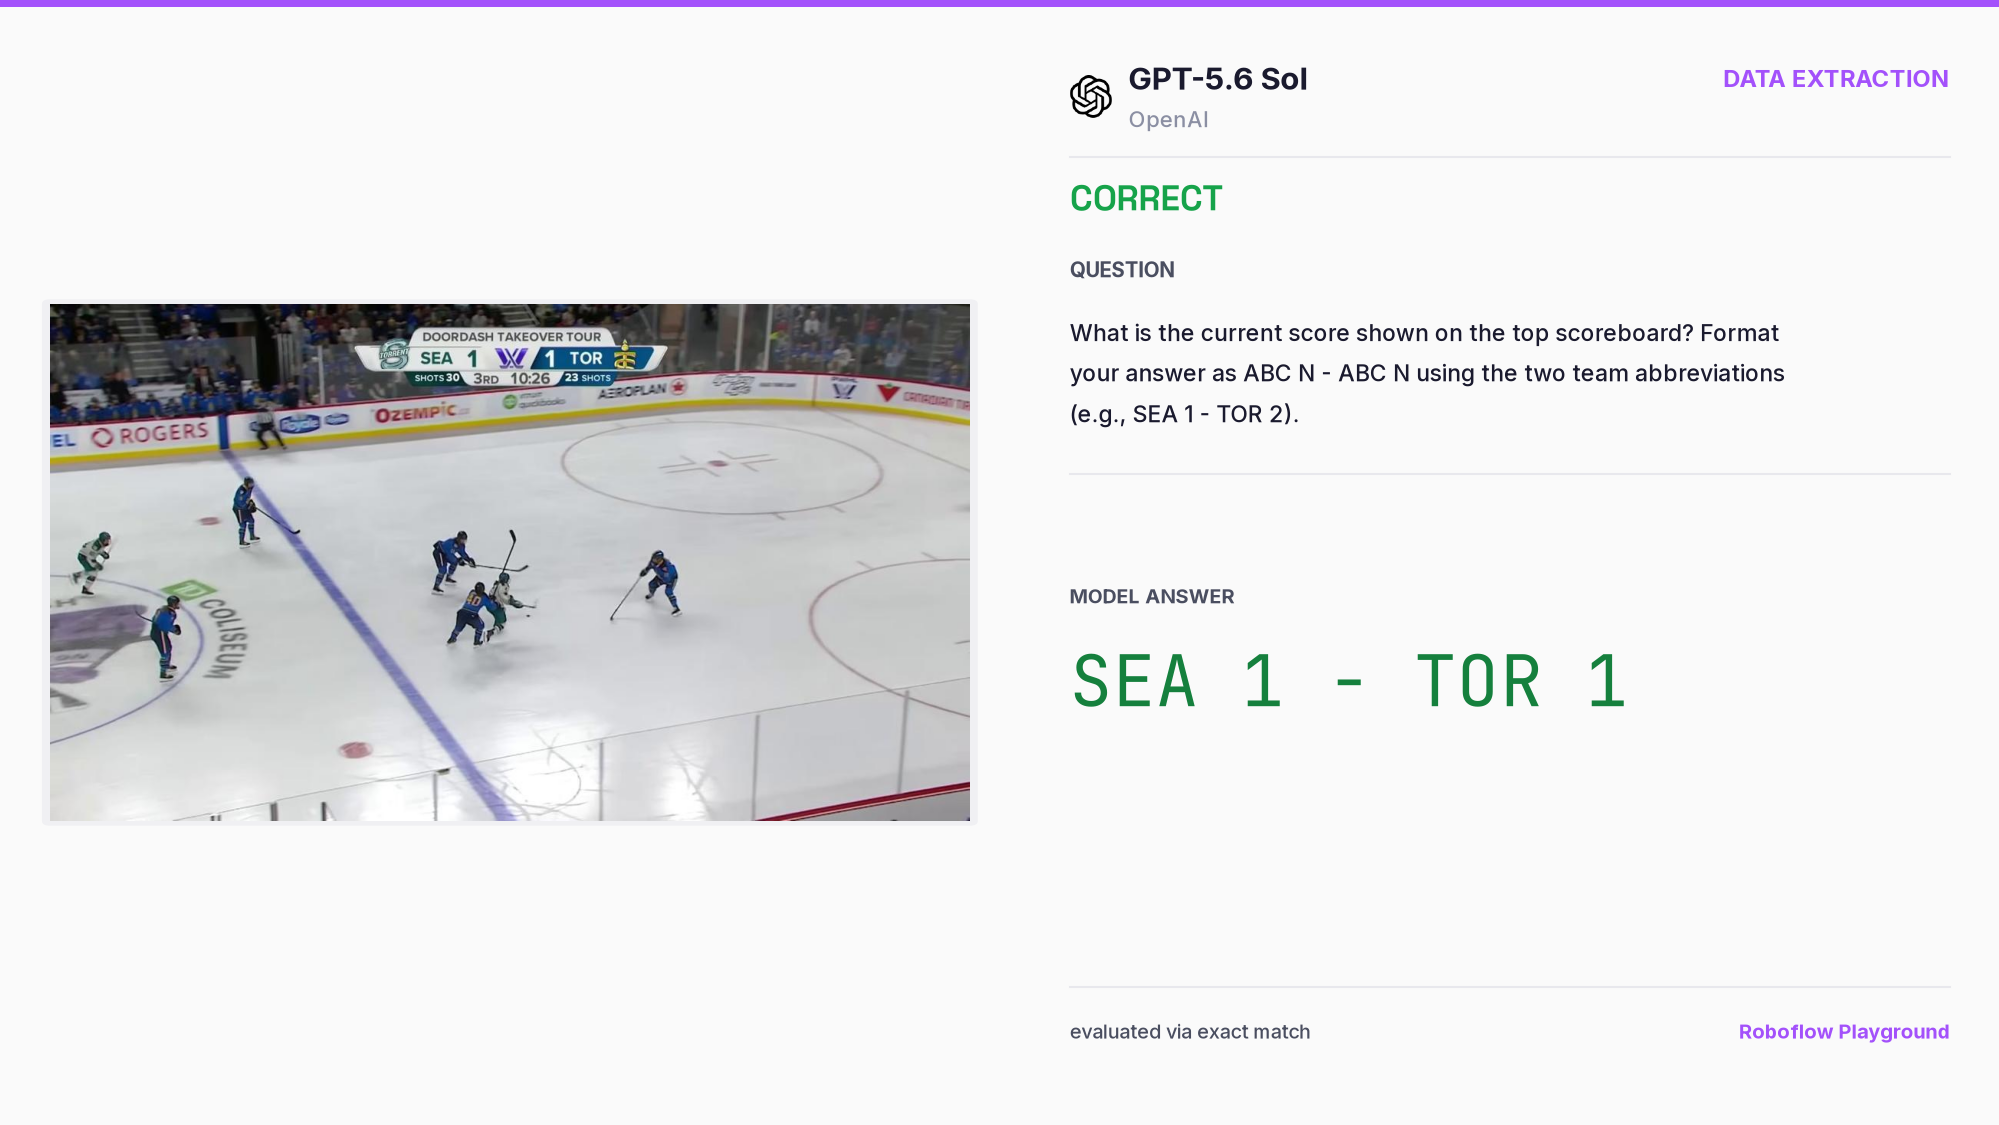
Sol performed well on text embedded in complex visual scenes. It read a tire size sequence printed along the curved surface of a dirty, worn tire. In another example, it extracted the live score from a hockey broadcast and returned the answer in the requested format, testing both visual reading and instruction following.
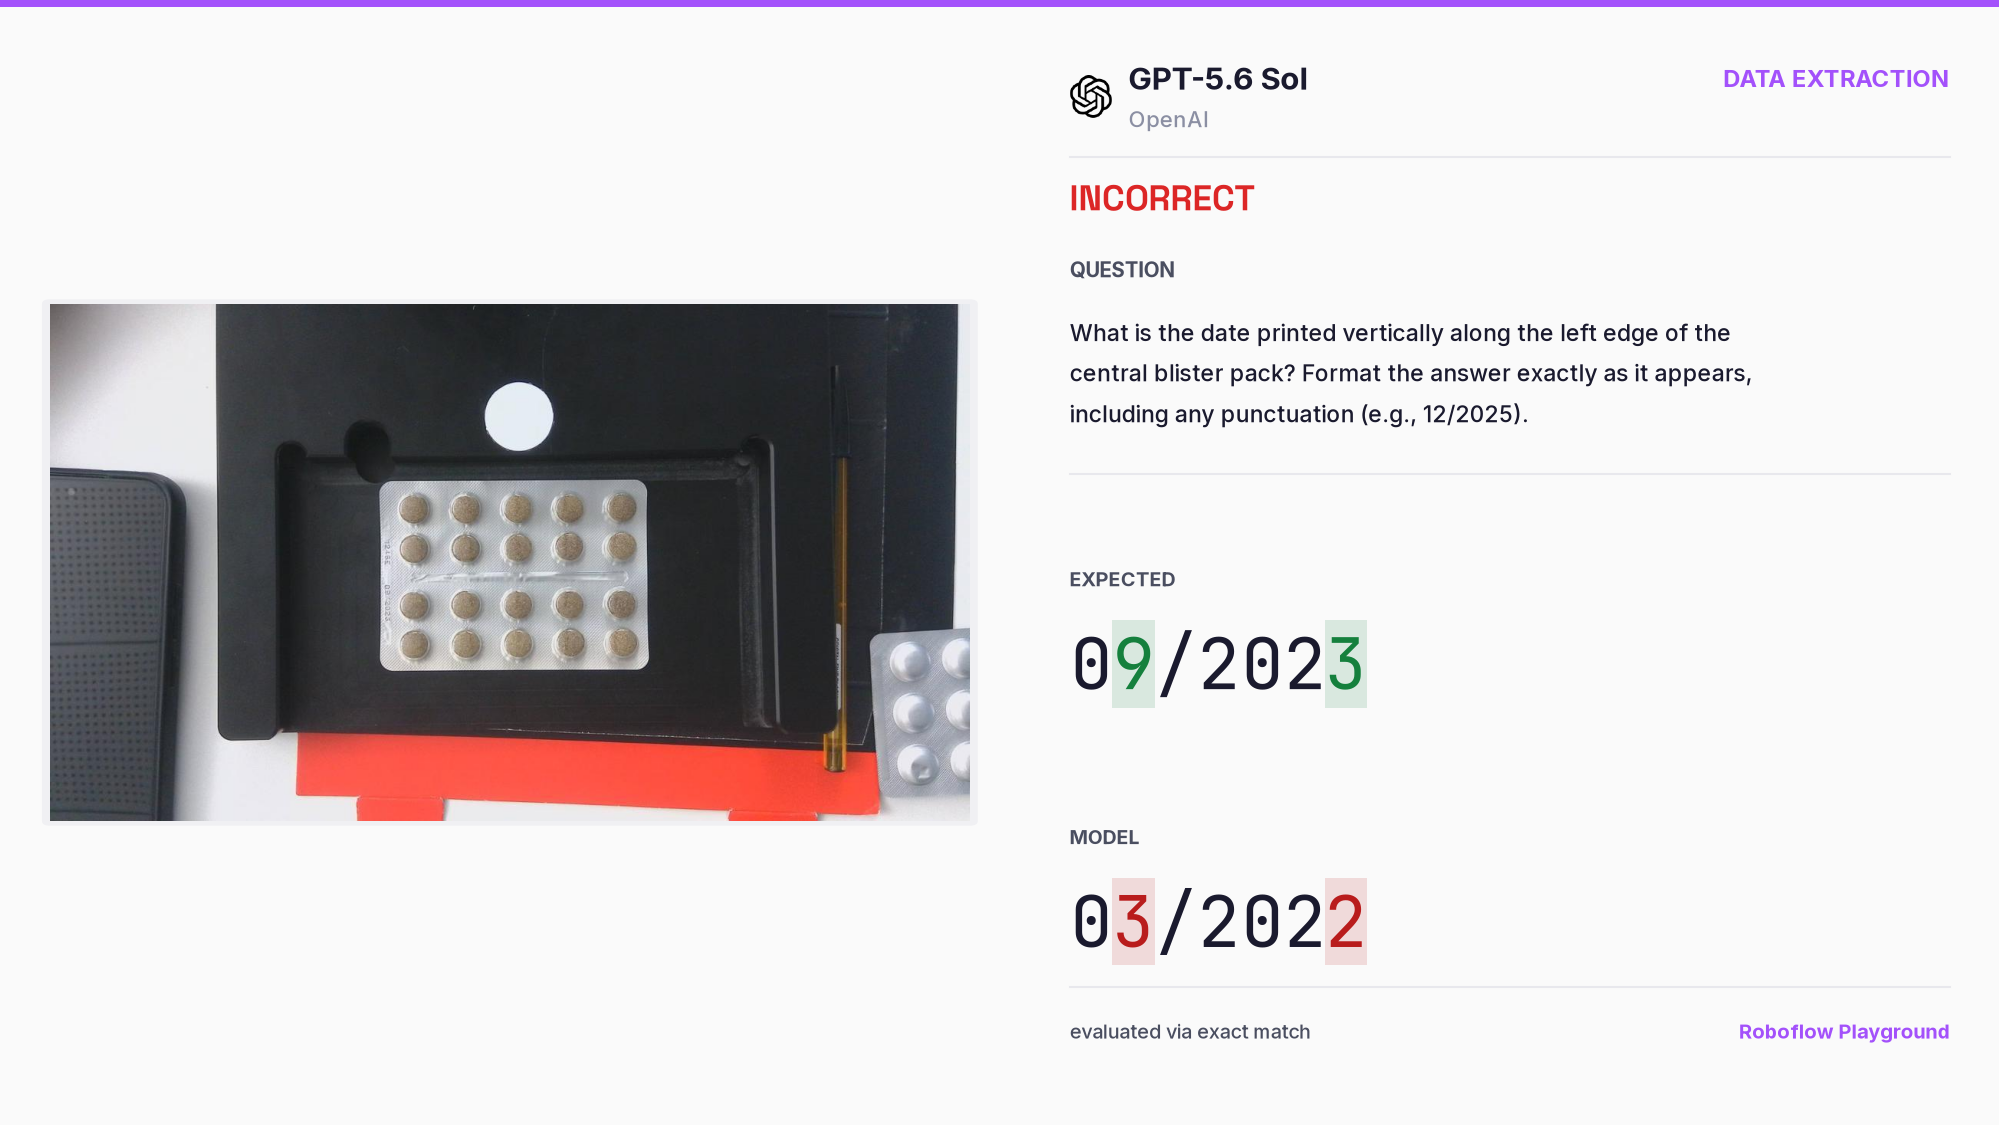
Some simple-looking extraction tasks still failed. Sol could not read the expiration date printed on a blister pack. The text was small, vertical, low contrast, and affected by reflections, which may explain the error.
Trade-offs
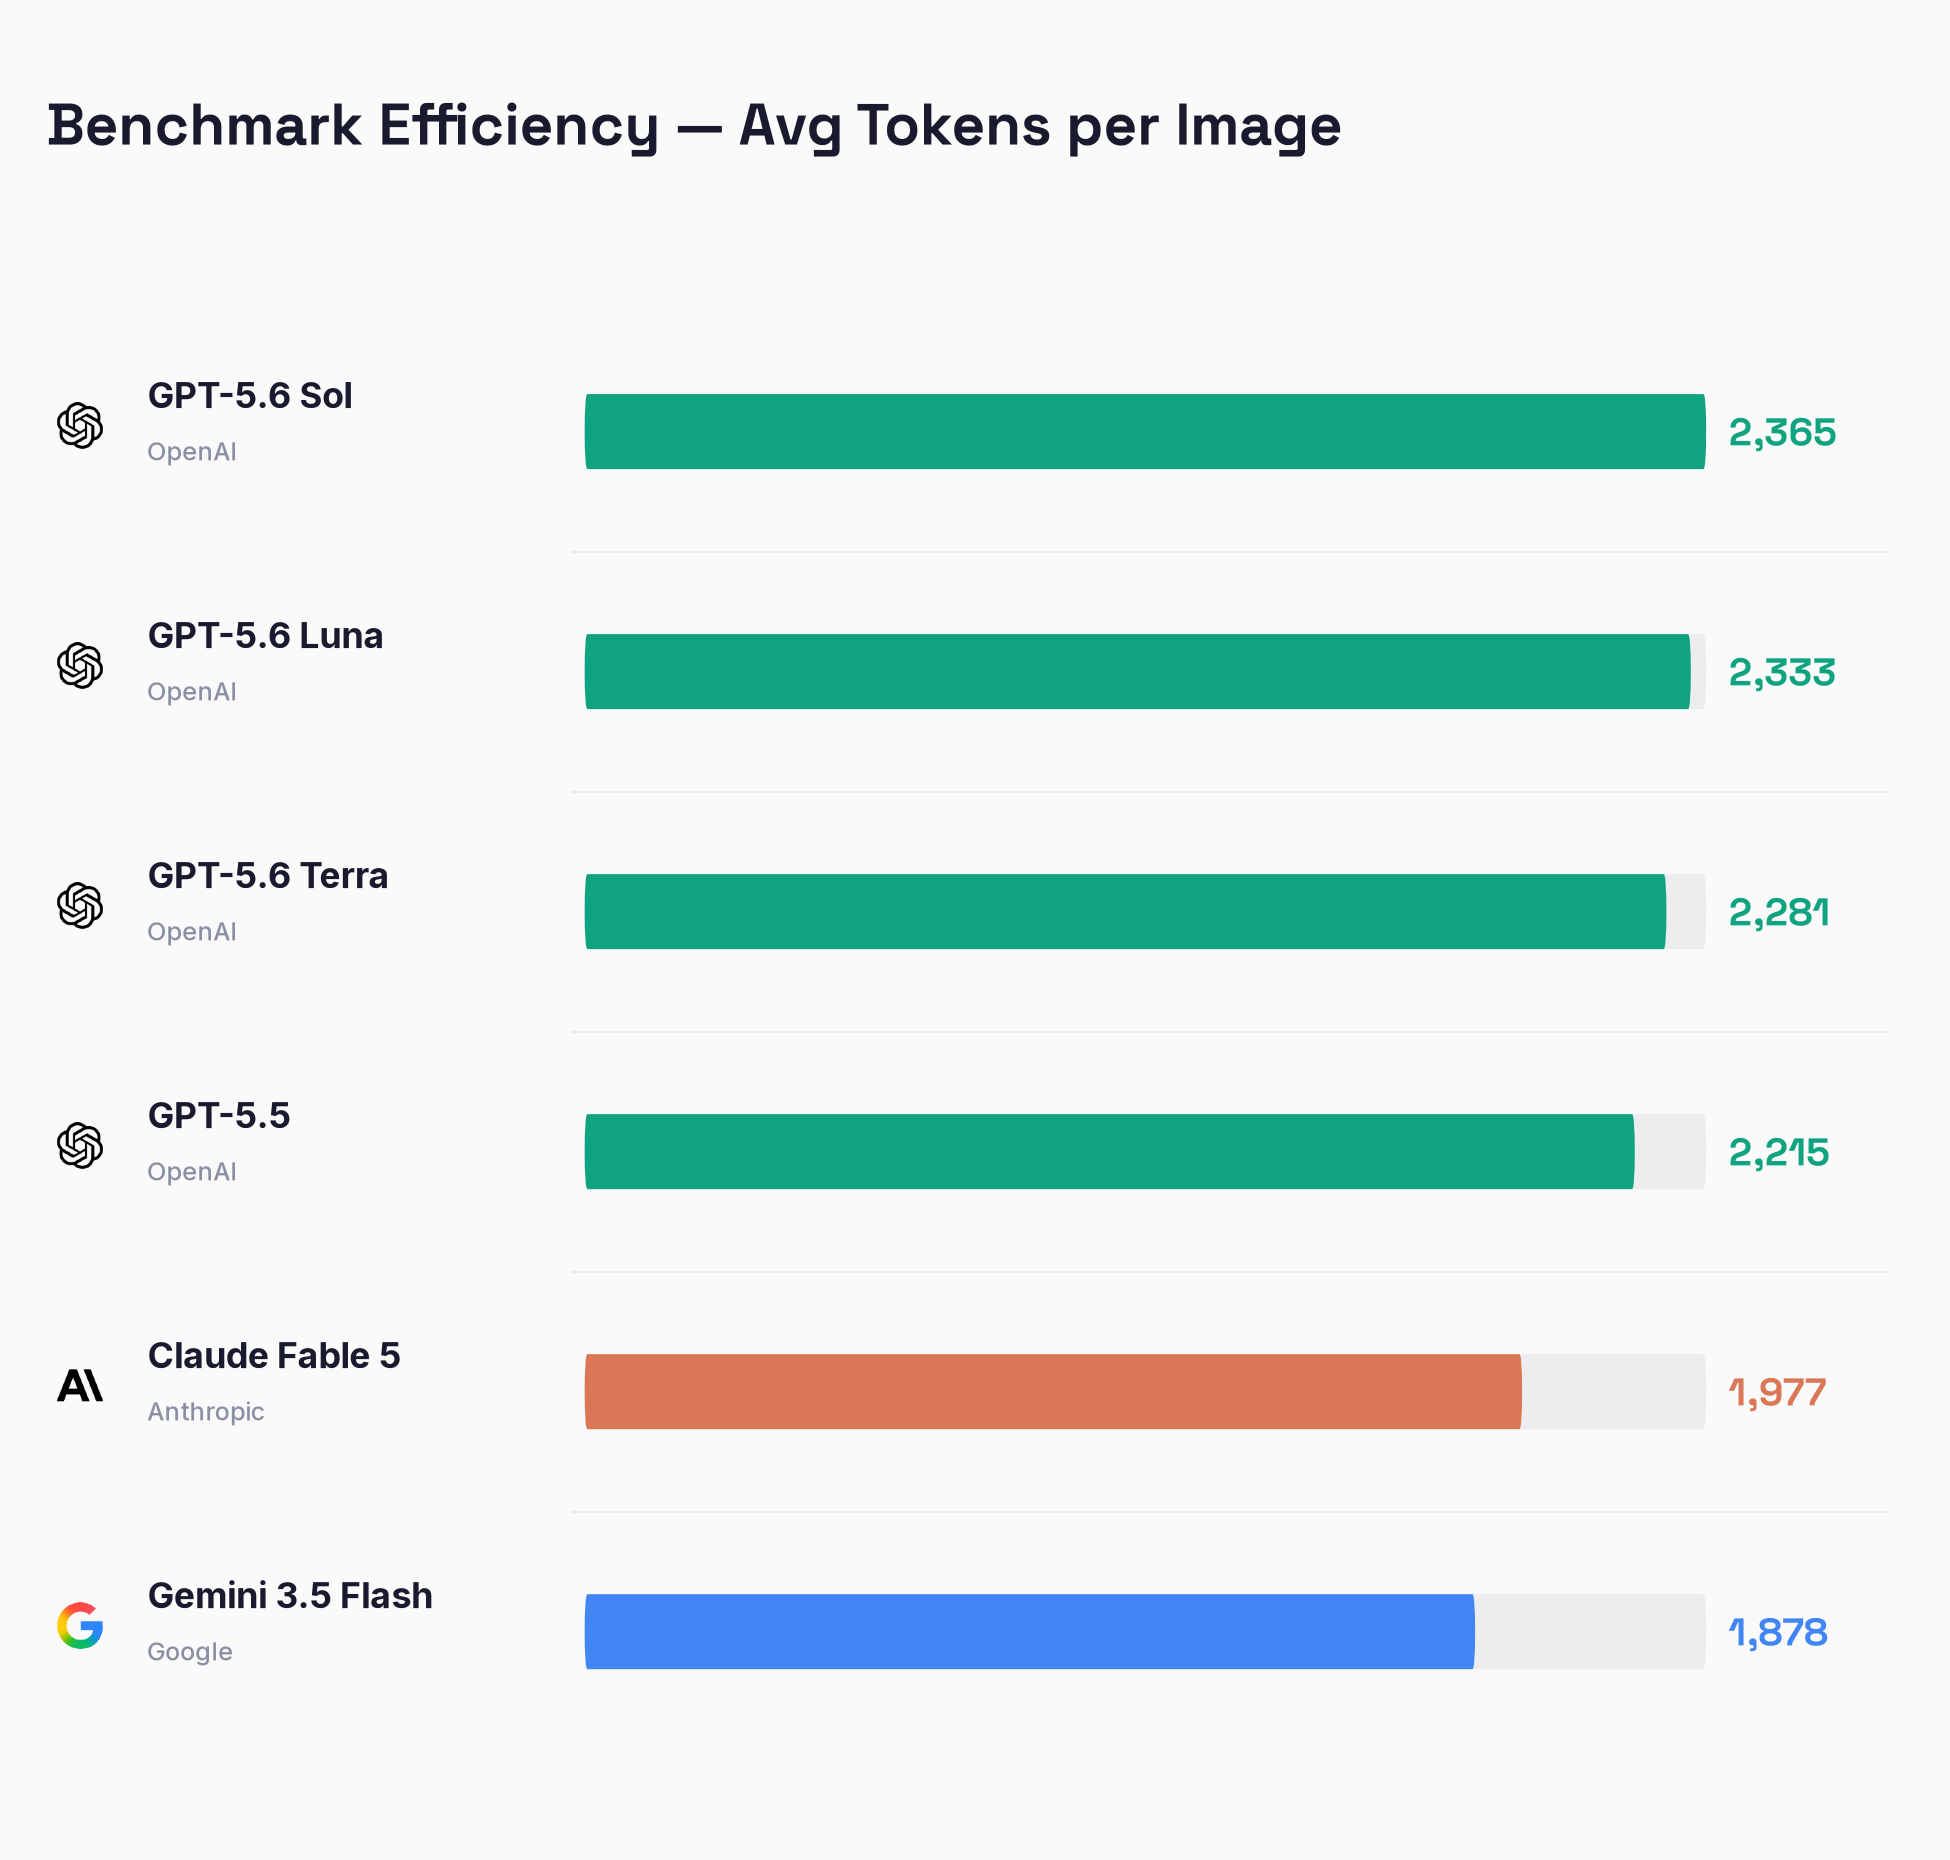
The vision gains come with higher token usage across the GPT-5.6 lineup. The difference matters less in small tests, but becomes more important at scale, where token volume directly increases processing costs.
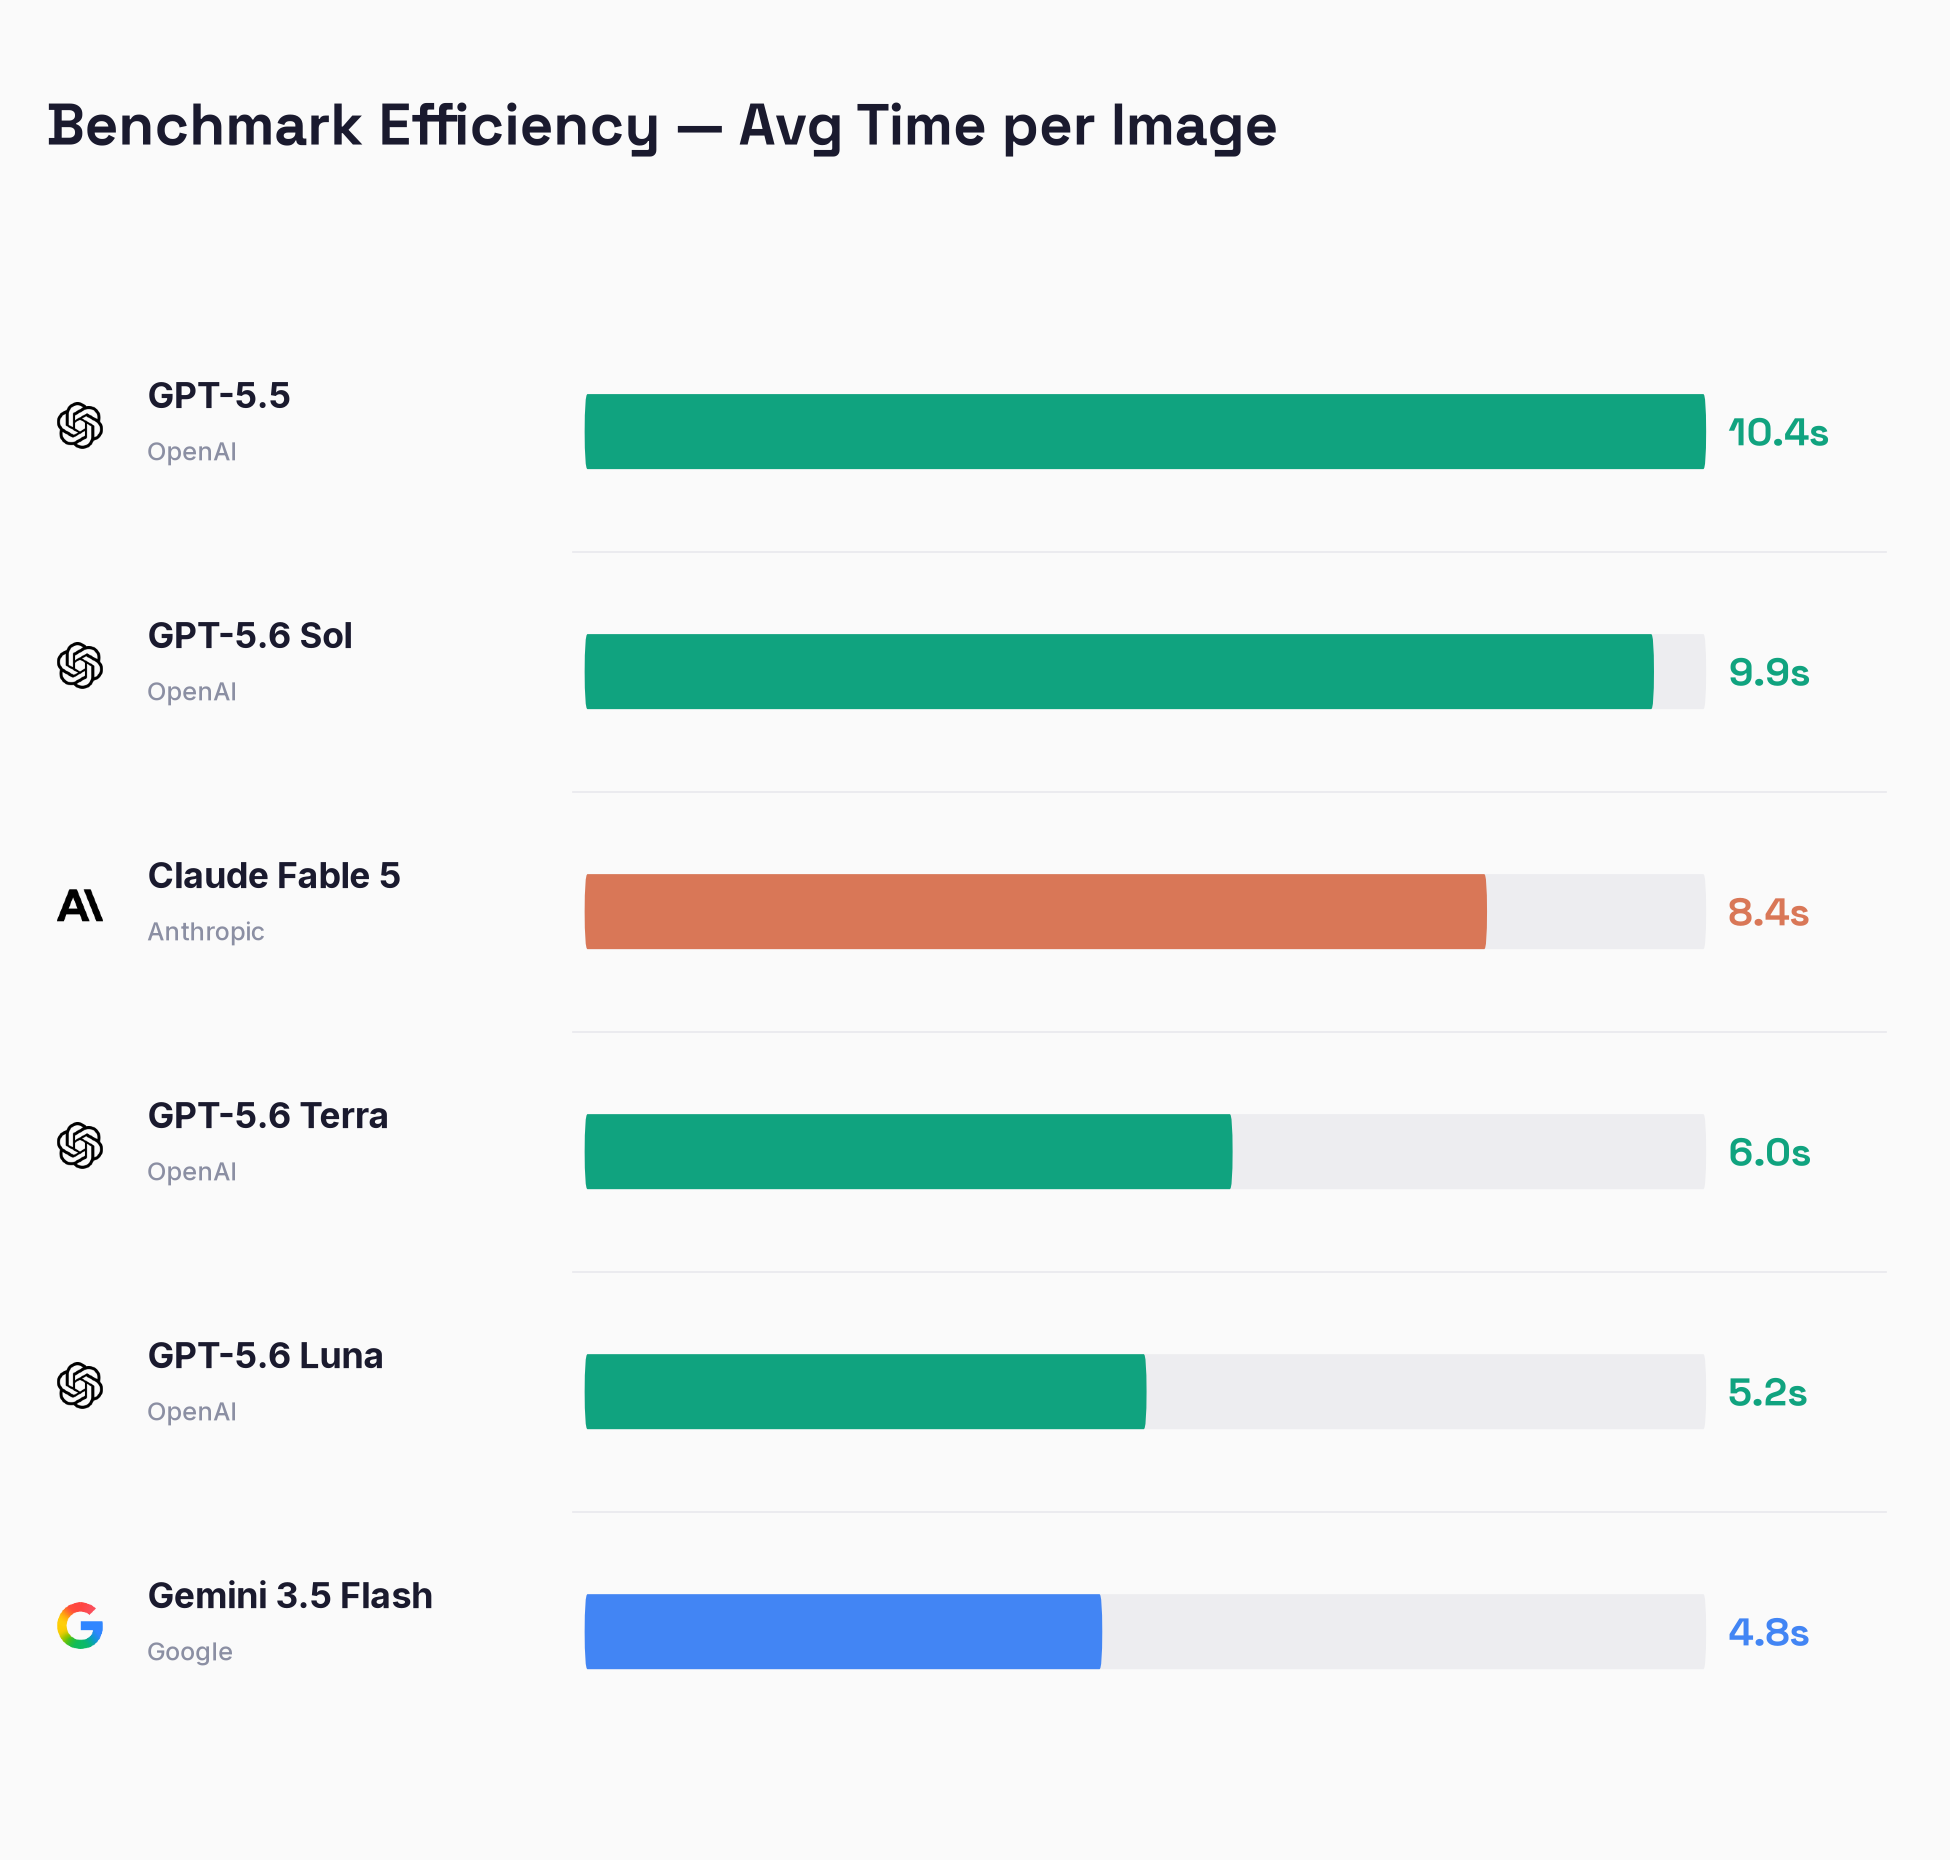
Sol averaged close to 10 seconds per image in our benchmark. Terra reduced that to around 6 seconds, while Luna finished in slightly over 5 seconds. Luna offers the strongest latency-quality balance in the lineup, with speed close to Gemini 3.5 Flash while still outperforming GPT-5.5 on detection and counting.
In our benchmark, Sol cost roughly 2.5 cents per image, making it the second most expensive model after Claude Fable 5. Terra reduced the average cost to about 1 cent per image, while Luna cost less than 0.5 cents.
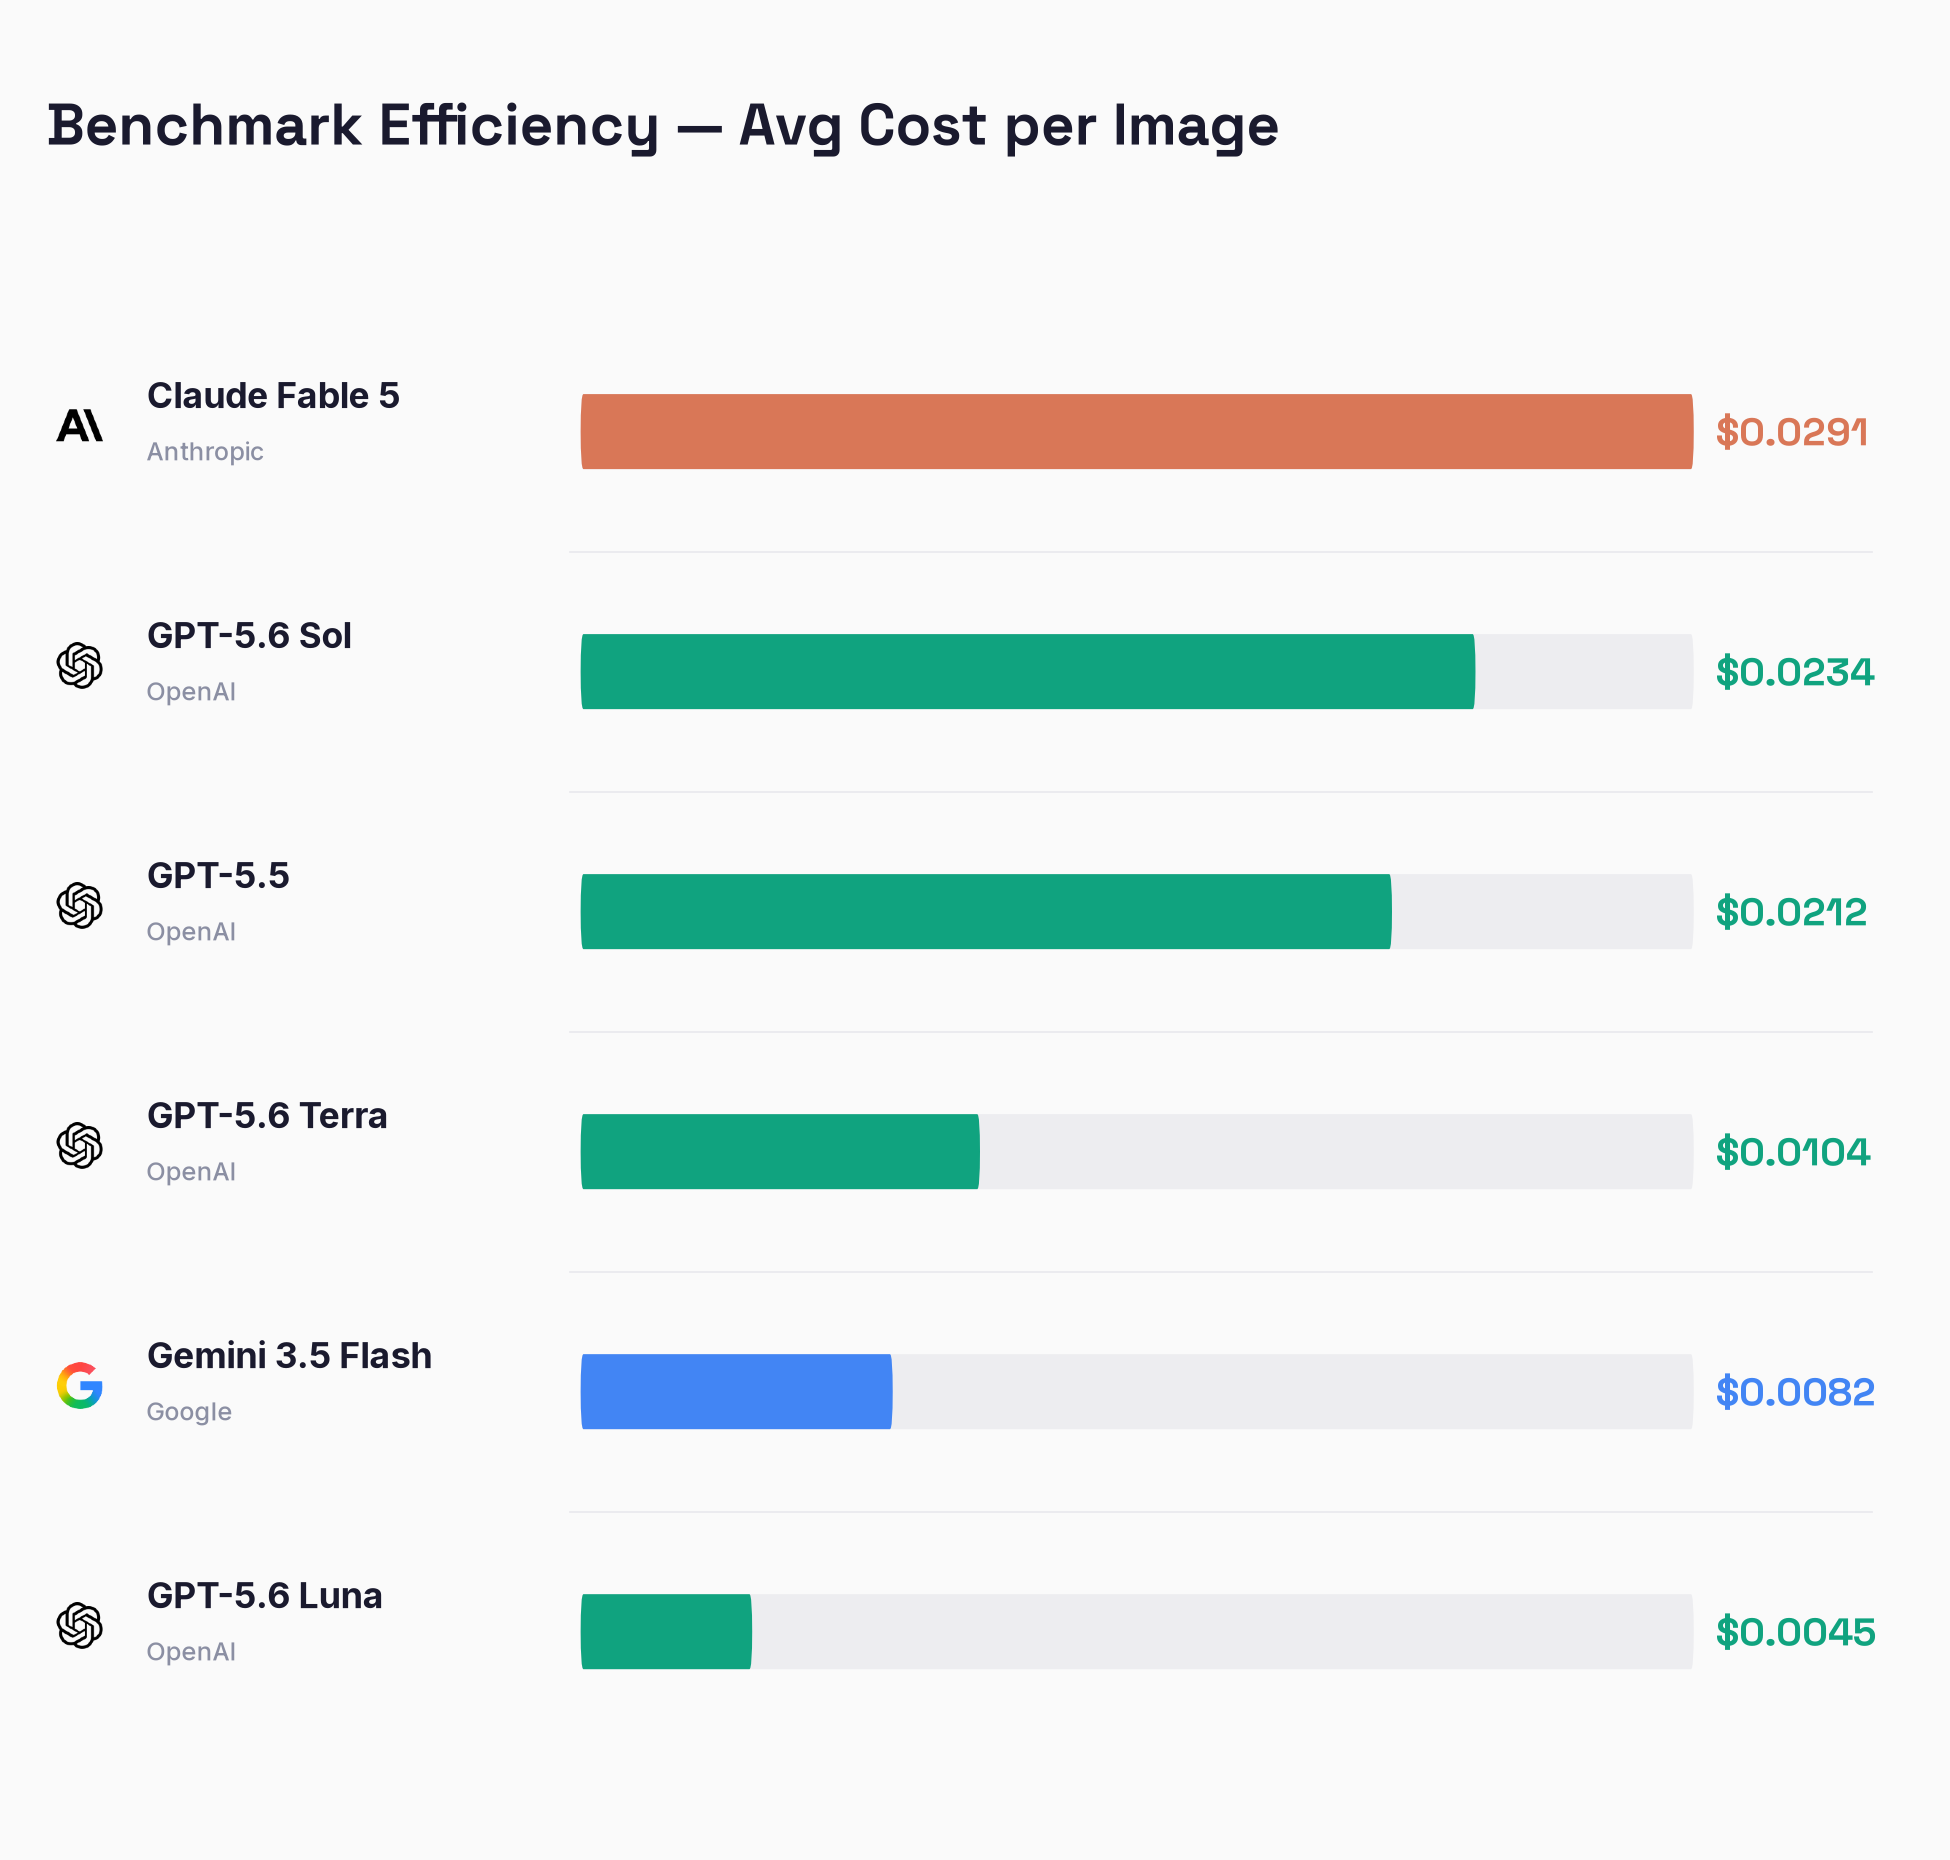
At 0.8 cents per image, Gemini 3.5 Flash is much cheaper than Sol while still leading our detection and counting benchmarks. This makes it a strong option for data-intensive workloads where cost scales across large image batches. Roboflow Playground lets you test Sol, Terra, and Luna alongside Claude Fable 5, Gemini 3.5 Flash, and other VLMs on the same tasks.
Takeaways
With GPT-5.6, OpenAI is much closer to the leading VLMs than before. Detection moved from a weak point to a usable capability, and counting improved across the full model family.
There are still clear limits. Gemini 3.5 Flash remains a better practical choice for high-volume detection and counting in our benchmark, especially at its price.
GPT-5.6 shows OpenAI is now taking vision much more seriously. Sol still has flaws, especially around cost, latency, and some unstable detection cases, but the progress is hard to ignore. For agents, screen understanding, document workflows, and visual reasoning, this release makes OpenAI a much stronger option than before.