AI has made code cheap, and as a result many companies are building bigger tools in pursuit of better performance. Larger prompts, more orchestration, more layers, more complexity. This also makes these tools intrinsically more expensive to use. Pi takes the opposite approach.
Pi is the coding harness that chooses minimalism on purpose. It comes out of the box with only 4 tools, and its system prompt and tool definitions come in below 1,000 tokens. The idea being that most work can be done with the basics, and if you want more, build it.
Evidence increasingly suggests that Pi’s design is not just cleaner; it’s cheaper and more performant. Users are finding that vanilla Pi produces industry leading results, even before adding on extensions to match user specific workflows and needs. As we'll see in case studies of Databricks and Shopify, Pi produced ideal outcomes for both.
Case Studies
Databricks Study: Cost Per Task
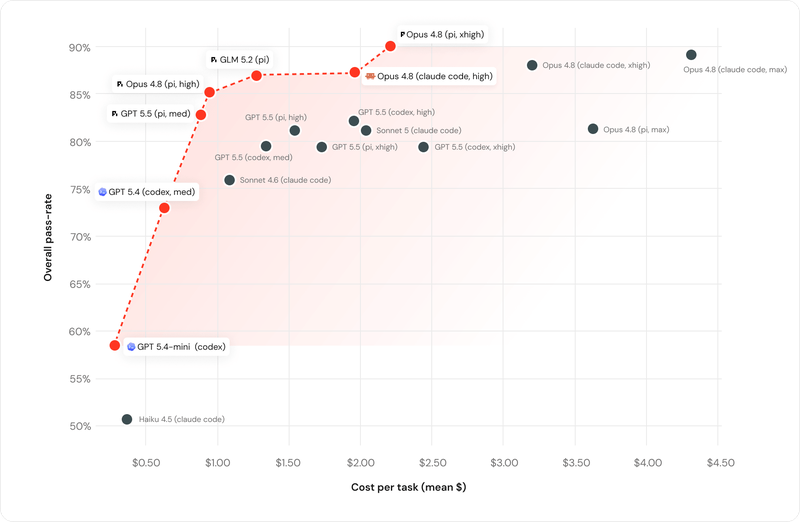
Databricks recently shared their findings “Benchmarking Coding Agents on Databricks’ Multi-Million Line Codebase.” The goal of their research was to understand which coding agents offer the best performance on real-world coding tasks, and how task-performance varies with price.
To avoid bias from external benchmarks that have become oversaturated, they created their own based on tasks their team of engineers regularly performs. The results match what we would expect, but what many in the industry may have been surprised to learn. In their words, “...the harness a model is called from dramatically impacts cost and quality,” and, “in many cases, simple harnesses like Pi performed best on our workloads.”

When combined with Opus 4.8, xhigh, Pi had the highest overall pass-rate, at a significantly lower cost than both Claude Code and Codex.
Minimal harness, measurable effect
Pi shines because it doesn’t try to wrap the model in a bunch of defaults and instructions that get lost in the instruction hierarchy. Instead, Pi stays out of the model’s way, and the team is able to add what they actually need for their workflow.
Databricks’ study is insightful because it separates model from harness.
They reported that when they ran the same model with the same thinking effort through different harnesses, “the cost per task differed significantly (more than 2x in some cases), while quality remained the same”. We call this Pi’s “context discipline”. “Pi sent about 3x less context per turn. It managed context better, keeping a tighter working set and finishing the tasks in fewer runs.”
We agree that one must take into account end-to-end engineering economics, and not just price per token. And this is also true at the model level; we have observed, for instance, that running complex workflows on Haiku 4.5 was often more expensive than Sonnet 4.6, especially when code execution was involved, simply because the agent required more turns to complete the task successfully.
Now we see this at the harness level too; stronger, more expensive models with a performant harness can be cheaper than the converse.
Shopify builds Pi Autoresearch: Extensible beats bloat
Minimalism is part of Pi’s core philosophy. What makes this work is that minimal does not mean inflexible. In fact, it is the first widely used agentic infrastructure created for extensibility and self-editability.
Another insightful external validation of Pi’s design comes from Shopify. In this post from Shopify Engineering, David Cortés describes building pi-autoresearch directly as a Pi extension, by simply asking “Pi, [to] create an extension for Autoresearch...”. Pi reads its own extension documentation and starts building a new workflow from there.
Autoresearch is an autonomous loop for optimization with coding agents. When you ask for a change, it runs experiments to find out what works and what causes regressions. For as long as the target is measurable, it can throw out these regressions and keep self-improving.
For Shopify and others, the Autoresearch extension quickly became a serious internal productivity tool. Shopify reported cases including unit tests running “300 times faster,” React component mounting “20% faster,” reduced build times across multiple projects, and even improvements to pnpm performance.

The important point here is that Pi doesn’t ship any of these tools out of the box. Instead, it makes it ridiculously simple for you to build them. Instead of assuming the vendor knows your workflow and trying to ship every tool under the sun, Pi assumes you know best, and gifts you extensibility to wield and craft your own workflow.
Why minimal wins now
About a year ago, an argument could be made for native harnesses having a structural advantage over all others, because models were built around them. However, this argument has gotten weaker.
Frontier models are now generally very competent at understanding a terminal (or terminal-style) coding environment, and acting within it. Anthropic recently cutting down Claude Code’s system prompt by 80% is a clear sign of this. So the question is becoming less about how native the harness is, and more about how it handles context to avoid redundancy and act with clean primitives. Models need a clean interface to the environment, and a harness that does not waste context.
Pi provides this: less prompt overhead and repeated context, cheaper runs, fewer unnecessary abstractions. Because it is extensible, you do not lose power, but gain selectivity. You add complexity only when it “earns its keep”.
We are also seeing local models developing fast, and at Earendil we find them very promising. Pi’s context discipline is especially an asset here. Local models usually have lower context windows, and prefill can take a long time, so preserving a stable prompt prefix matters. Context discipline means we do not change the context without the user explicitly asking for it, avoiding minute-long re-prefilling. Combined with the minimal default system prompt and tool set, this makes pi an ideal harness for local models.
Pi is proving that it can manage it all. To be cheaper, minimal, and more performant.